
agentscope-ai / PawBench
A benchmark for evaluating LLM × harness performance.
Why this job: says: benchmark; topics: benchmark
What it does
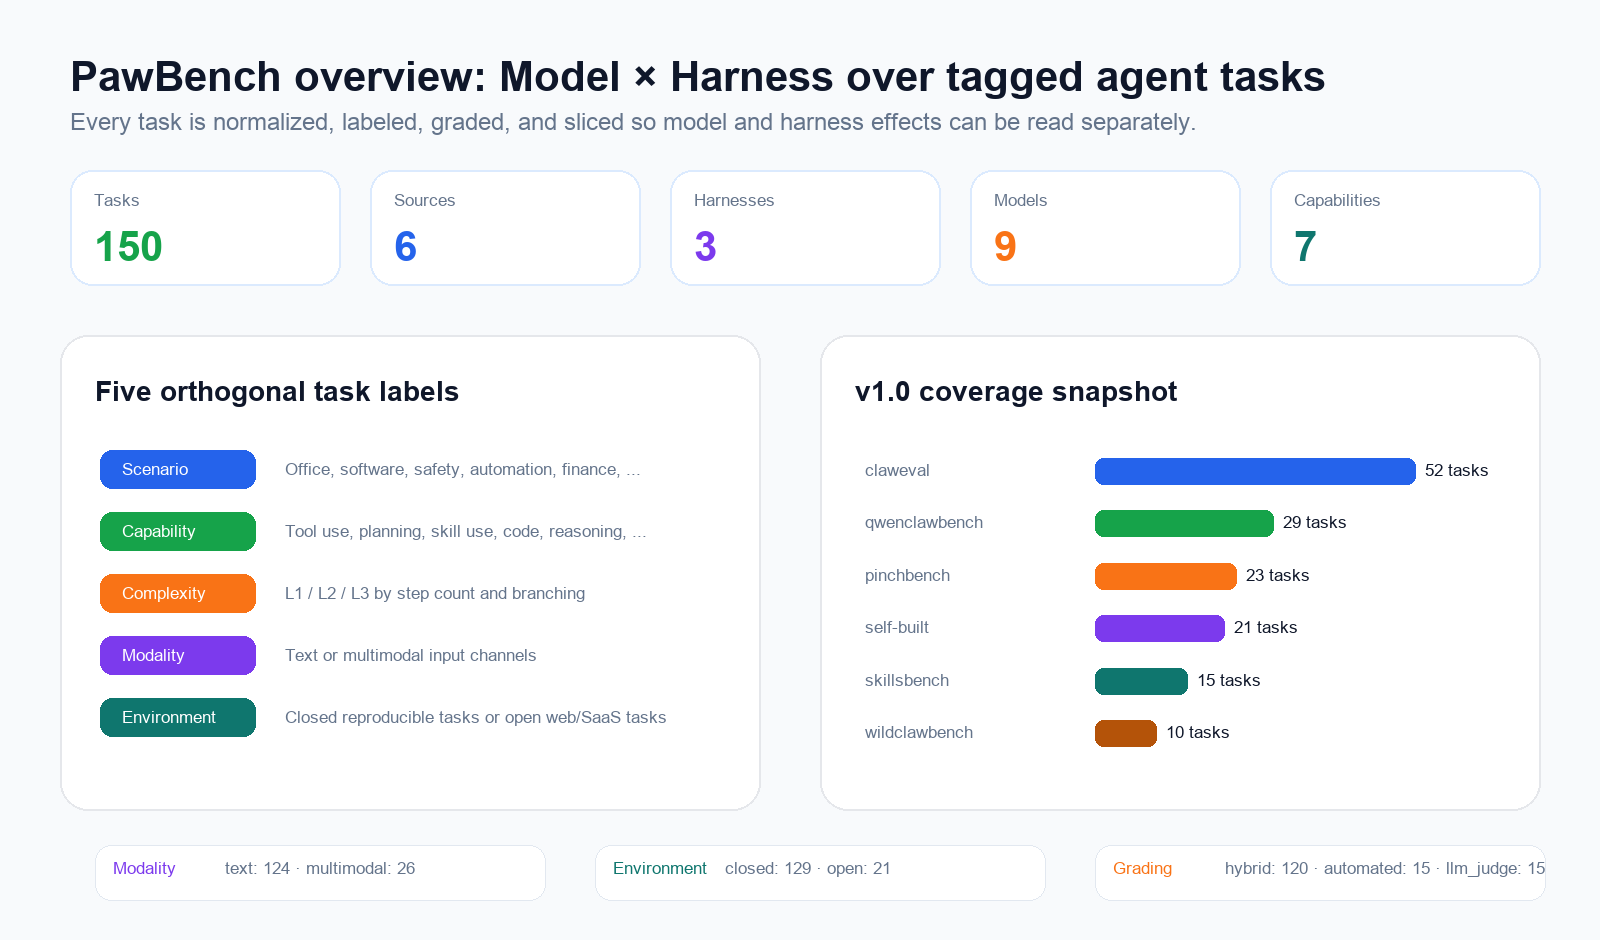
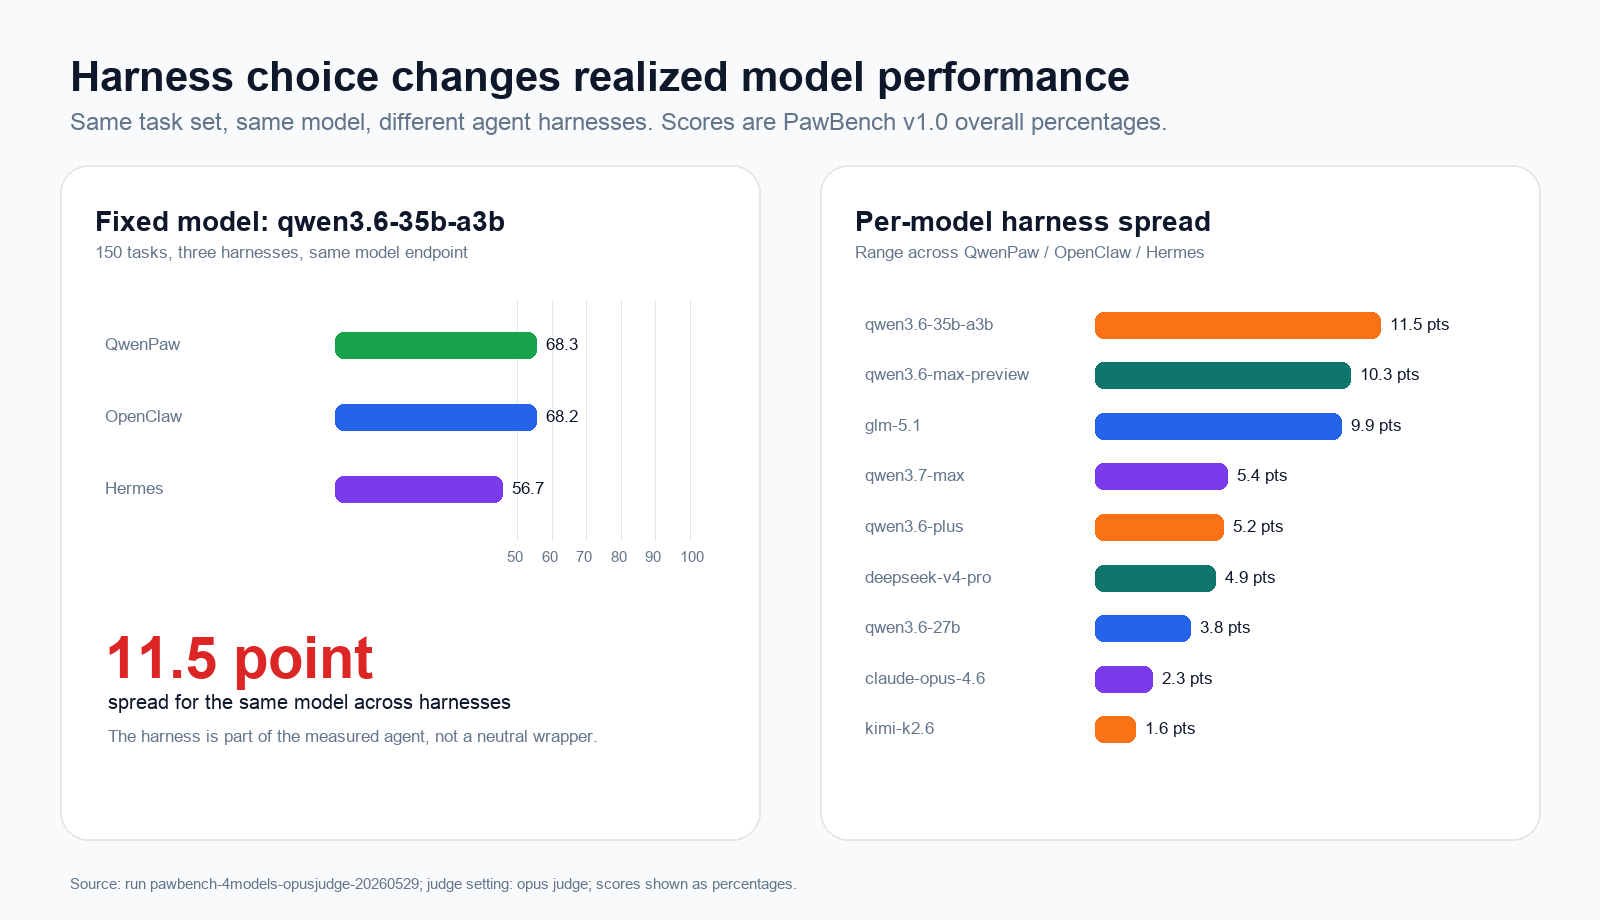
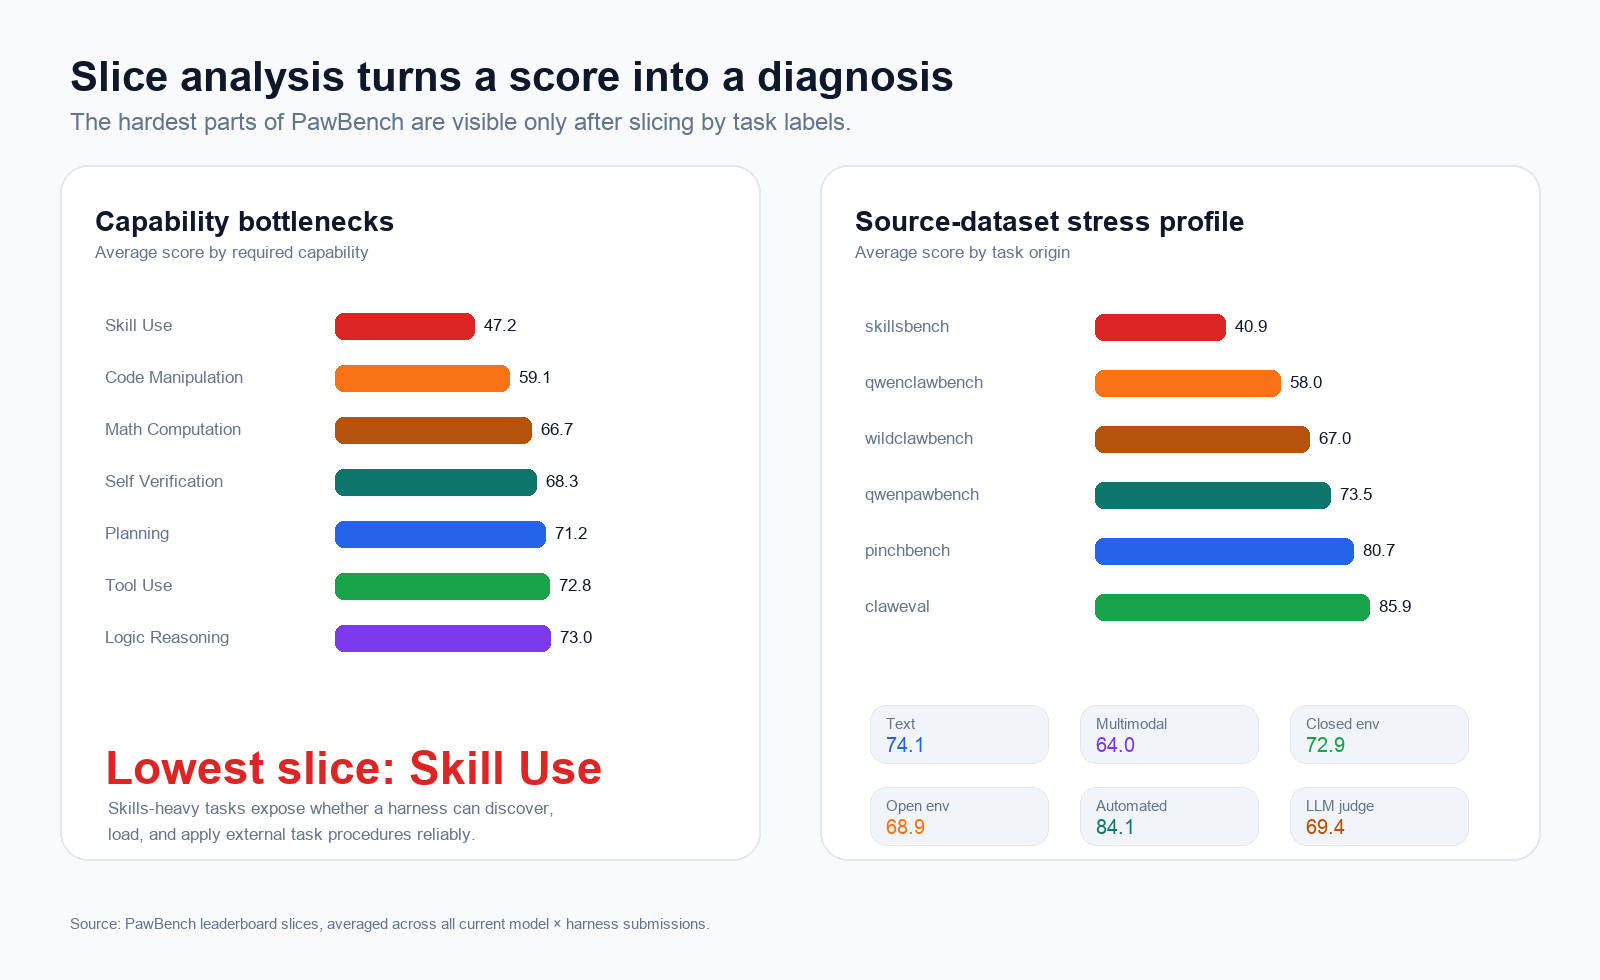
The same model can behave very differently once it is placed inside a real agent runtime. A failure may come from model reasoning, missing tools, weak skill discovery, poor workspace awareness, brittle web access, or a completion check that is too loose. A single final pass rate cannot separate these causes.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 3 months ago
- Stars
- 127
- +1 this week
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 58% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 17% closed
- 5 still open
- Pull requests
- 14 merged
- 6 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| suyoumo / ClawProBench | 829 | 2 months ago | Apache-2.0 | No downloads |
| alibaba / sec-code-bench | 138 | 28 days ago | Apache-2.0 | No downloads |
| sierra-research / tau2-bench | 2,419 | 5 days ago | MIT | No downloads |
More: languages, topics and project record
Languages
- Python 58%
- HTML 18%
- PDDL 11%
- TypeScript 4%
Topics
- agent
- benchmark
- harness
- llm
- hermes
- openclaw
- qwenpaw
Project record
- JobEvals and observability
- StatusListed
- Commits64
- Forks22
- Watching1
- Stars in 28 days+9
- CreatedMay 15, 2026
- First seen by usNov 7, 2026
- CheckedNov 8, 2026