
BrowserCash / teracrawl
High-performance web crawler API optimized for LLMs. Turn any search or website into clean Markdown using remote browsers. Firecrawl alternative
Why this job: says: web crawler; topics: browser-automation, web-scraping, web-scraper, browser-agent
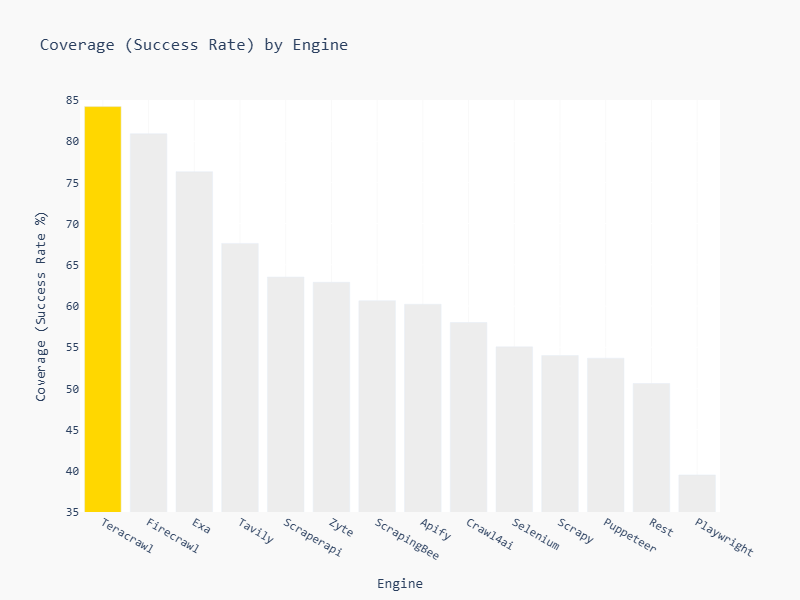
What it does
- Search + Scrape. Query Google and scrape top N results in a single API call.
- Direct Scraping. Convert any specific URL to Markdown.
- Smart Content Extraction. Automatically detects main content areas (article, main, etc.) and removes clutter (scripts, styles, navs).
- Docker Ready. Deploy anywhere with a lightweight container.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Inactive
- Last commit 11 months ago
- Stars
- 289
- On GitHub
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- v1.0.0
- Released 11 months ago
- Built with
- TypeScript
- 100% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 0% closed
- 1 still open
- Pull requests
- 0 merged
- 1 waiting
- Releases
- 1
- 1 in the last year
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| firecrawl / firecrawl | 200,979 | today | AGPL-3.0 | No downloads |
| ScrapeGraphAI / Scrapegraph-ai | 32,728 | 37 days ago | MIT | No downloads |
| fastcrw / crw | 1,244 | today | AGPL-3.0 | Mac, Linux |
More: languages, topics and project record
Languages
- TypeScript 100%
- Dockerfile <1%
Topics
- ai-agents
- ai-crawler
- ai-scraping
- ai-search
- antibot-bypass
- browser-agent
- browser-automation
- crawl4ai
- data-extraction
- firecrawl-alternative
- firecrawl-api
- firecrawl-mcp
Project record
- JobAutomation and scraping
- StatusListed
- Commits4
- Forks33
- Watching1
- Stars in 28 days+4
- CreatedOct 19, 2025
- First seen by usNov 7, 2026
- CheckedNov 8, 2026