
chiennv2000 / orthrus
[NeurIPS 2026 Spotlight] Fast, lossless LLM inference via dual-view diffusion decoding.
Why this job: says: llm inference; topics: llm-inference
What it does
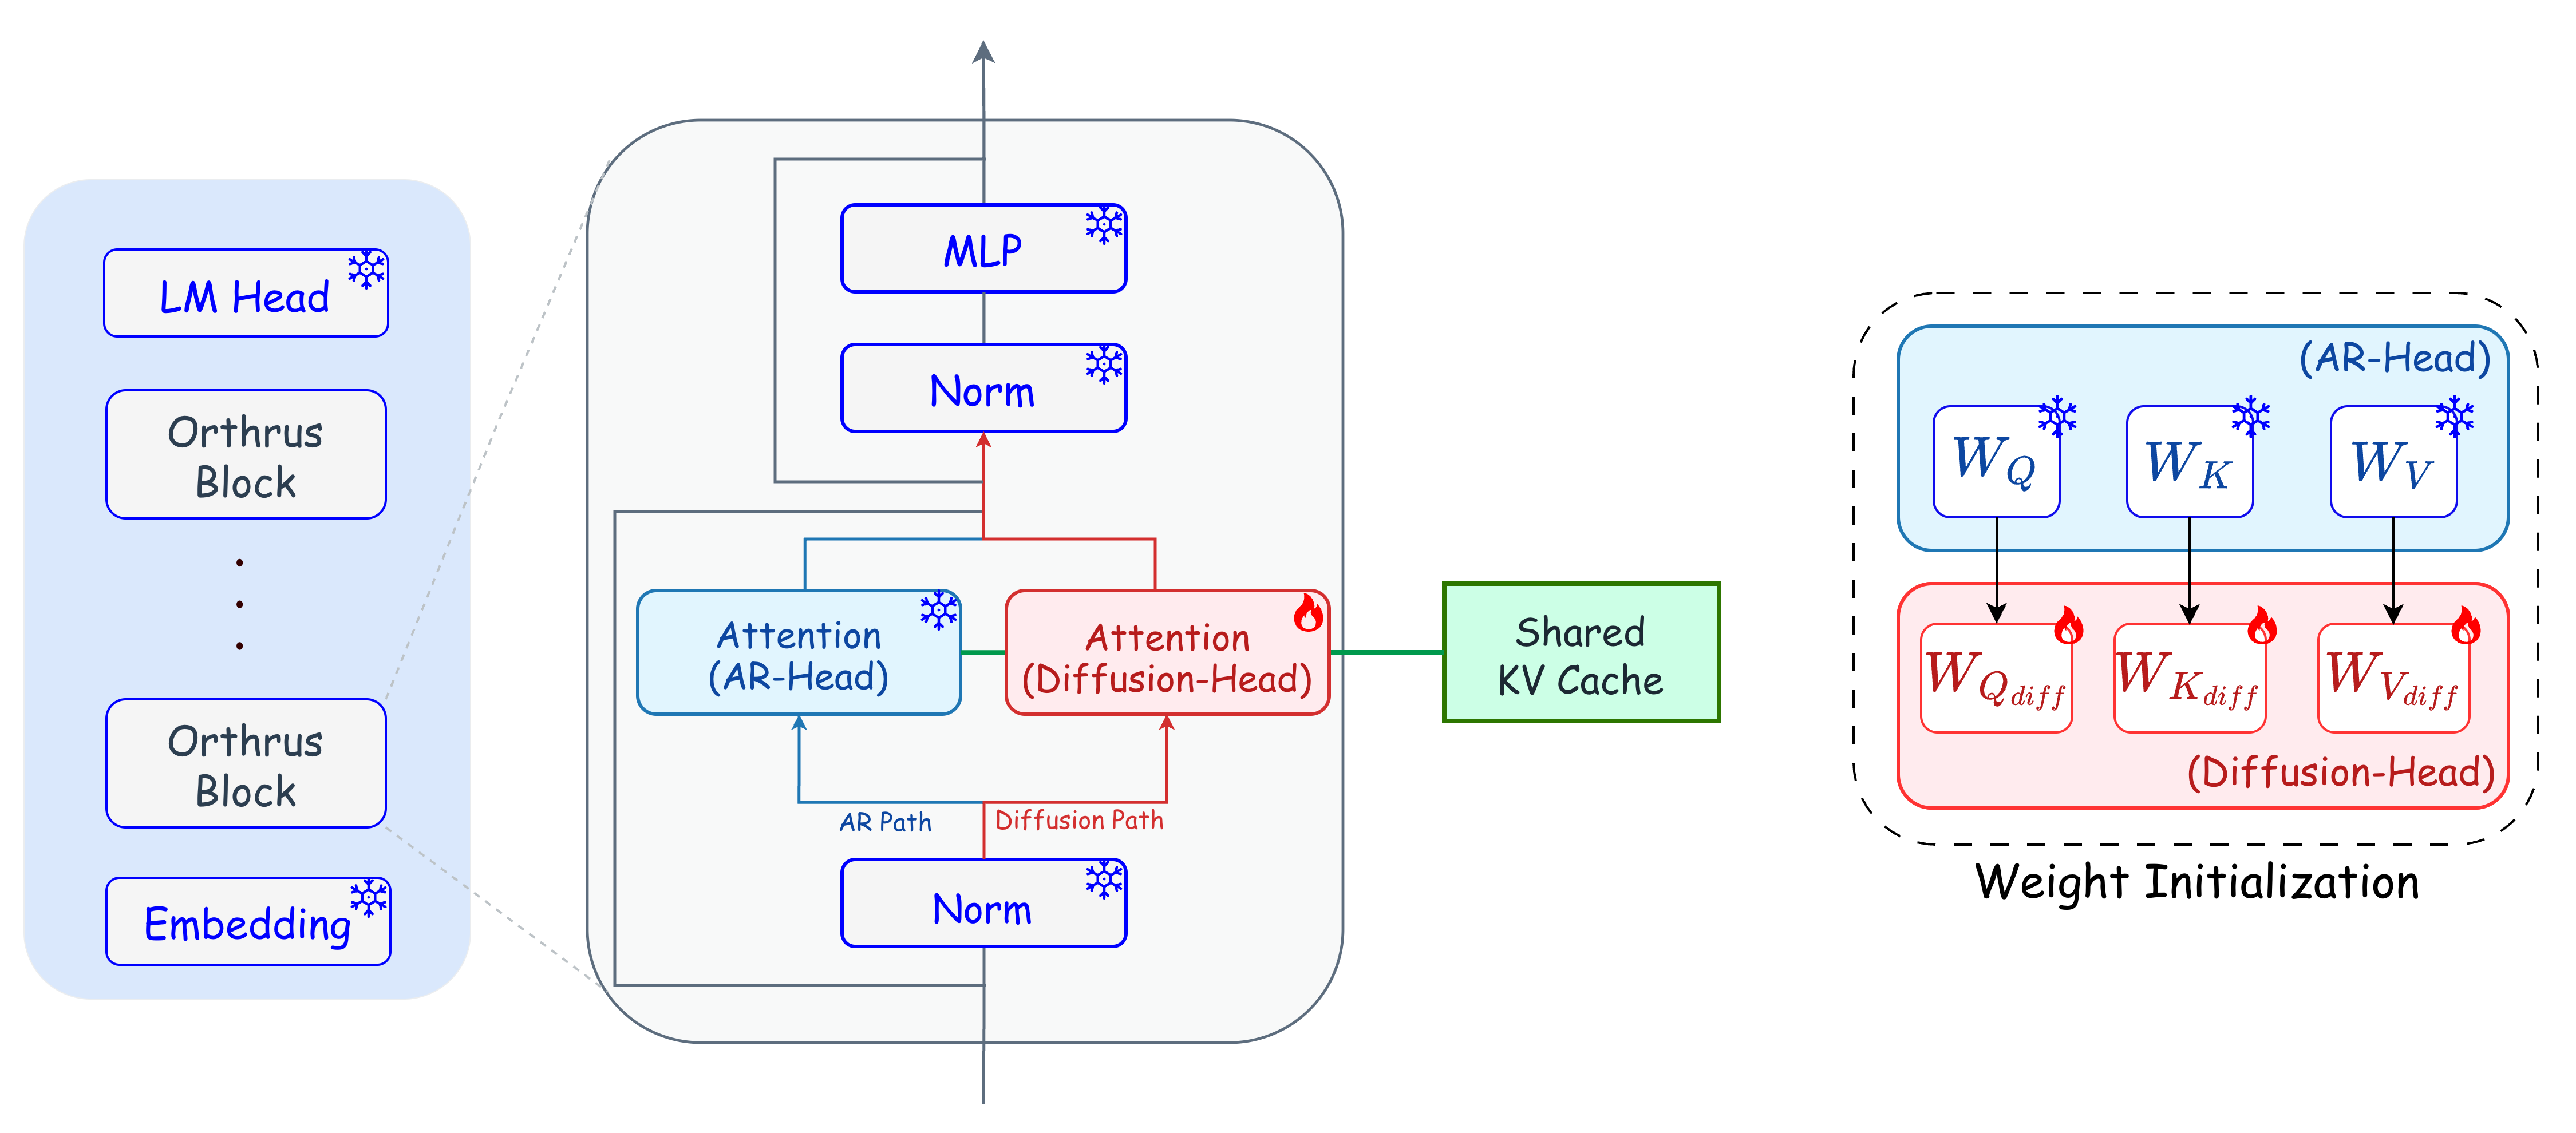
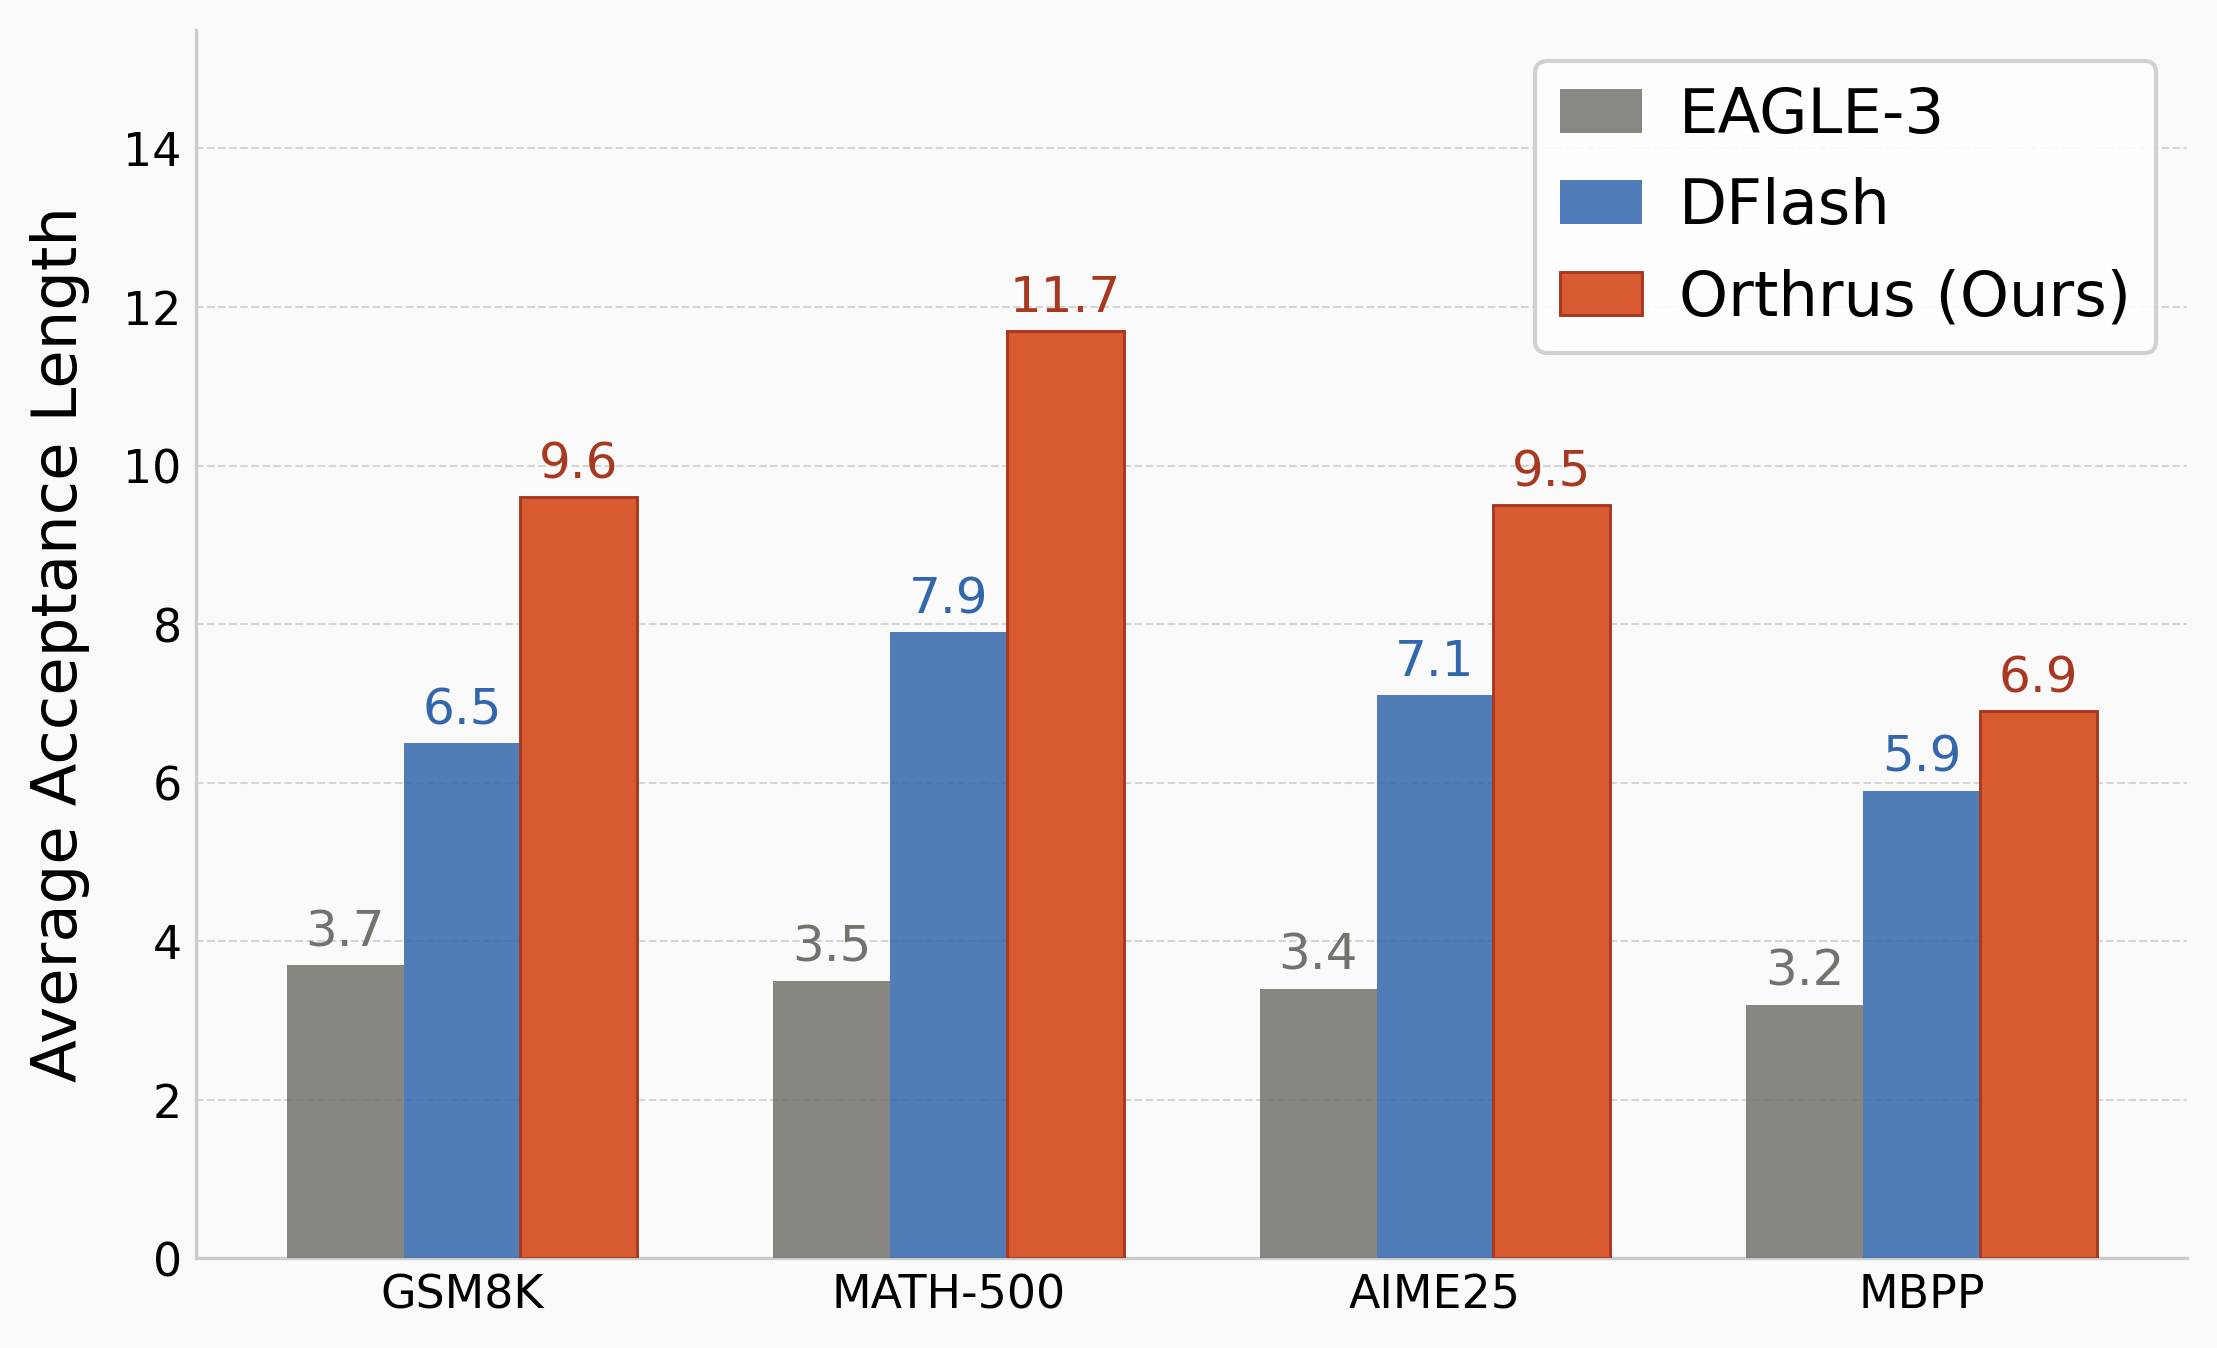
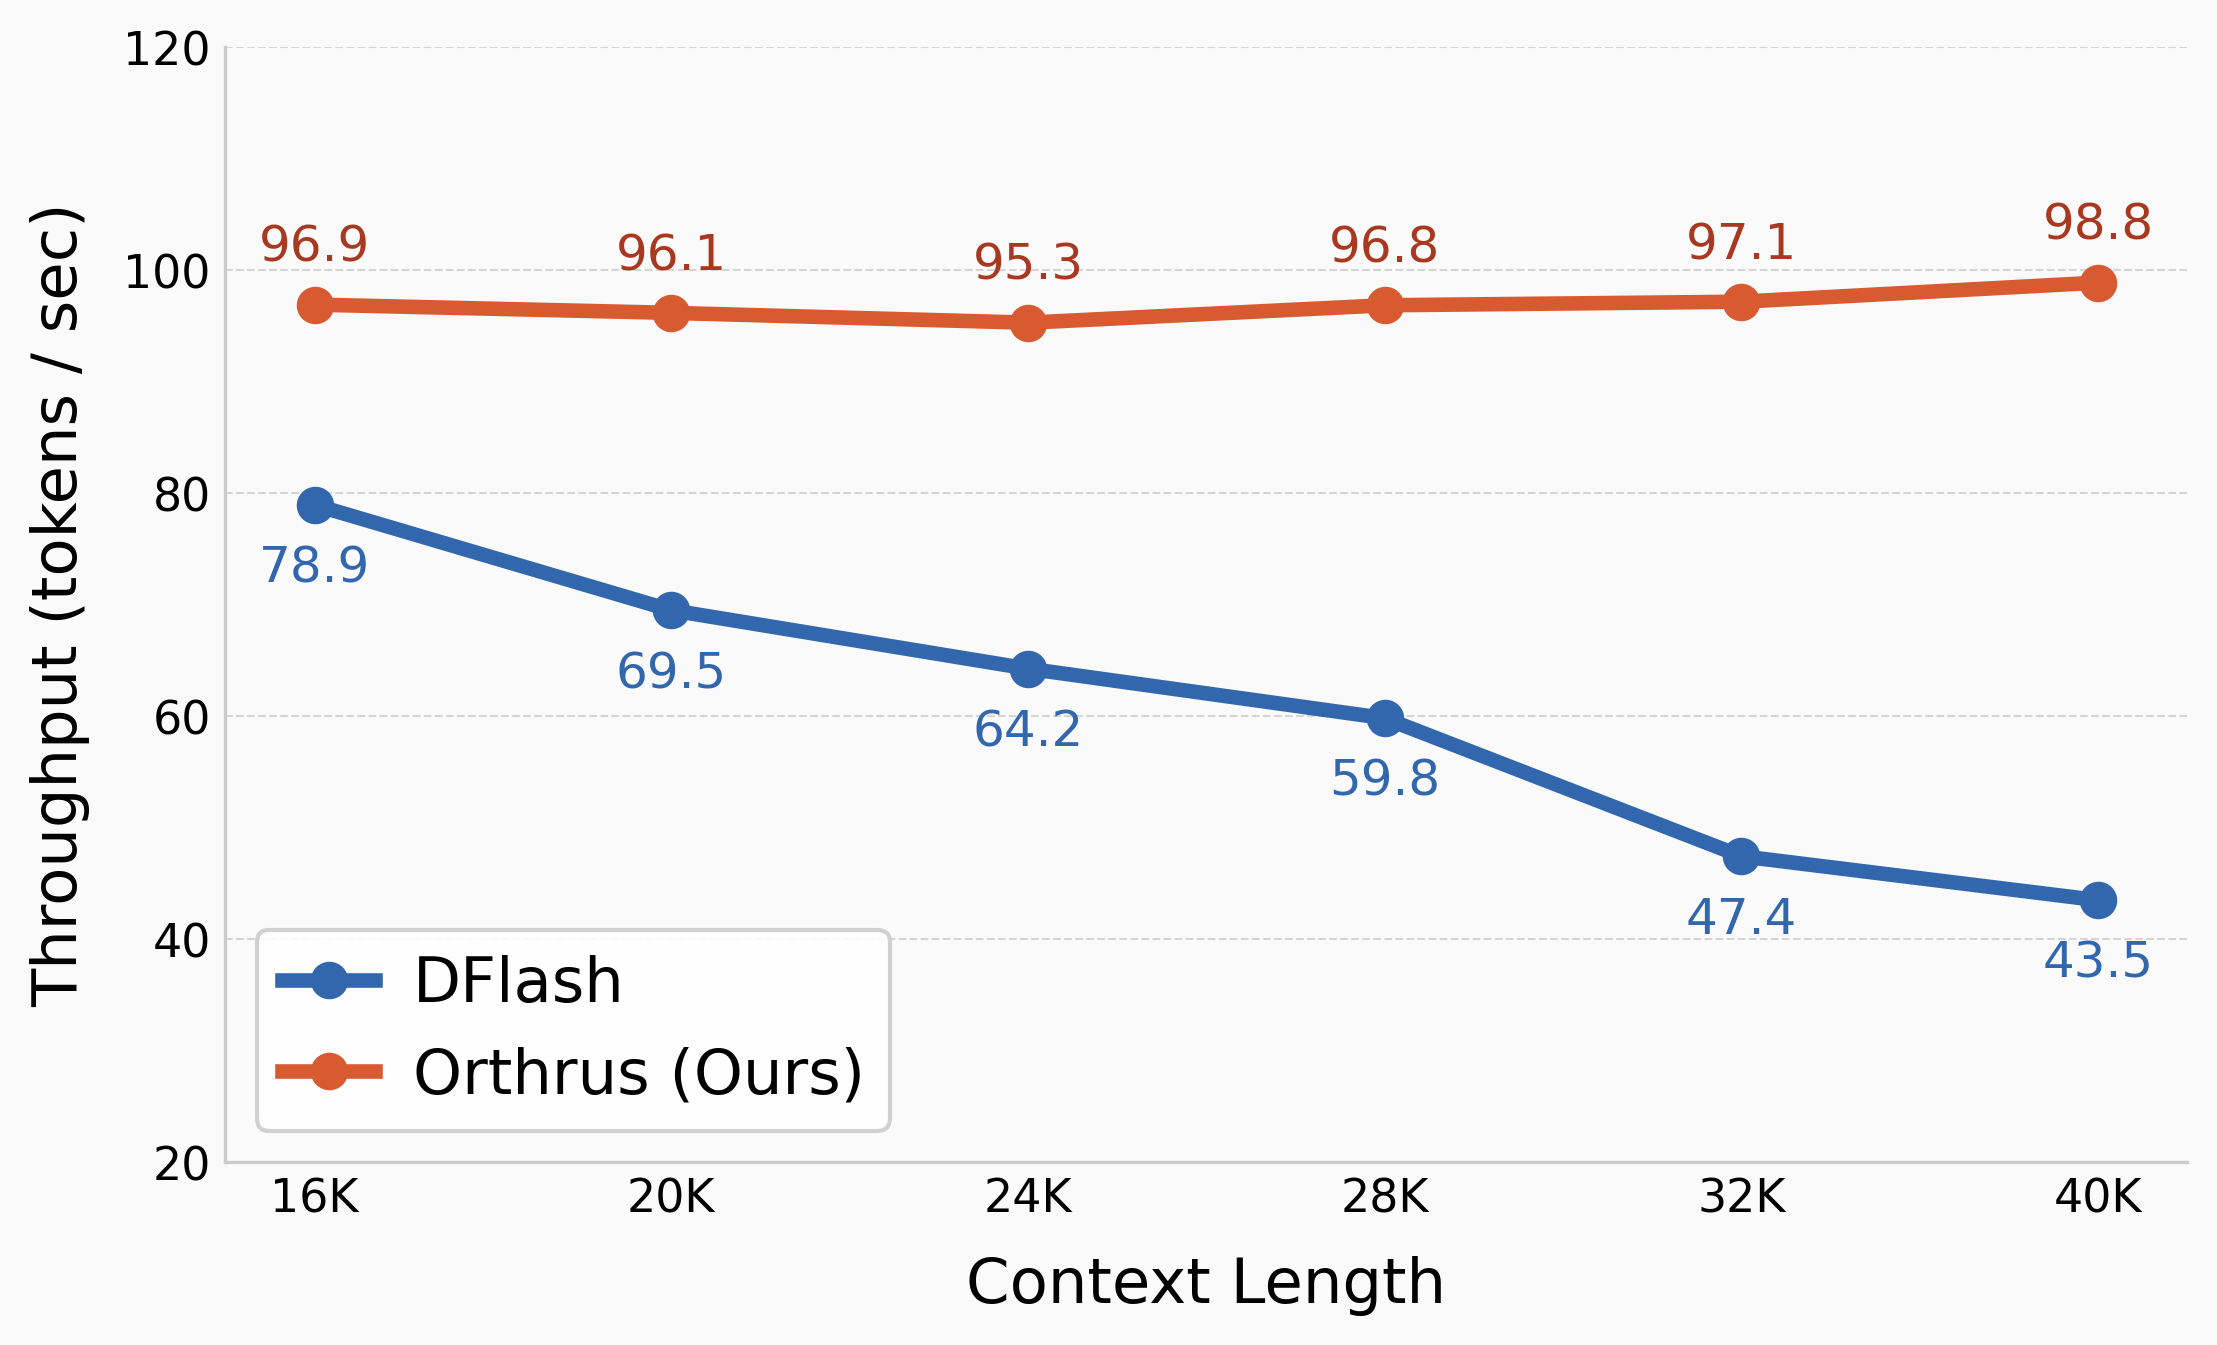
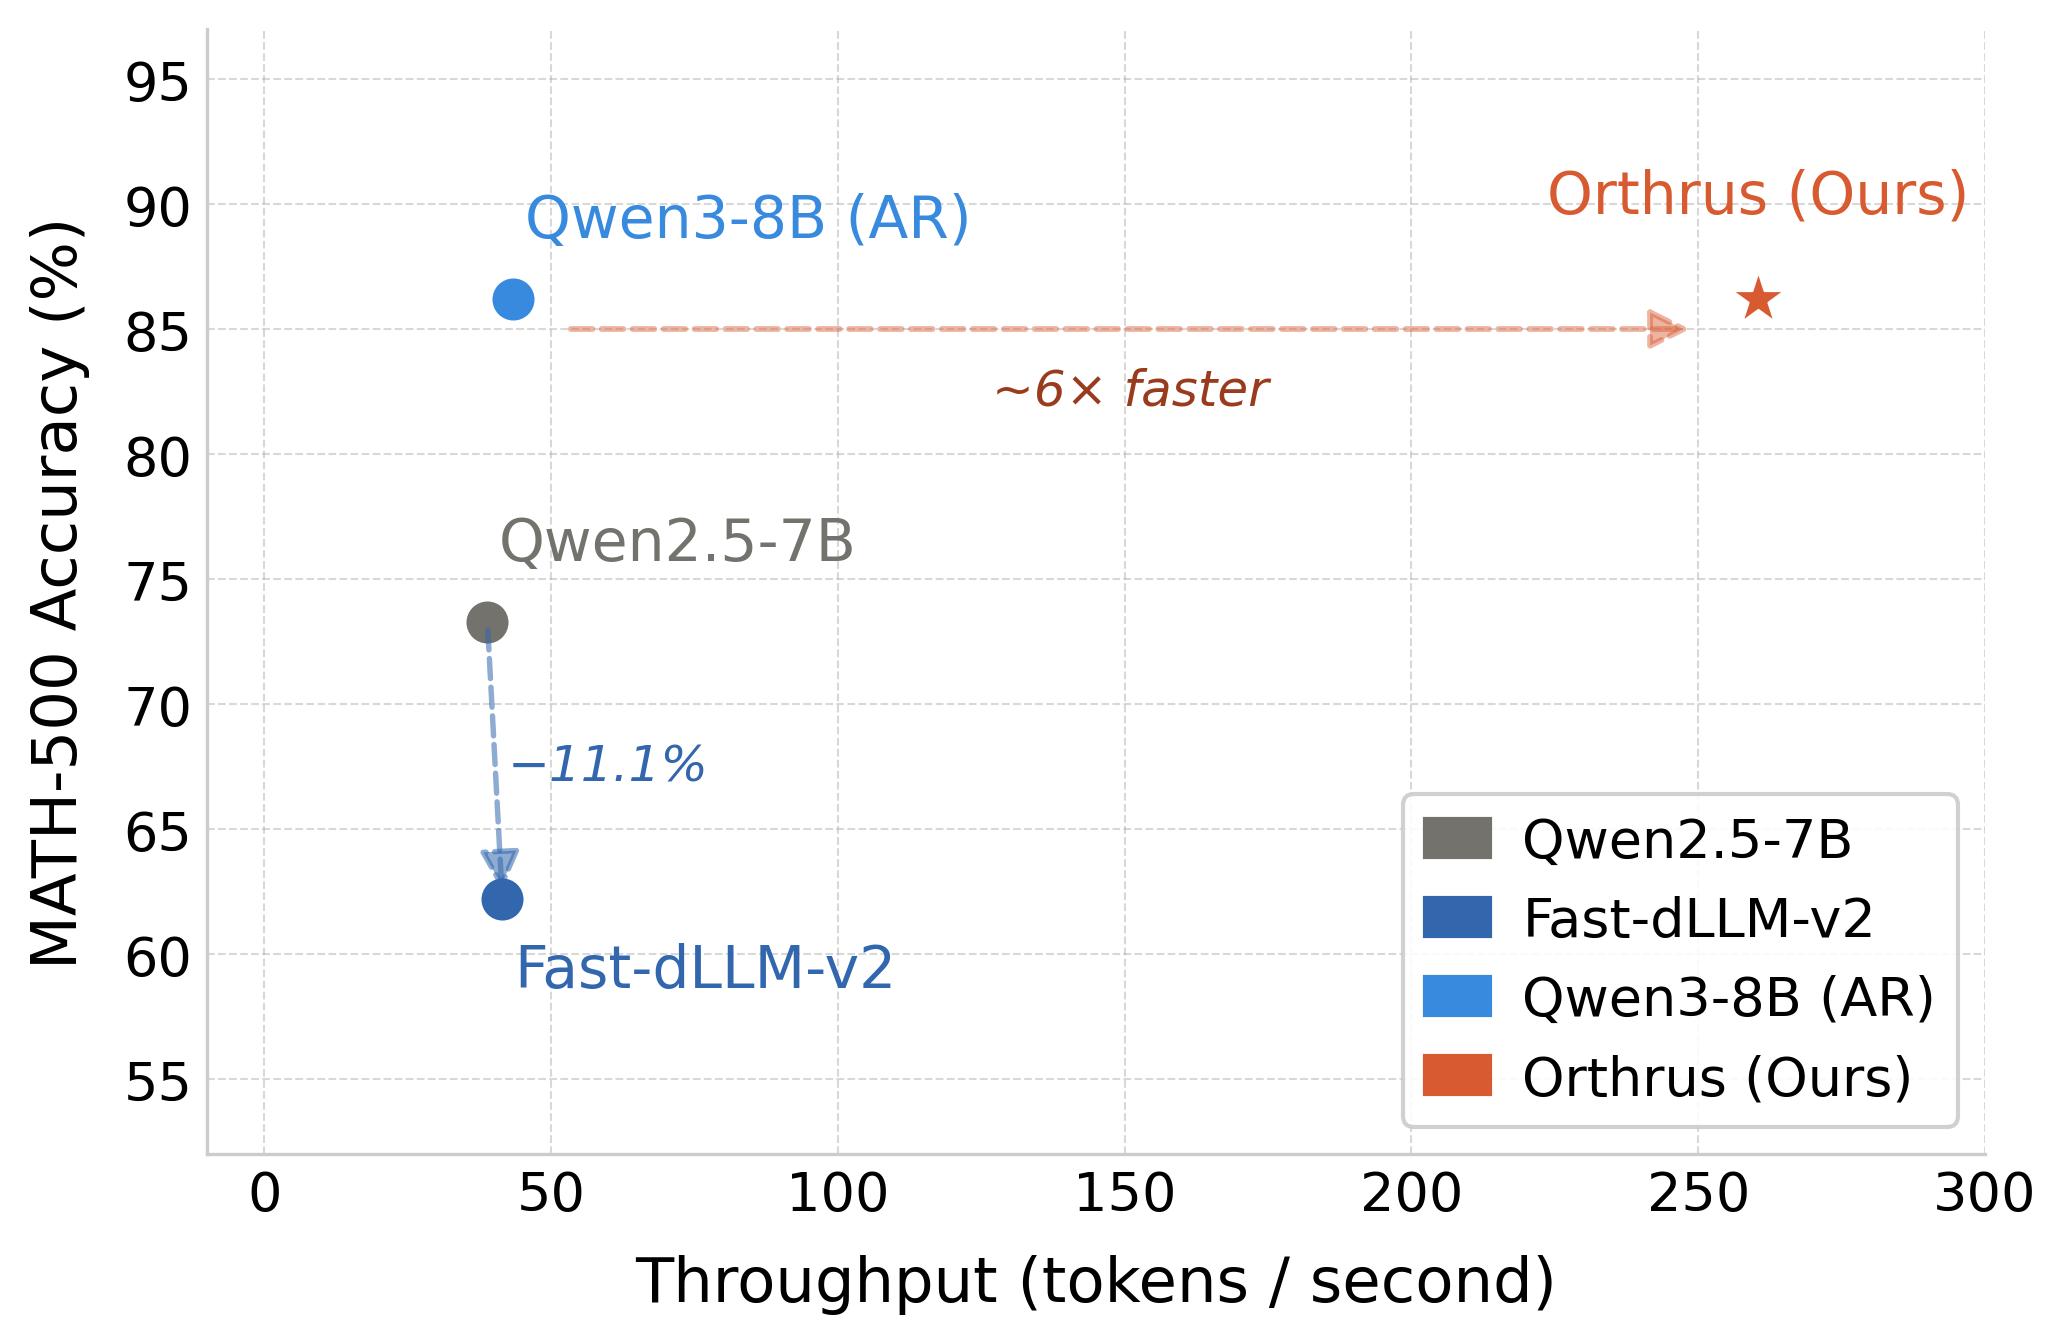
Official implementation and model checkpoints for Orthrus, a dual-architecture framework that unifies the exact generation fidelity of autoregressive Large Language Models (LLMs) with the high-speed parallel token generation of diffusion models.
Get started
uv pip install -e .
uv pip install ninja packaging
uv pip install flash-attn --no-build-isolation # or: pip install "flash-attn-4[cu13]" if your device supports it- Maintenance
- Active
- Last commit 3 months ago
- Stars
- 483
- On GitHub
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 99% of the code
Is it looked after?
- Contributors
- 1
- Last 90 days
- Issues
- 75% closed
- 3 still open
- Pull requests
- 0 merged
- 0 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| incoai / splash | 2,170 | 4 days ago | Apache-2.0 | Mac |
| Picovoice / picollm | 319 | yesterday | Apache-2.0 | No downloads |
| EfficientMoE / MoE-Infinity | 382 | 3 days ago | Apache-2.0 | Linux |
More: languages, topics and project record
Languages
- Python 99%
- Shell 1%
Topics
- diffusion-language-models
- efficient-inference
- large-language-models
- llm
- llm-efficiency
- llm-inference
- model-architecture
- speculative-decoding
Project record
- JobLocal LLMs
- StatusListed
- Commits18
- Forks23
- Watching18
- Stars in 28 days+2
- CreatedMay 13, 2026
- First seen by usNov 7, 2026
- CheckedNov 7, 2026