
declare-lab / TangoFlux
[ICLR 2026] TangoFlux: Super Fast and Faithful Text to Audio Generation with Flow Matching
Why this job: matched by what the repo talks about: text, audio, fast, generation
What it does
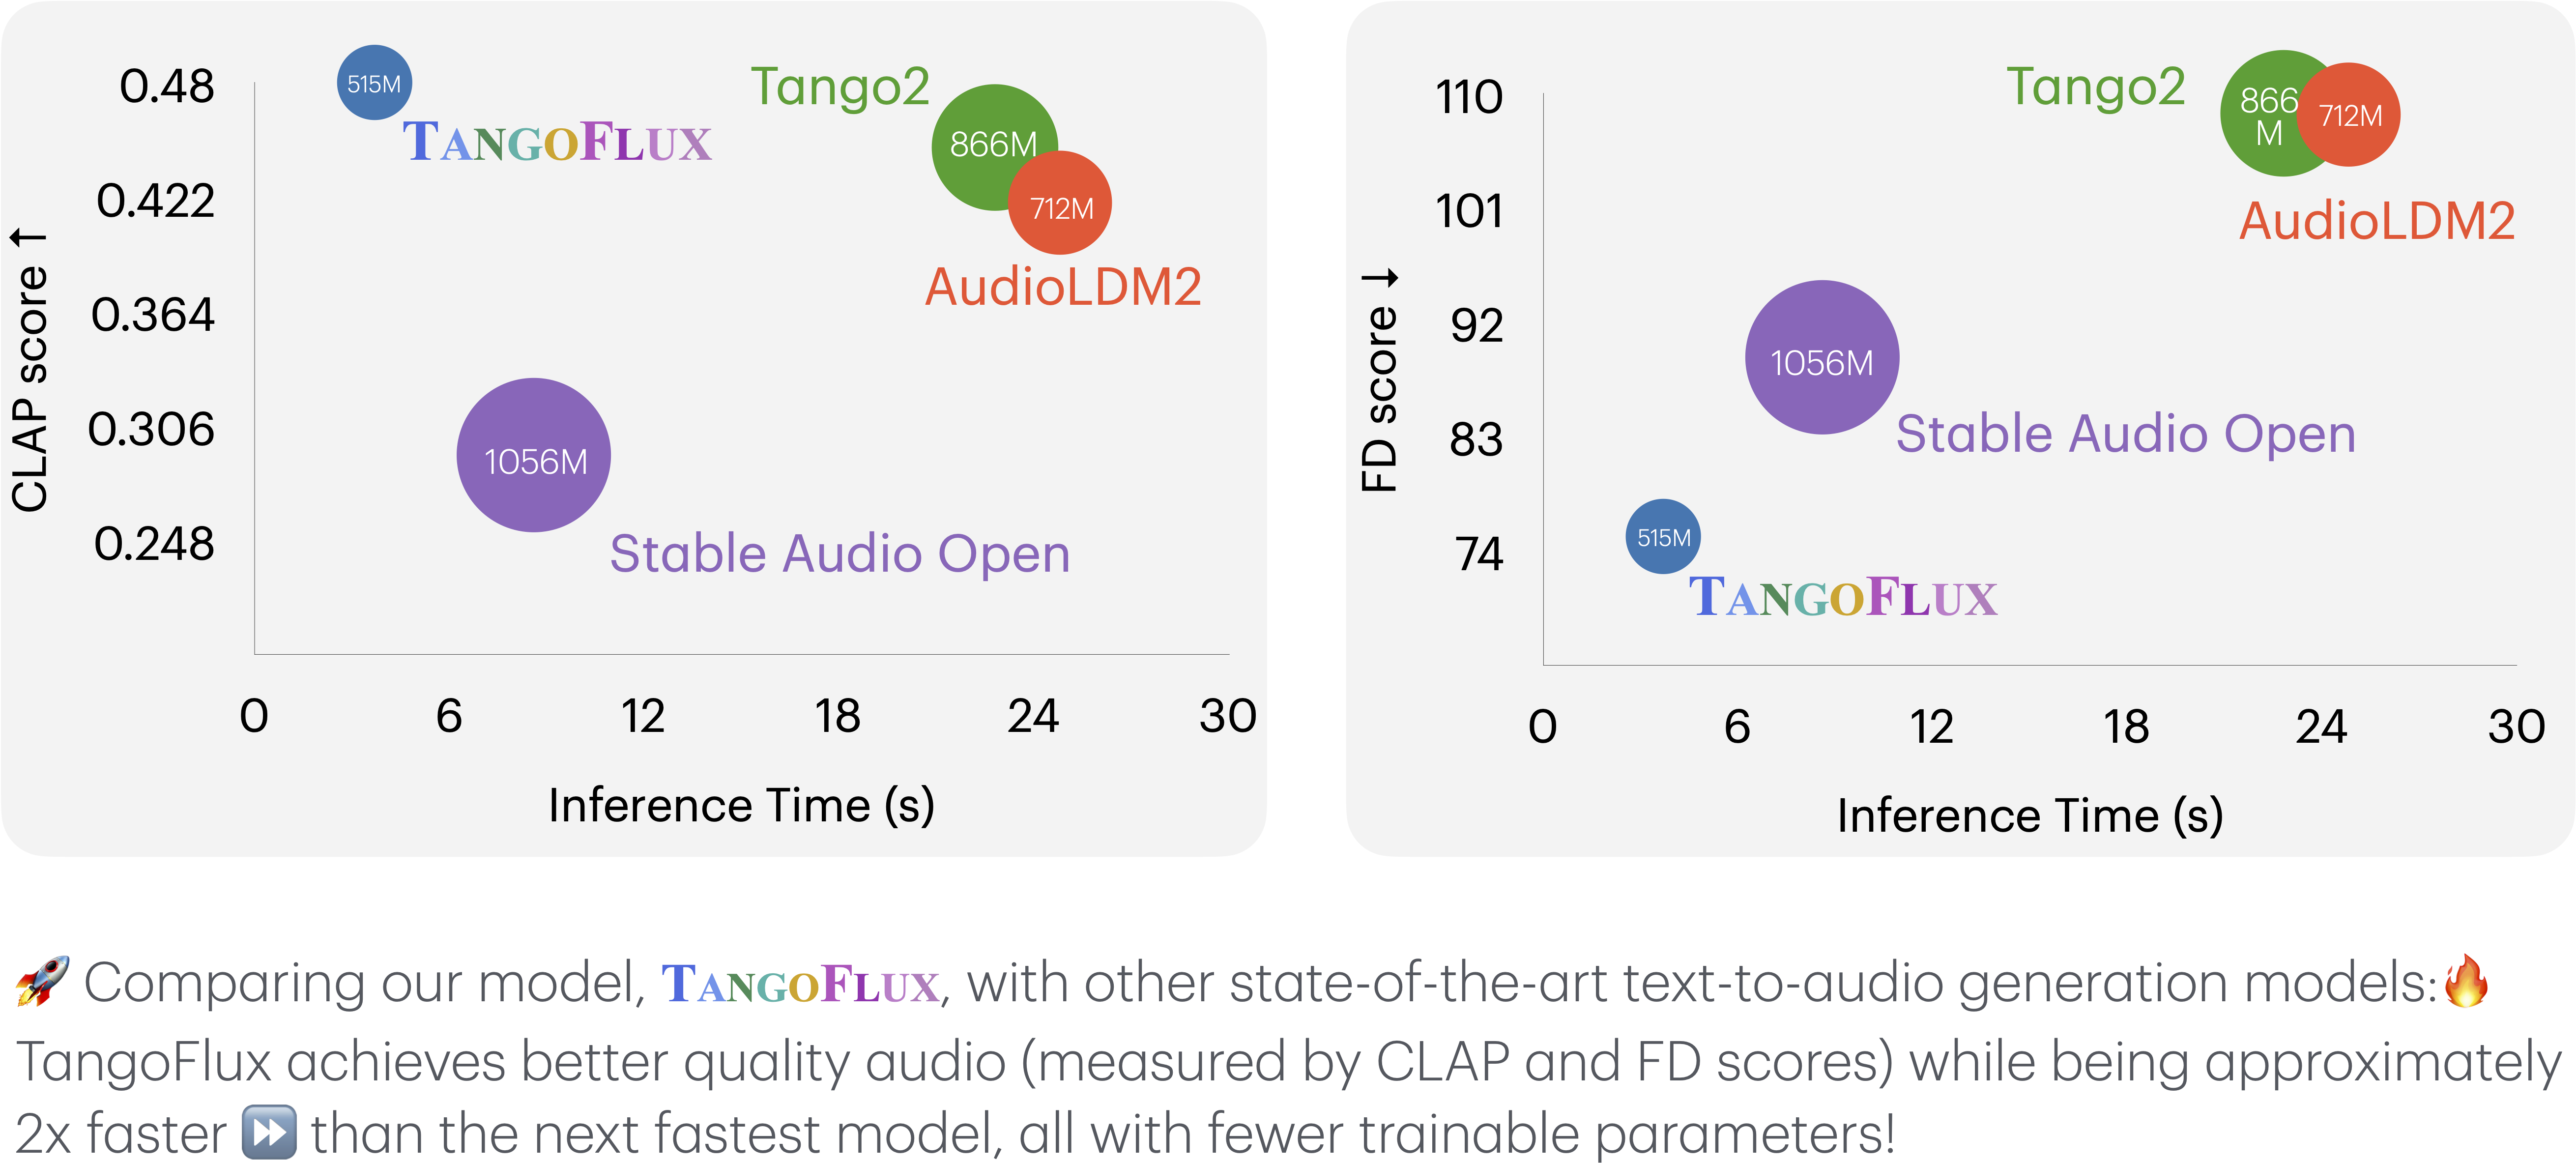
TangoFlux can generate 44.1kHz stereo audio up to 30 seconds in ~3 seconds on a single A40 GPU.
Get started
pip install git+https://github.com/declare-lab/TangoFlux You need: You must comply with the Stability AI Community License Agreement (the “Agreement”) for any usage, distribution, or modification of this Model.; Non-Commercial Use: This Model is for research and academic purposes only. Any commercial usage requires registering with Stability AI or obtaining a separate commercial license.; Attribution & Notice:
- Maintenance
- Inactive
- Last commit 9 months ago
- Stars
- 885
- On GitHub
- Licence
- Custom
- Read before business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Jupyter Notebook
- 95% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 52% closed
- 13 still open
- Pull requests
- 6 merged
- 1 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| Aratako / Irodori-TTS | 1,595 | 3 days ago | MIT | No downloads |
| OpenMOSS / MOSS-TTS | 4,321 | 2 months ago | Apache-2.0 | No downloads |
More: languages, topics and project record
Languages
- Jupyter Notebook 95%
- Python 5%
- JavaScript <1%
- Shell <1%
Topics
- flow-matching
- generative-ai
- text-to-audio
- text-to-audio-ai
- tta
Project record
- JobSpeech and audio
- StatusListed
- Commits89
- Forks79
- Watching10
- Stars in 28 days+3
- CreatedDec 28, 2024
- First seen by usNov 7, 2026
- CheckedNov 8, 2026