
eagle-hq / EAGLE-4
Official Inference Code of EAGLE-4
Why this job: topics: llm-inference, vllm
What it does
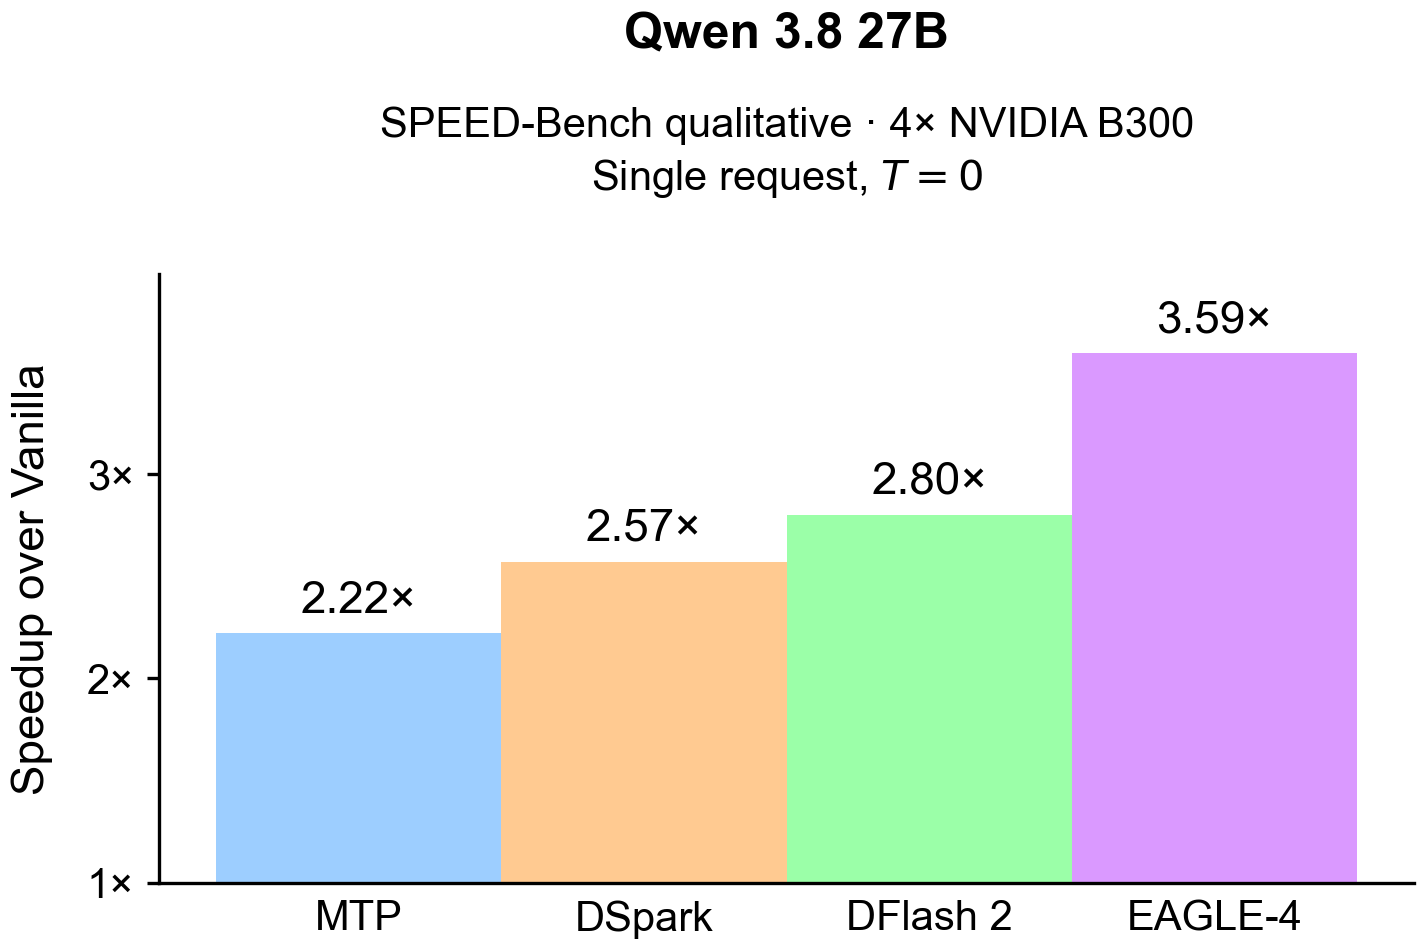
Figure 1(a) of the EAGLE-4 paper: Qwen3.8-27B on the SPEED-Bench qualitative split, 4× NVIDIA B300, one request, temperature 0. The numbers this release measured with EAGLE-4 are in the support matrix.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 9 days ago
- Stars
- 1,163
- +80 this week
- Licence
- Custom
- Read before business use
- Downloads for
- None listed
- No release files
- Latest version
- v0.1.5
- Released 9 days ago
- Built with
- Python
- 92% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 33% closed
- 2 still open
- Pull requests
- 6 merged
- 1 waiting
- Releases
- 6
- 6 in the last year
- Contributing guide (opens in new tab)
- Security policy (opens in new tab)
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| kvcache-ai / Mooncake | 7,013 | today | Apache-2.0 | Linux |
| incoai / splash | 2,170 | 4 days ago | Apache-2.0 | Mac |
| bitcloud-ai / Bittune | 213 | 4 days ago | MIT | Linux |
More: languages, topics and project record
Languages
- Python 92%
- Cuda 7%
- Dockerfile <1%
- Shell <1%
Topics
- eagle
- gpu
- llm-inference
- sglang
- speculative-decoding
- tokenspeed
- vllm
Project record
- JobLocal LLMs
- StatusNew to our list
- Commits79
- Forks42
- Watching29
- CreatedOct 20, 2026
- First seen by usNov 7, 2026
- CheckedNov 8, 2026