
foldl / chatllm.cpp
Pure C++ implementation of several models for real-time chatting on your computer (CPU & GPU)
Why this job: matched by what the repo talks about: cpp, gpu, model, cpu
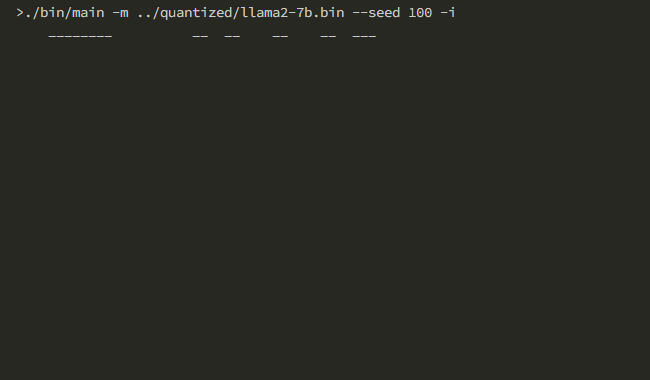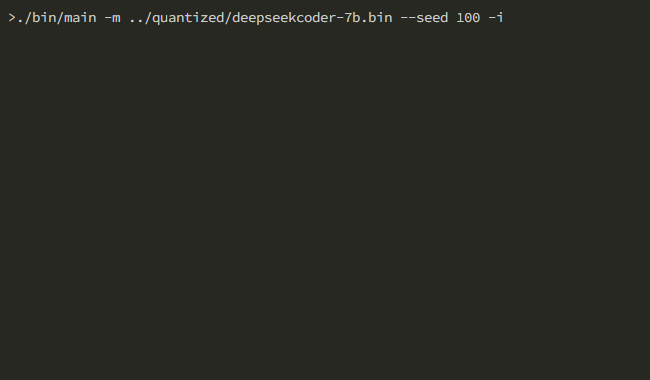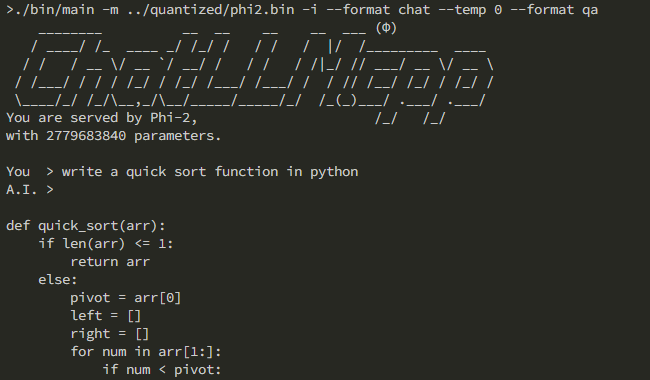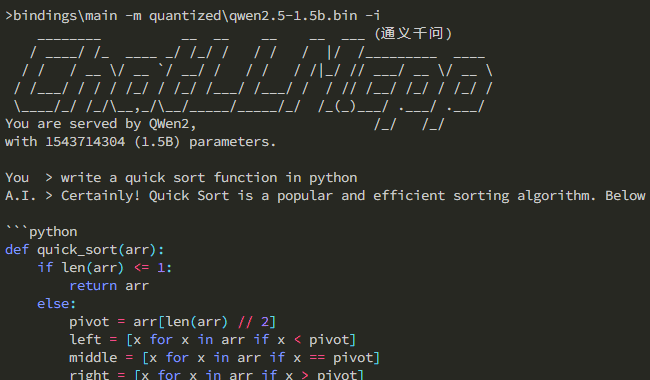
What it does
- Accelerated memory-efficient CPU/GPU inference with int4/int8 quantization, optimized KV cache and parallel computing;
- Use OOP to address the similarities between different _Transformer_ based models;
- Streaming generation with typewriter effect;
- Continuous chatting (content length is virtually unlimited)
- Retrieval Augmented Generation (RAG) 🔥
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 14 days ago
- Stars
- 941
- +4 this week
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest tag
- v25
- Released 23 days ago
- Built with
- C++
- 56% of the code
Is it looked after?
- Contributors
- 2
- Last 90 days
- Issues
- 91% closed
- 11 still open
- Pull requests
- 7 merged
- 0 waiting
- Releases
- 25
- 8 in the last year
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| liguodongiot / llm-action | 25,268 | 27 days ago | Apache-2.0 | No downloads |
| ashhart / TensorFold | 1,719 | yesterday | Apache-2.0 | Mac, Linux |
| Tiiny-AI / PowerInfer | 9,874 | 6 months ago | MIT | No downloads |
More: languages, topics and project record
Languages
- C++ 56%
- C 25%
- Cuda 8%
- Python 2%
Topics
- llm
- llm-inference
Project record
- JobLocal LLMs
- StatusListed
- Commits833
- Forks76
- Watching22
- Stars in 28 days+11
- CreatedDec 2, 2023
- First seen by usNov 7, 2026
- CheckedNov 10, 2026