
hao-ai-lab / DistCA
Efficient Long-context Language Model Training by Core Attention Disaggregation
Why this job: says: model training
What it does
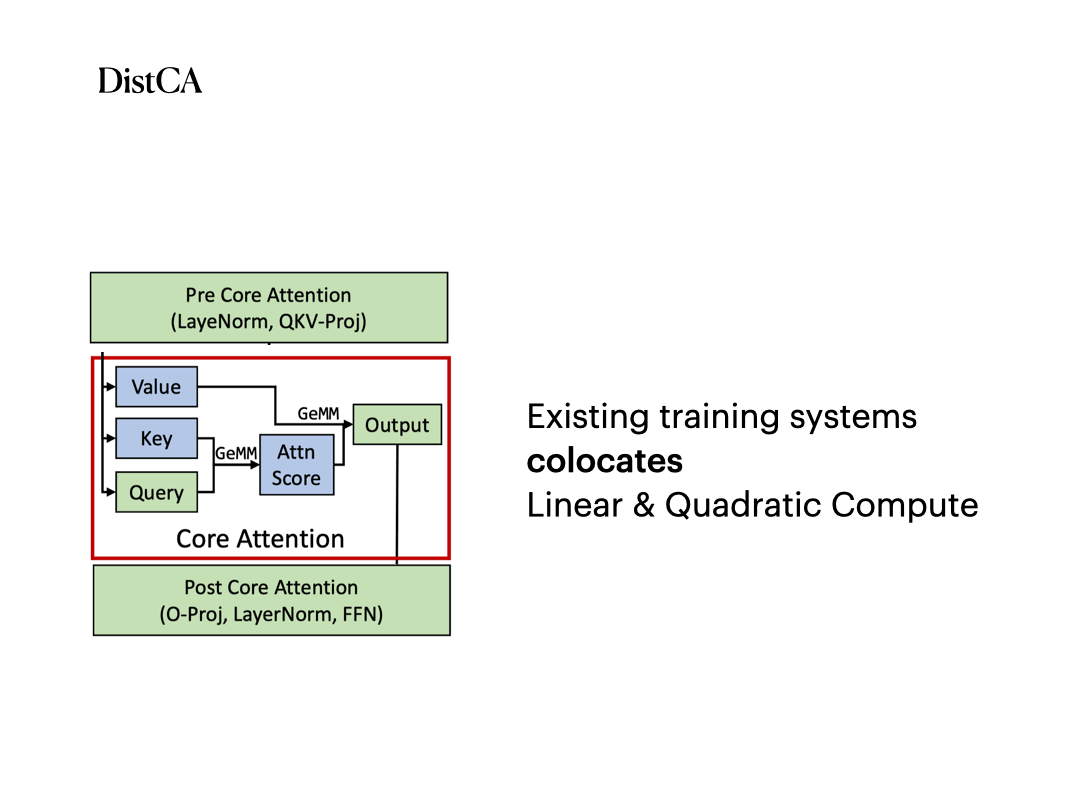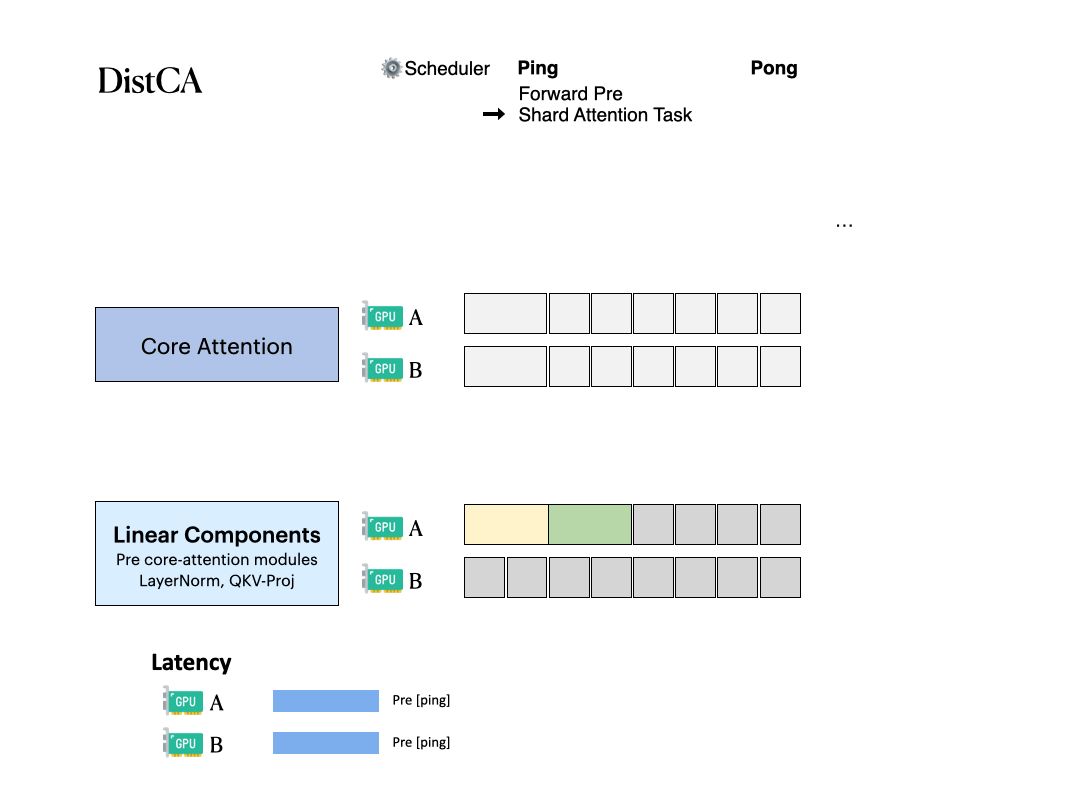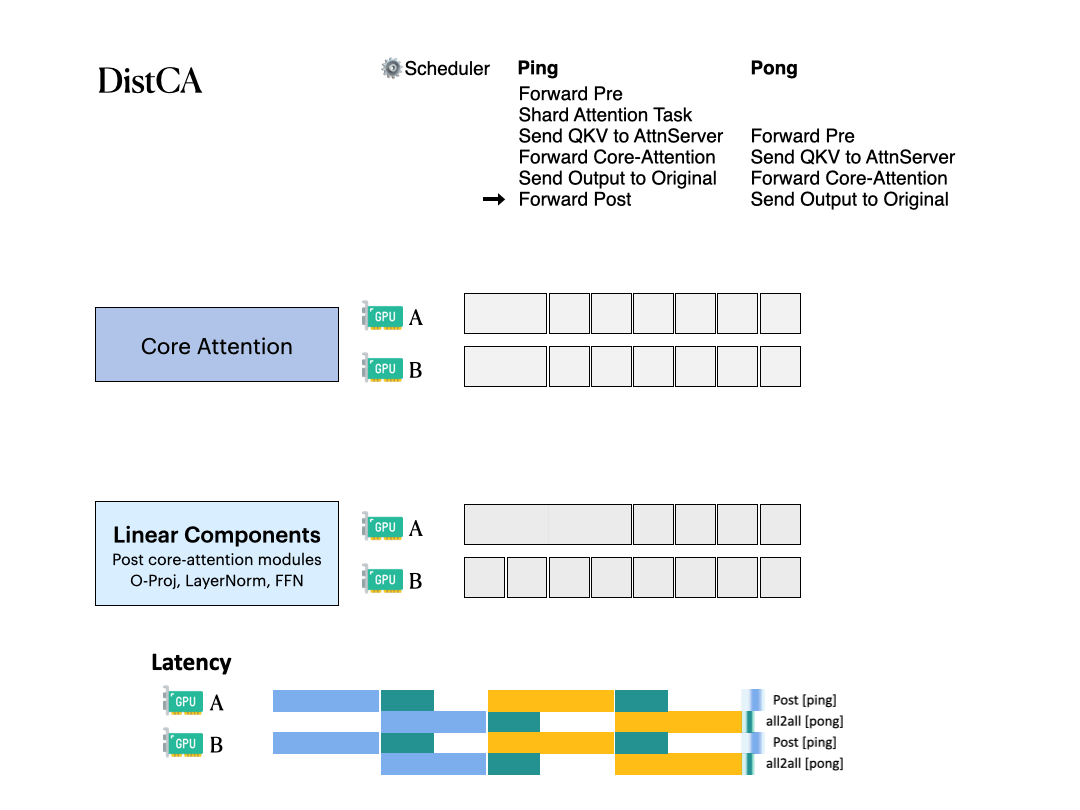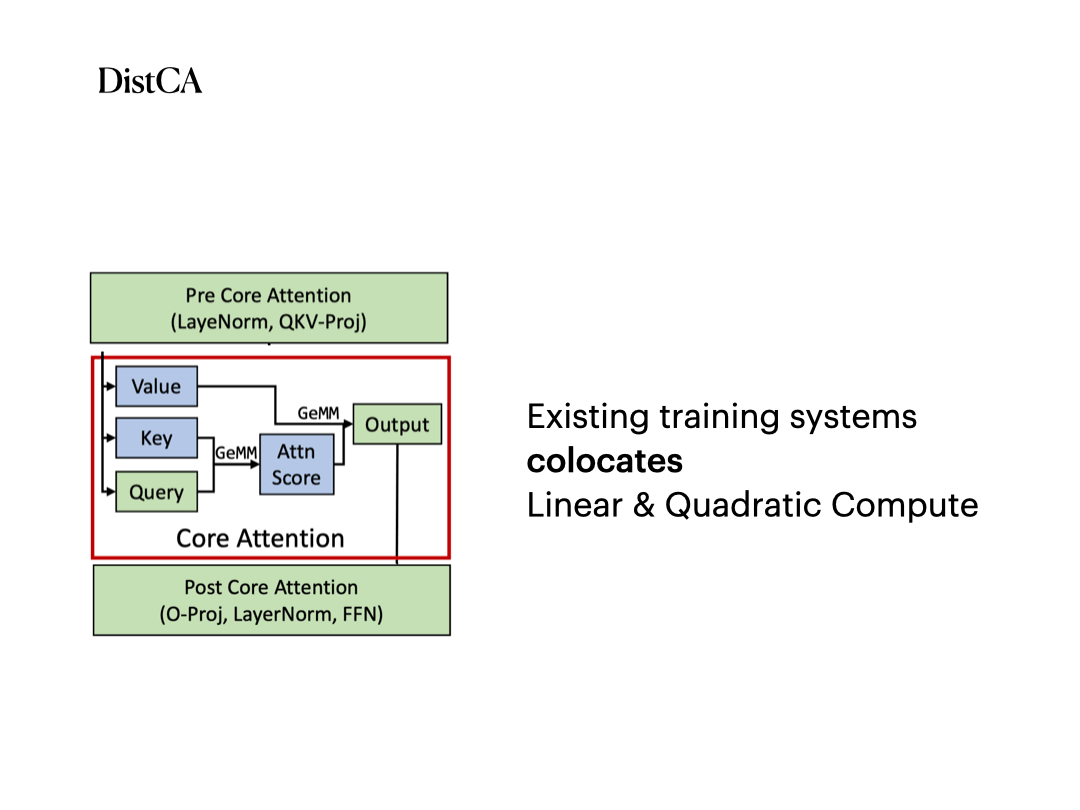
DistCA addresses a fundamental limitation in long-context LLM training: severe workload imbalance caused by the uneven quadratic cost of core attention across micro-batches. Existing systems and parallelization strategies (DP, PP, CP) colocate core attention with linear layers. As context length and system scale increase, this colocation leads to stragglers, pipeline bubbles, and excessive communication or memory overhead.
Get started
git clone --depth 1 https://github.com/hao-ai-lab/DistCA - Maintenance
- Inactive
- Last commit 7 months ago
- Stars
- 107
- +1 this week
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest tag
- v0.1.2-mlsys26-ae
- Released 7 months ago
- Built with
- Python
- 90% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 75% closed
- 2 still open
- Pull requests
- 115 merged
- 3 waiting
- Releases
- 2
- 2 in the last year
- No contributing guide
- No security policy
- No code of conduct
More: languages, topics and project record
Languages
- Python 90%
- Shell 6%
- C++ 1%
- Cuda 1%
Topics
- llm
Project record
- JobFine-tuning
- StatusListed
- Commits245
- Forks8
- Watching2
- Stars in 28 days+1
- CreatedMay 1, 2025
- First seen by usNov 7, 2026
- CheckedNov 8, 2026