
huawei-csl / KVarN
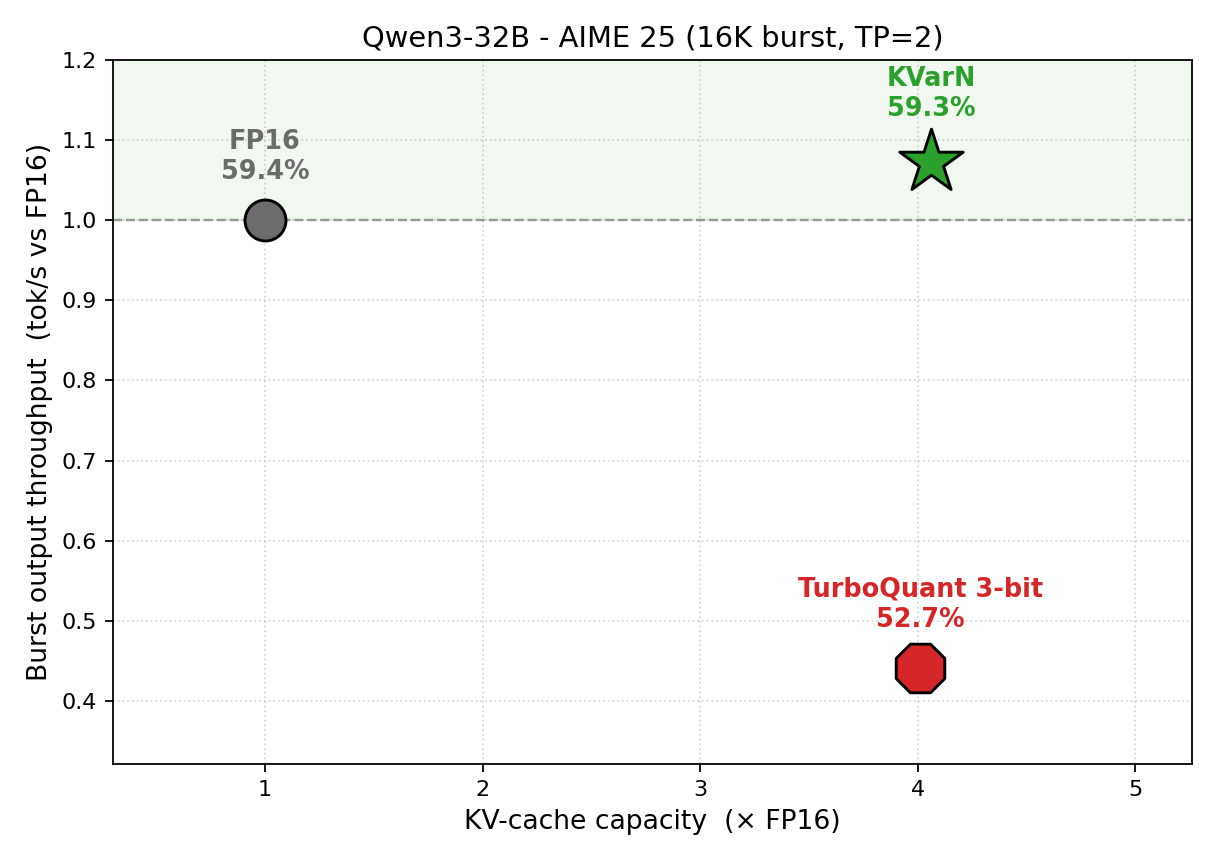
KVarN is a native vLLM KV-cache quantization backend for your agents: 3-5x more context, throughput above FP16, and FP16-level accuracy. Calibration-free, one flag.
Why this job: topics: llm-inference, vllm, quantization
What it does
KVarN stays in the upper-right corner the blog's methods can't reach: FP16-level accuracy, FP16-or-better throughput, and several times the context.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 4 months ago
- Stars
- 518
- +3 this week
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 84% of the code
Is it looked after?
- Contributors
- 0
- Last 90 days
- Issues
- 38% closed
- 8 still open
- Pull requests
- 2 merged
- 3 waiting
- Releases
- None
- Never published
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| syv-ai / HyperQwen | 2,639 | today | Apache-2.0 | No downloads |
| LMCache / LMCache | 12,321 | today | Apache-2.0 | Linux |
| Dynamis-Labs / spectralquant | 204 | 5 months ago | MIT | No downloads |
More: languages, topics and project record
Languages
- Python 84%
- Cuda 6%
- Rust 5%
- C++ 4%
Topics
- agentic-ai
- kv-cache
- llm
- llm-inference
- long-context
- quantization
- vllm
Project record
- JobLocal LLMs
- StatusListed
- Commits227
- Forks37
- Watching5
- Stars in 28 days+11
- CreatedMay 29, 2026
- First seen by usNov 7, 2026
- CheckedNov 7, 2026