
huawei-csl / MACaQ
SOTA model-agnostic quantization for GGUF, local inference and beyond. Quantize and run text, image, video and audio models with llama.cpp, vLLM, Diffusers and PyTorch.
Why this job: says: llama.cpp; topics: llama-cpp, gguf, vllm, local-ai, quantization, local inference, gguf
What it does
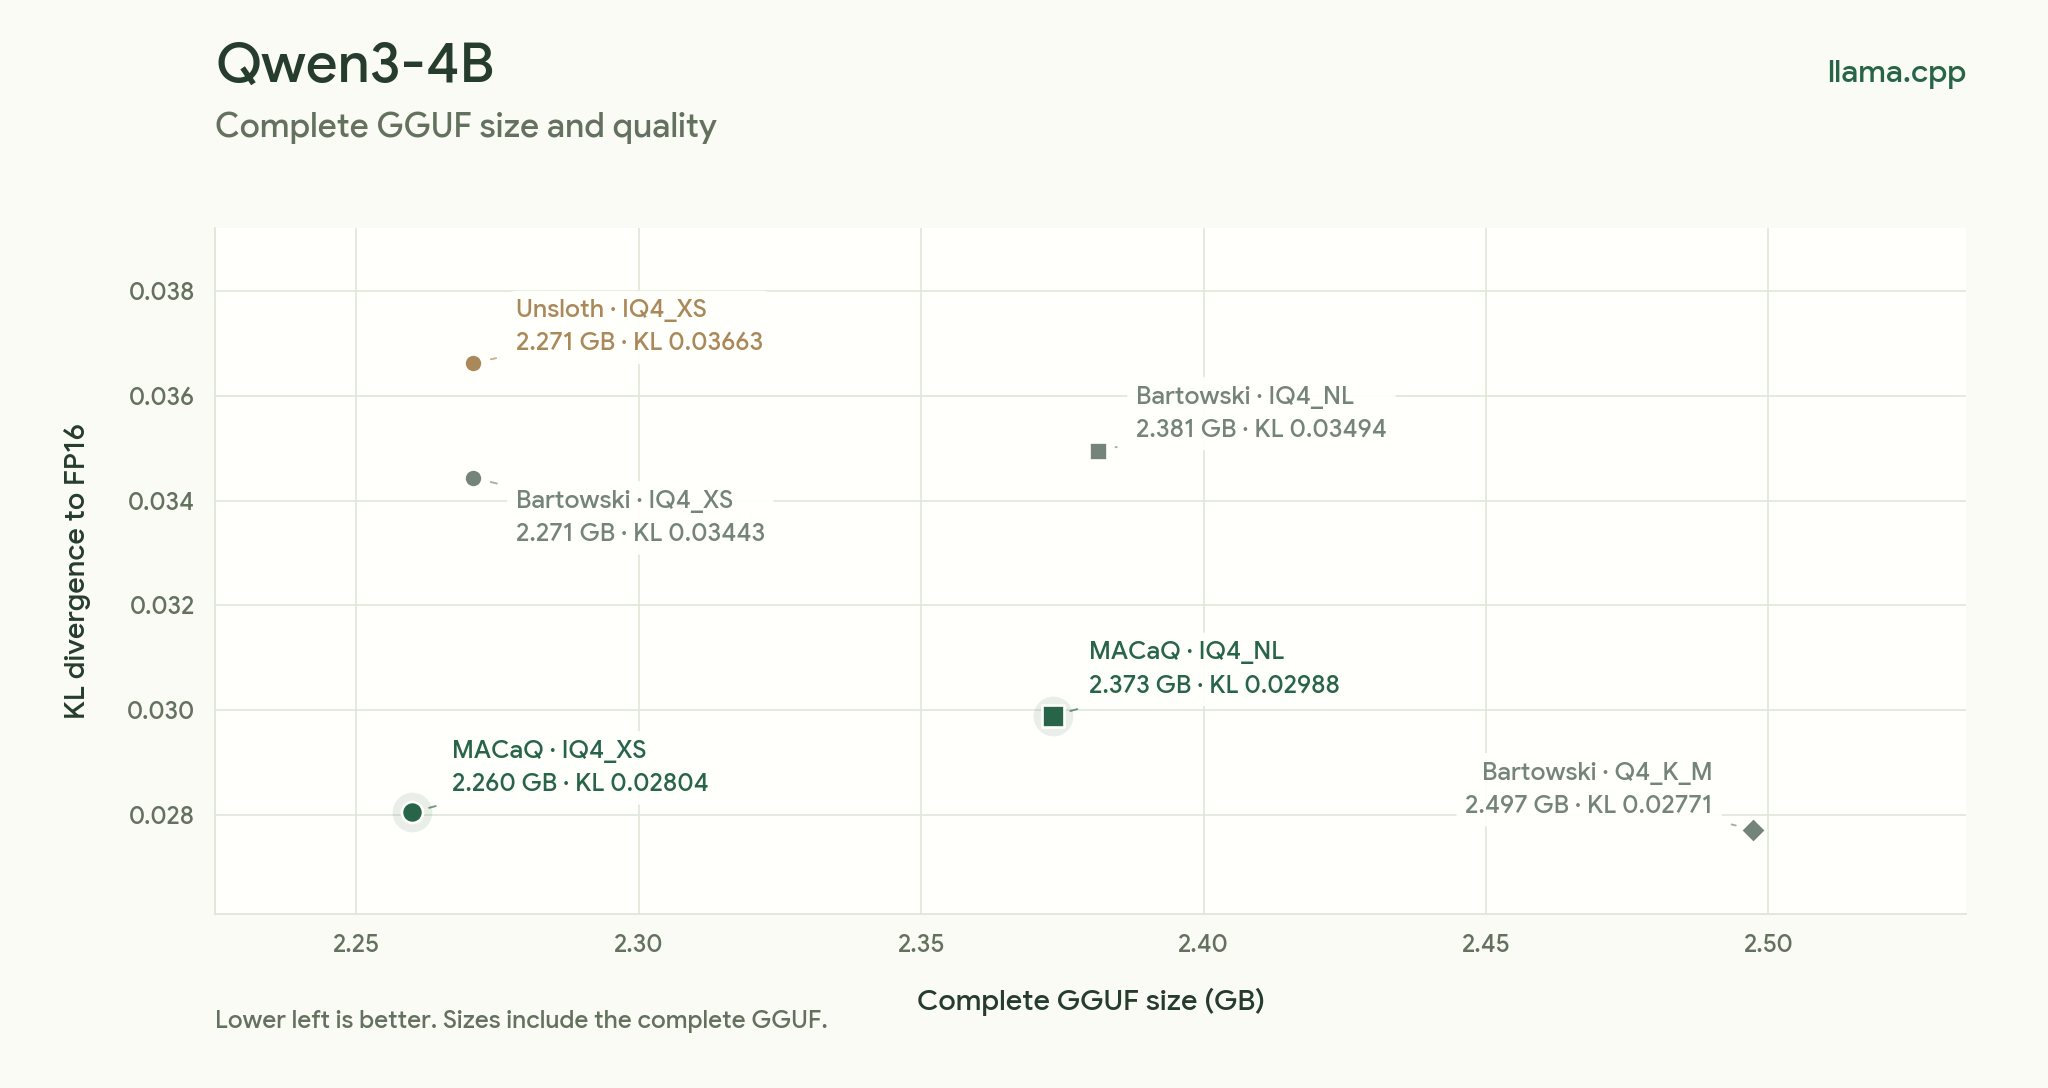
Quantize and run text, image, video and audio models with llama.cpp, vLLM, Diffusers and PyTorch. MACaQ can quantize a 122B-parameter model in 64 minutes using just 32.5 GB of device memory. You can get lower perplexity than MR-GPTQ and DuQuant++, or match their best Llama-3-8B perplexity with 11× less quantization time. Read the paper.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit today
- Stars
- 103
- On GitHub
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- C++
- 55% of the code
Is it looked after?
- Contributors
- 1
- Last 90 days
- Issues
- 0% closed
- 1 still open
- Pull requests
- 0 merged
- 0 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| xorbitsai / inference | 9,653 | yesterday | Apache-2.0 | No downloads |
| gpustack / gpustack | 6,030 | yesterday | Apache-2.0 | No downloads |
| lone-cloud / gerbil | 480 | 9 days ago | AGPL-3.0 | Mac, Windows, Linux |
More: languages, topics and project record
Languages
- C++ 55%
- C 15%
- Python 9%
- Cuda 5%
Topics
- ascend
- audio
- audio-generation
- diffusers
- gguf
- gguf-quantization
- image-generation
- llm
- local-ai
- local-inference
- quantization
- video-generation
Project record
- JobLocal LLMs
- StatusNew to our list
- Commits20
- Forks4
- Watching0
- CreatedNov 10, 2026
- First seen by usNov 12, 2026
- CheckedNov 12, 2026