
jy-yuan / KIVI
[ICML 2024] KIVI: A Tuning-Free Asymmetric 2bit Quantization for KV Cache
Why this job: topics: inference, quantization, llama
What it does
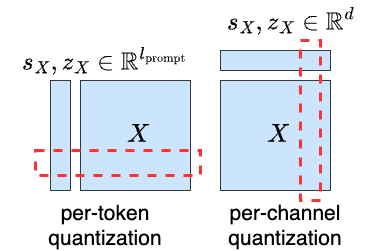
KIVI is a new plug-and-play 2bit KV cache quantization algorithm without any fine-tuning. This algorithm optimizes memory usage by quantizing the key cache per-channel and the value cache per-token to 2bit. KIVI's hardware-friendly design allows LLMs like Llama-2, Falcon, and Mistral to maintain comparable quality levels while reducing peak memory usage by 2.6 times. This enables up to 4 times larger batch sizes and significantly increases throughput by 2.35 to 3.47 times in real LLM inference workloads, effectively addressing the bottleneck issues in speed and memory usage.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Inactive
- Last commit 11 months ago
- Stars
- 439
- +1 this week
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 83% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 85% closed
- 6 still open
- Pull requests
- 7 merged
- 1 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| adithya-s-k / AI-Engineering.academy | 2,389 | 8 months ago | MIT | No downloads |
| vllm-project / vllm | 96,774 | today | Apache-2.0 | Mac, Linux |
| sgl-project / sglang | 38,767 | today | Apache-2.0 | No downloads |
More: languages, topics and project record
Languages
- Python 83%
- Cuda 15%
- Jupyter Notebook 1%
- C <1%
Topics
- inference
- large-language-models
- llama
- llm
- natural-language-processing
- quantization
- transformer
Project record
- JobLocal LLMs
- StatusListed
- Commits64
- Forks58
- Watching7
- Stars in 28 days+4
- CreatedFeb 2, 2024
- First seen by usNov 7, 2026
- CheckedNov 8, 2026