
nari-labs / dia2
TTS model capable of streaming conversational audio in realtime.
Why this job: says: tts; topics: text-to-speech
What it does
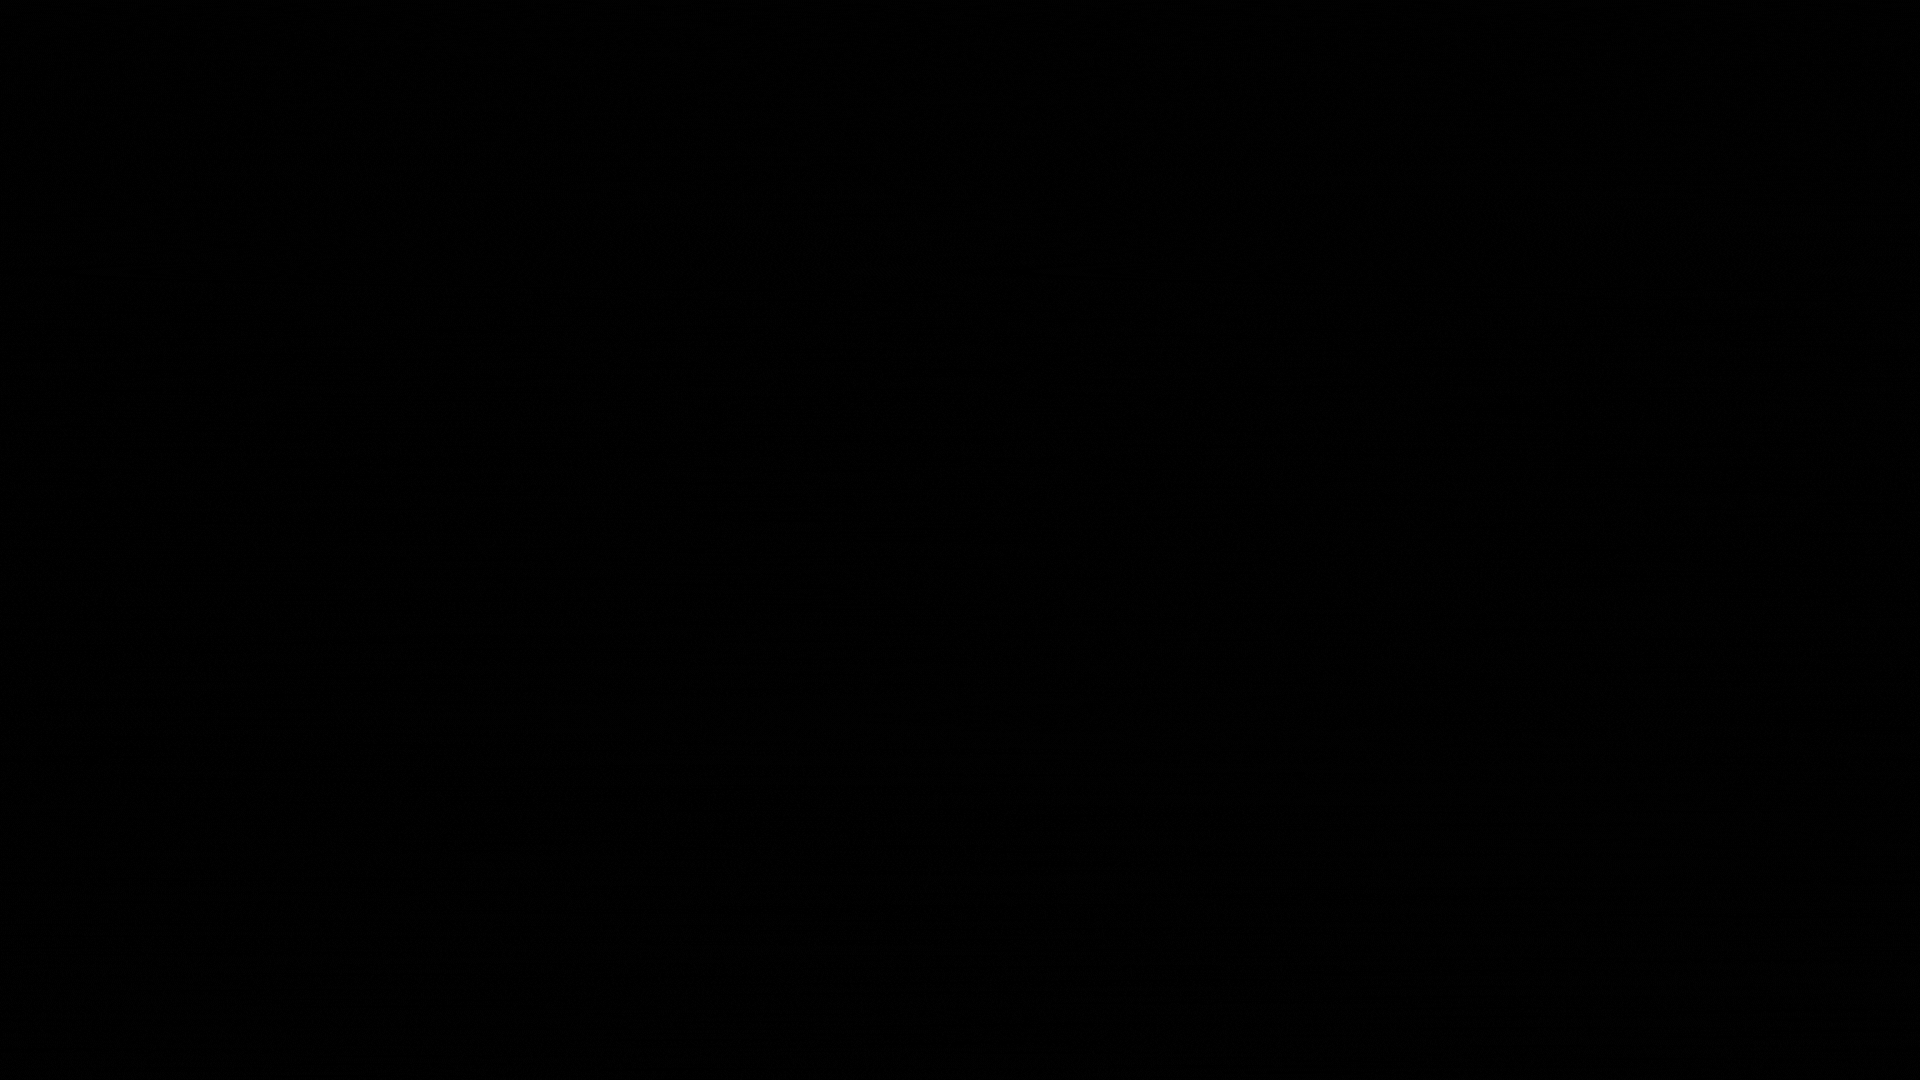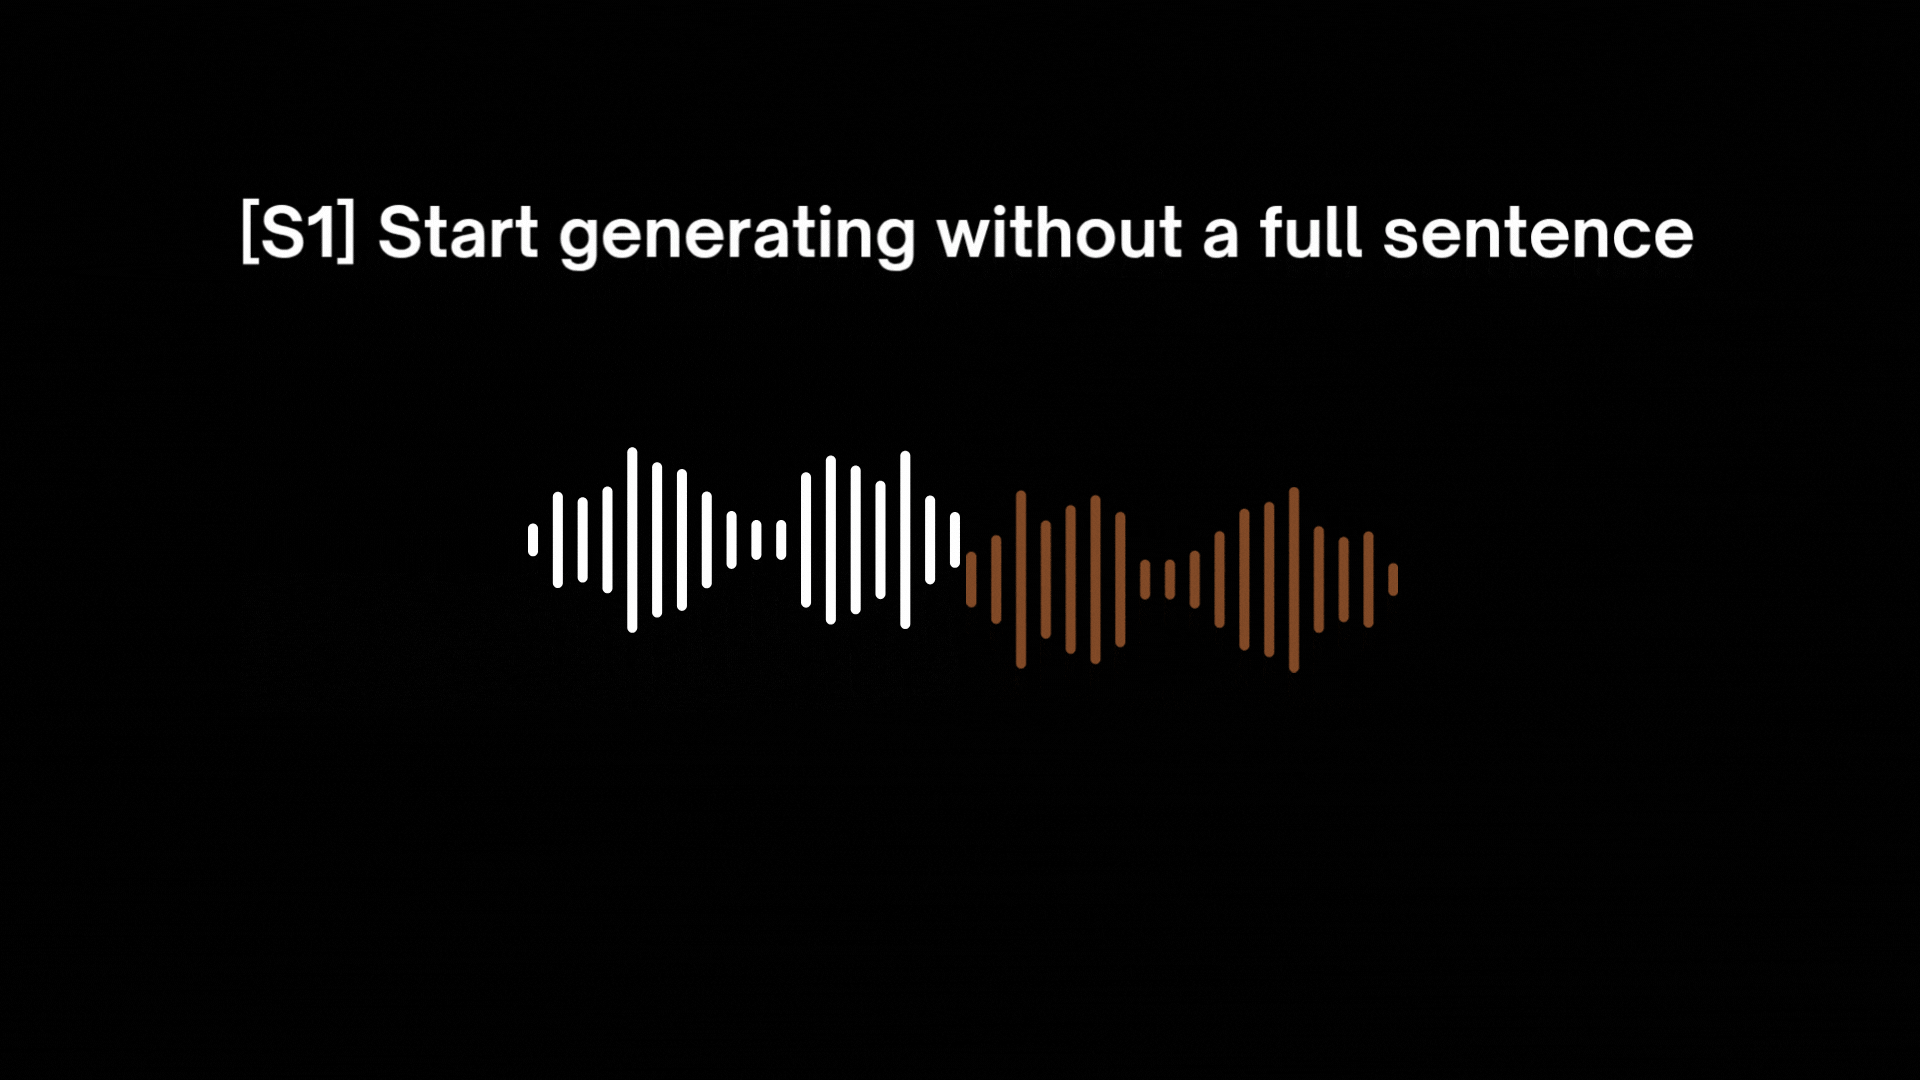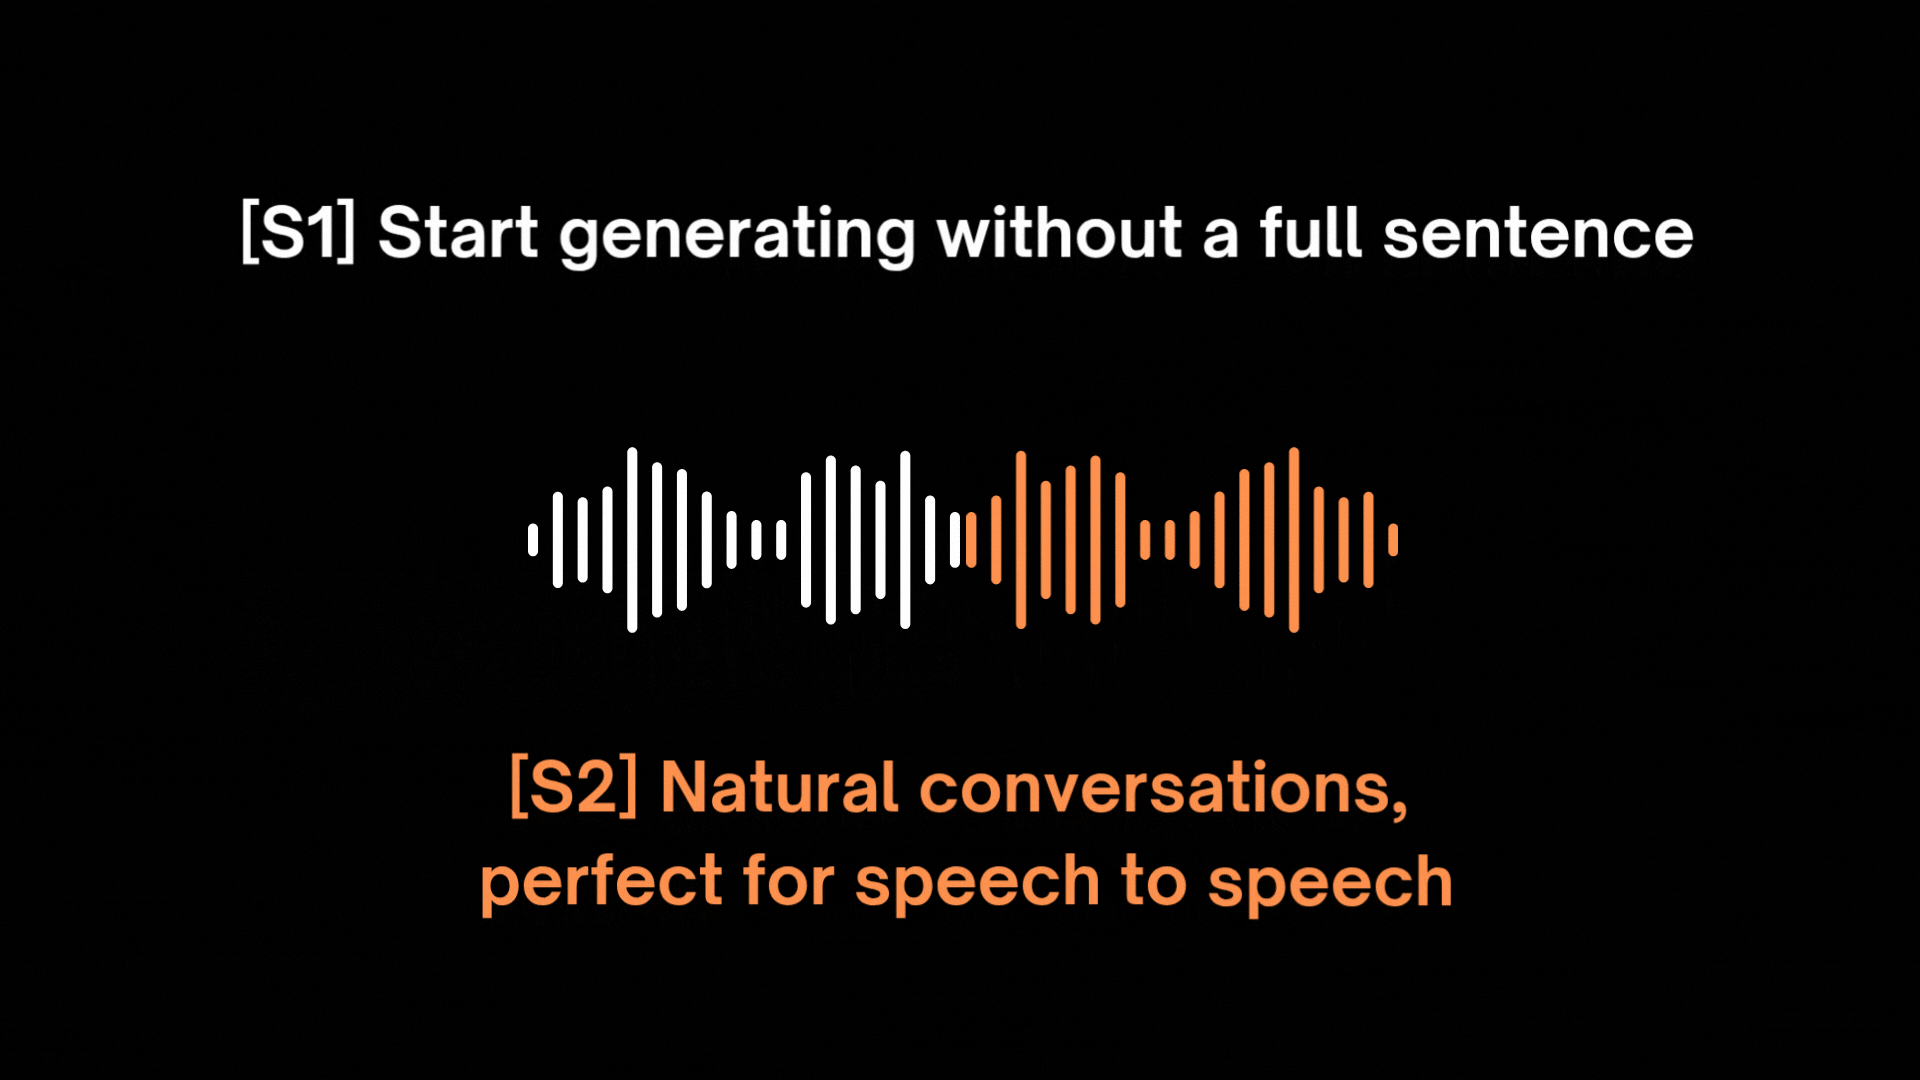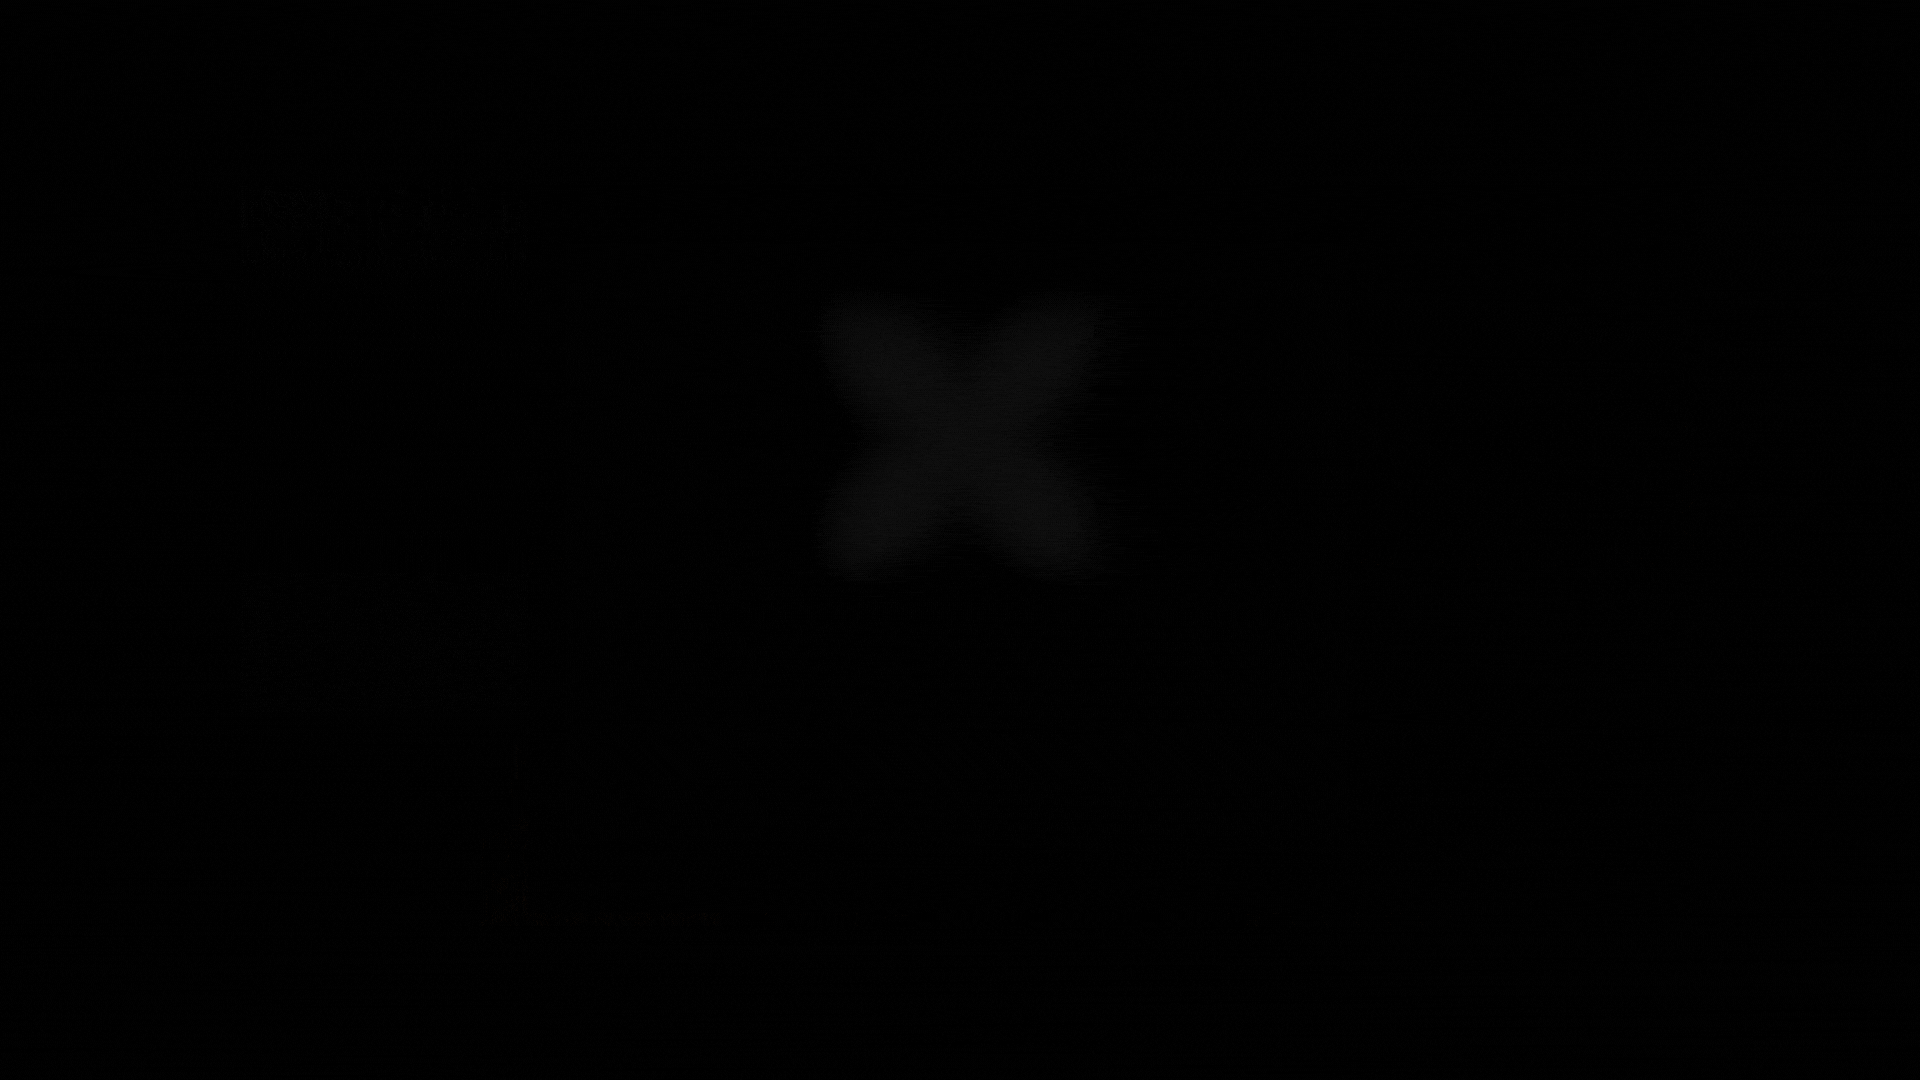
The model does not need the entire text to produce the audio, and can start generating as the first few words are given as input. You can condition the output on audio, enabling natural conversations in realtime.
Get started
uv sync- Maintenance
- Inactive
- Last commit 11 months ago
- Stars
- 1,187
- +1 this week
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 100% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 0% closed
- 3 still open
- Pull requests
- 3 merged
- 2 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| ekwek1 / soprano | 1,635 | 10 months ago | Apache-2.0 | No downloads |
| fishaudio / fish-audio-python | 232 | 12 days ago | Apache-2.0 | No downloads |
More: languages, topics and project record
Languages
- Python 100%
Topics
- open-weight
- text-to-speech
Project record
- JobSpeech and audio
- StatusListed
- Commits19
- Forks103
- Watching17
- Stars in 28 days+7
- CreatedNov 17, 2025
- First seen by usNov 7, 2026
- CheckedNov 8, 2026