
NVlabs / GDPO
Official implementation of GDPO: Group reward-Decoupled Normalization Policy Optimization for Multi-reward RL Optimization
Why this job: works in the areas we cover, but does not say which job it does
What it does
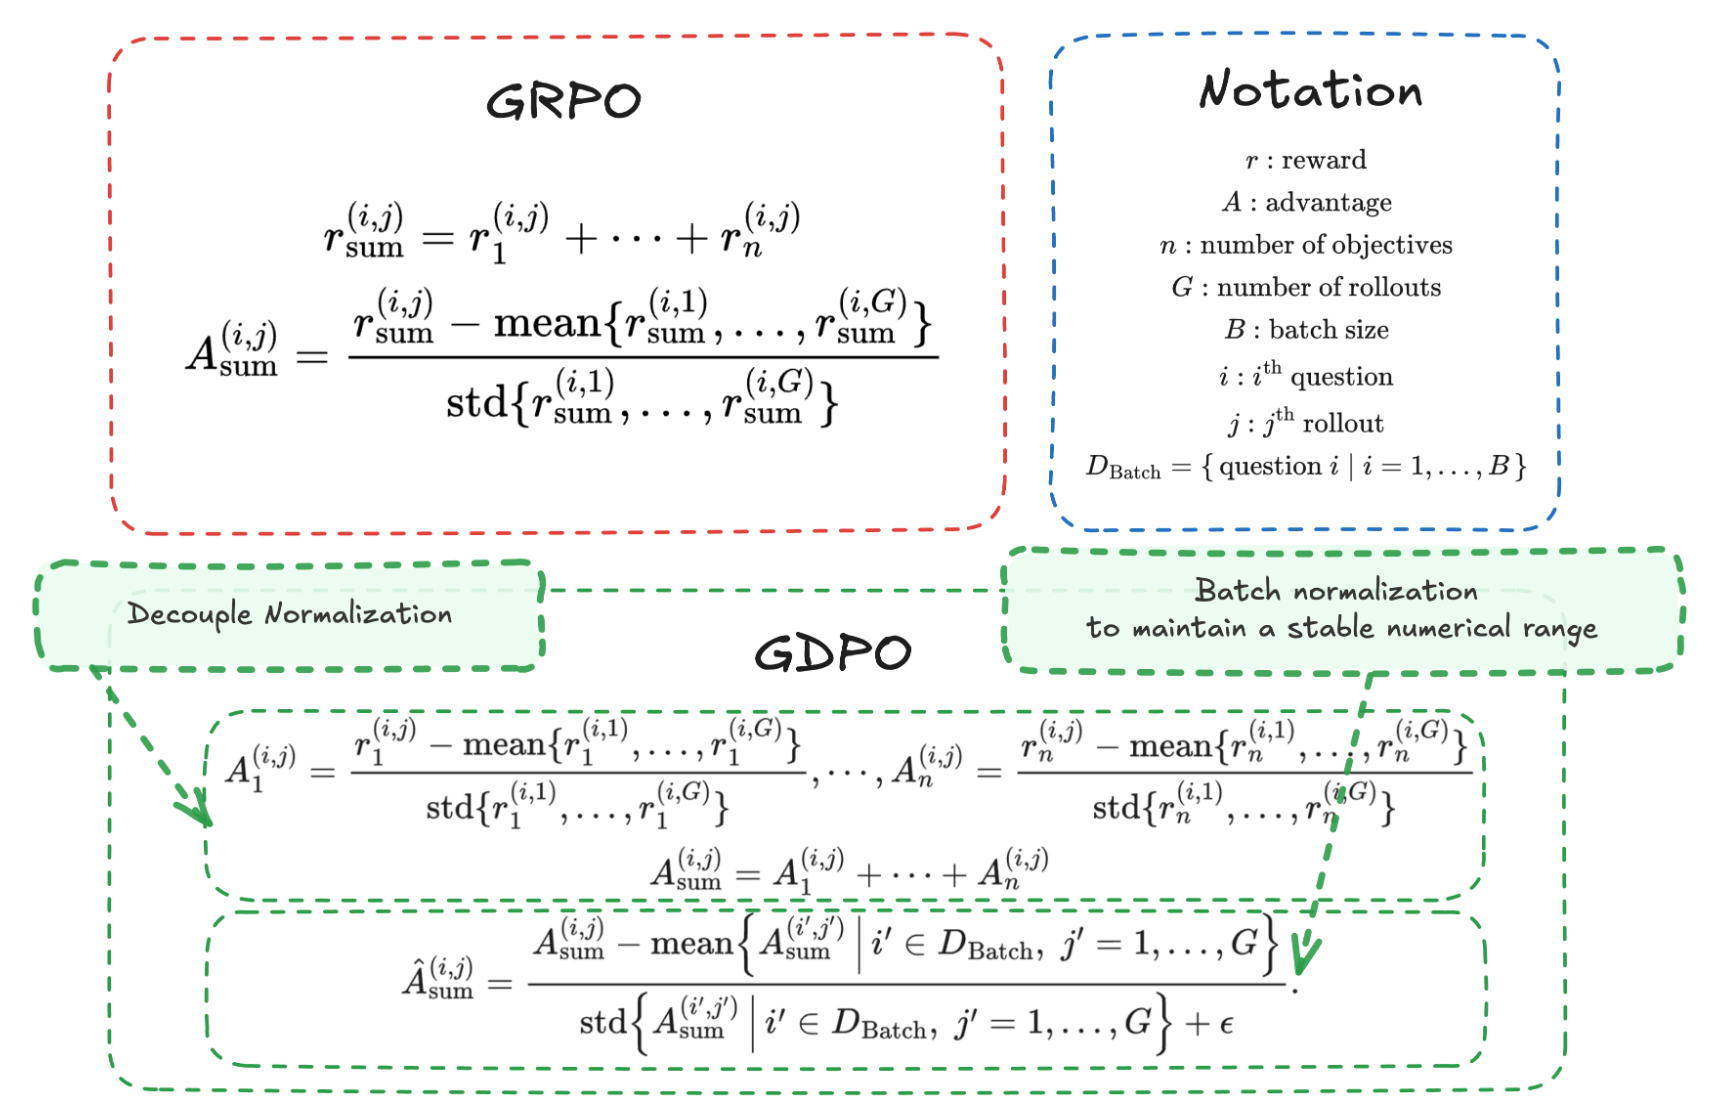
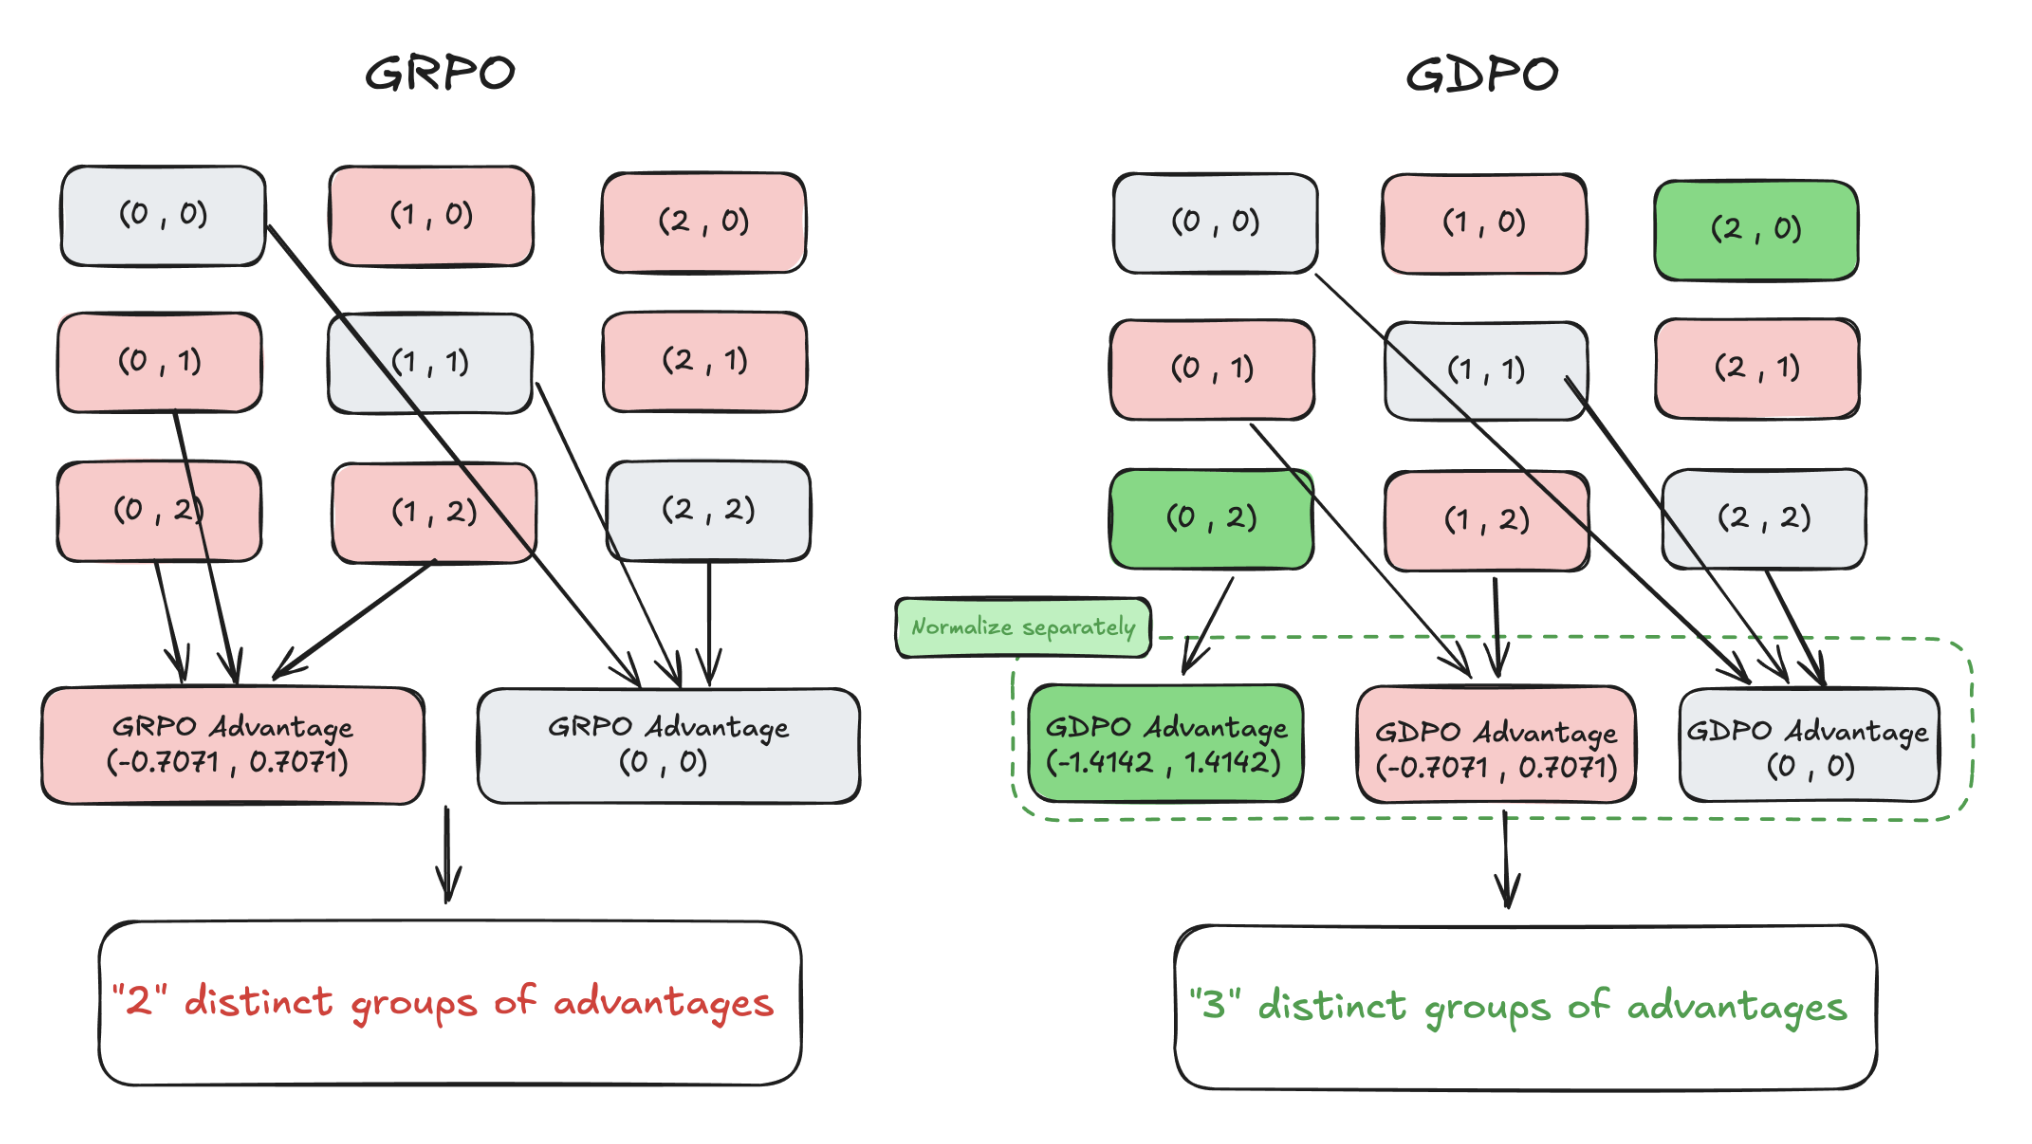
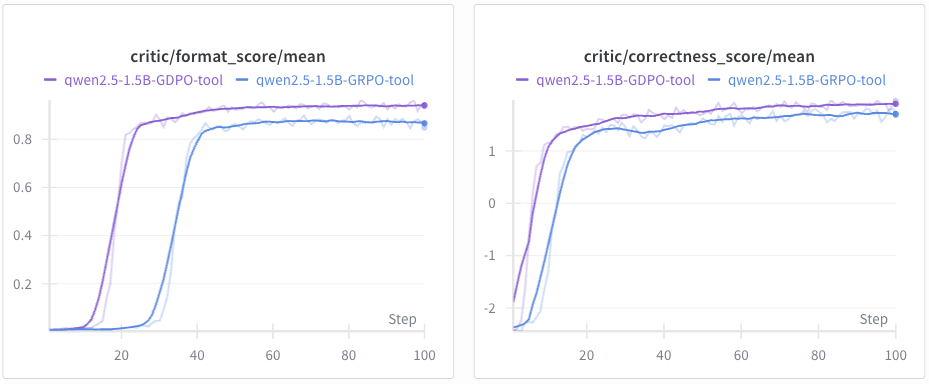
GDPO is a reinforcement learning optimization method designed for multi-reward training. While existing approaches commonly apply Group Relative Policy Optimization (GRPO) in multi-reward settings, we show that this leads to reward advantages collapse, reducing training signal resolution and causing unstable or failed convergence.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 5 months ago
- Stars
- 516
- +2 this week
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 96% of the code
Is it looked after?
- Contributors
- 0
- Last 90 days
- Issues
- 44% closed
- 5 still open
- Pull requests
- 0 merged
- 1 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| SkyworkAI / Skywork-R1V | 3,173 | 3 months ago | MIT | No downloads |
| meta-prompting / meta-prompting | 331 | 3 months ago | MIT | No downloads |
More: languages, topics and project record
Languages
- Python 96%
- Jupyter Notebook 3%
- Shell 1%
- Dockerfile <1%
Topics
- agentic-ai
- grpo
- llm
- reasoning
- rl
- trl
- verl
Project record
- JobOther AI tools
- StatusListed
- Commits31
- Forks38
- Watching3
- Stars in 28 days+3
- CreatedDec 9, 2025
- First seen by usNov 7, 2026
- CheckedNov 7, 2026