
raketenkater / ggrun
llama.cpp/ik_llama.cpp launcher: loads big MoE models across mismatched multi-GPU rigs by exact VRAM math.
Why this job: says: llama.cpp; topics: llama-cpp, llamacpp, local-llm, gguf
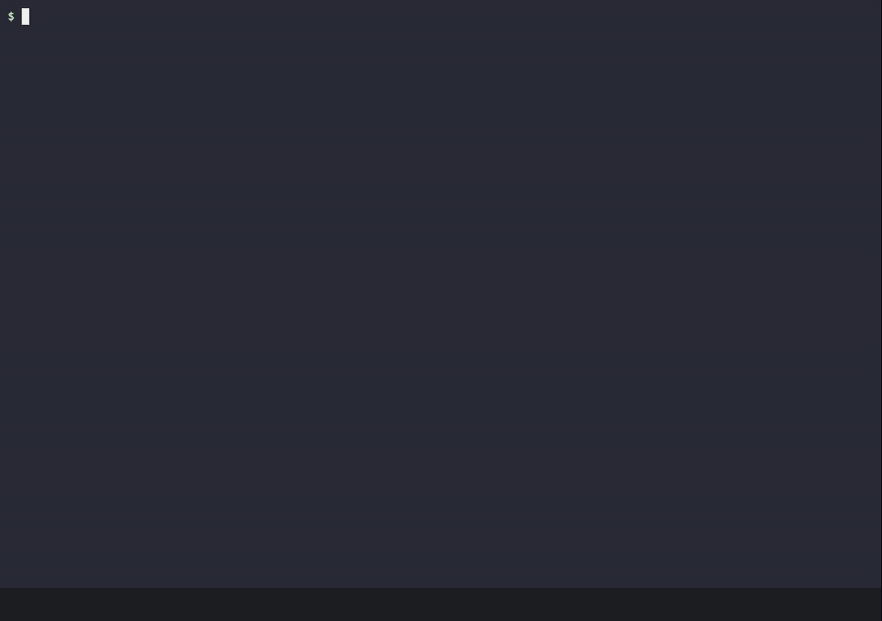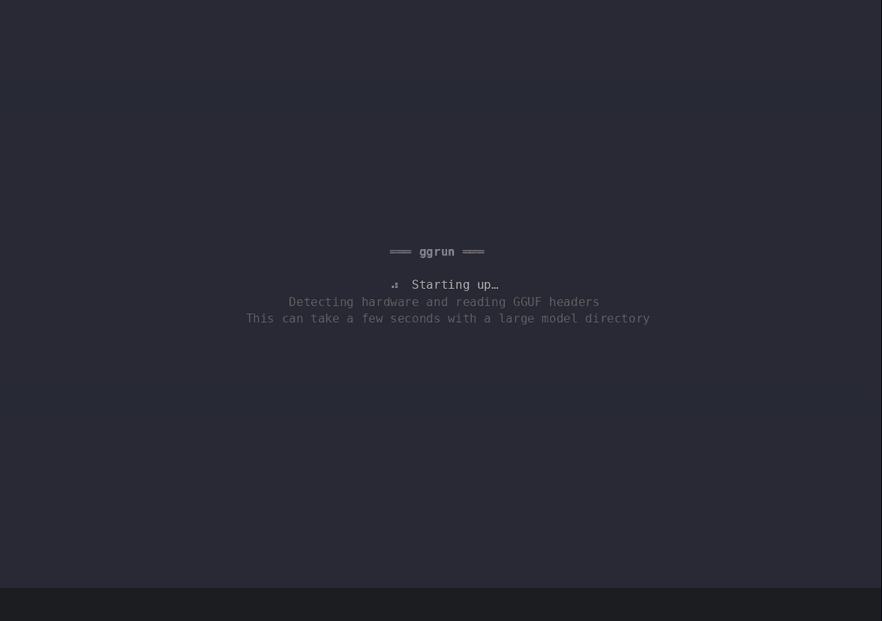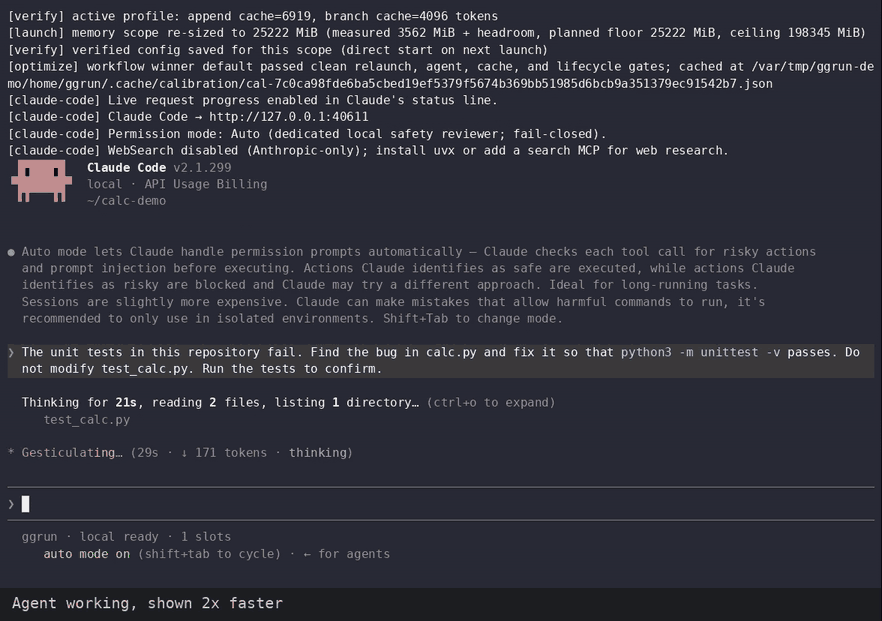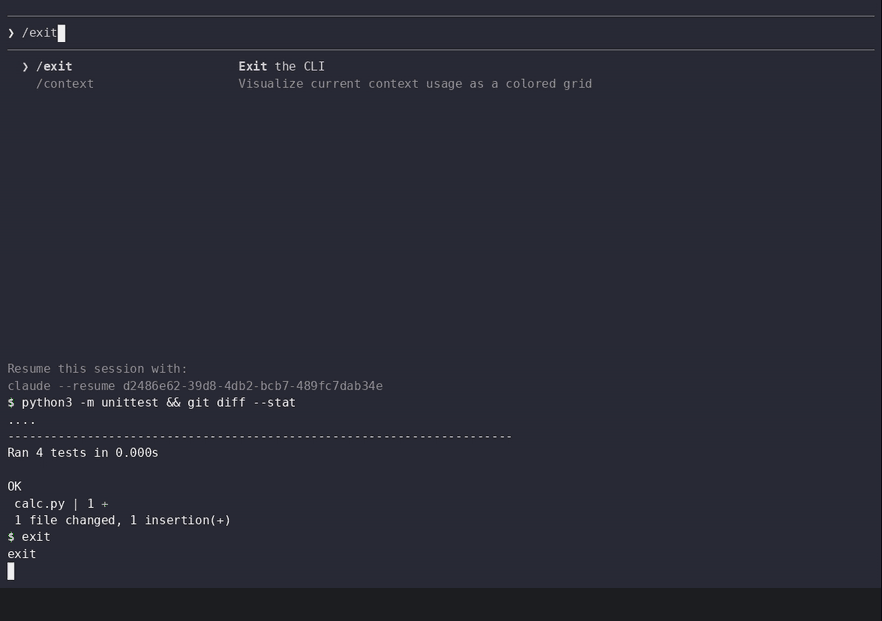
What it does
A launcher for llama.cpp and ik_llama.cpp. It recommends a model for your machine, places it across mismatched GPUs and RAM, and checks that it fits before it serves.
Get started
curl -fsSL https://raw.githubusercontent.com/raketenkater/ggrun/main/setup.sh | bash - Maintenance
- Active
- Last commit 2 days ago
- Stars
- 283
- On GitHub
- Licence
- MIT
- Allows business use
- Downloads for
- 2 systems
- Windows, Linux
- Latest version
- v3.2.13
- Released 11 days ago
- Built with
- Go
- 86% of the code
Is it looked after?
- Contributors
- 2
- Last 90 days
- Issues
- 76% closed
- 9 still open
- Pull requests
- 78 merged
- 5 waiting
- Releases
- 11
- 11 in the last year
- Contributing guide (opens in new tab)
- Security policy (opens in new tab)
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| jundot / omlx | 23,475 | 4 days ago | Apache-2.0 | Mac |
| thomas9120 / LLama-GUI | 139 | 3 days ago | GPL-3.0 | No downloads |
| dadwritestech / LlamaForge | 121 | 4 days ago | MIT | No downloads |
More: download files, languages, topics and project record
Download files, v3.2.13
- Windows1 file, 67 downloads
- Linux3 files, 46 downloads
Languages
- Go 86%
- Python 8%
- Shell 4%
- PowerShell 1%
Topics
- cuda
- gguf
- llama-cpp
- llm
- metal
- moe
- multi-gpu
- golang
- inference-server
- llamacpp
- local-llm
- localllama
Project record
- JobLocal LLMs
- StatusListed
- Commits1,011
- Forks18
- Watching3
- Stars in 28 days+2
- CreatedMar 11, 2026
- First seen by usNov 7, 2026
- CheckedNov 9, 2026