
Sandermage / sndr_core_engine
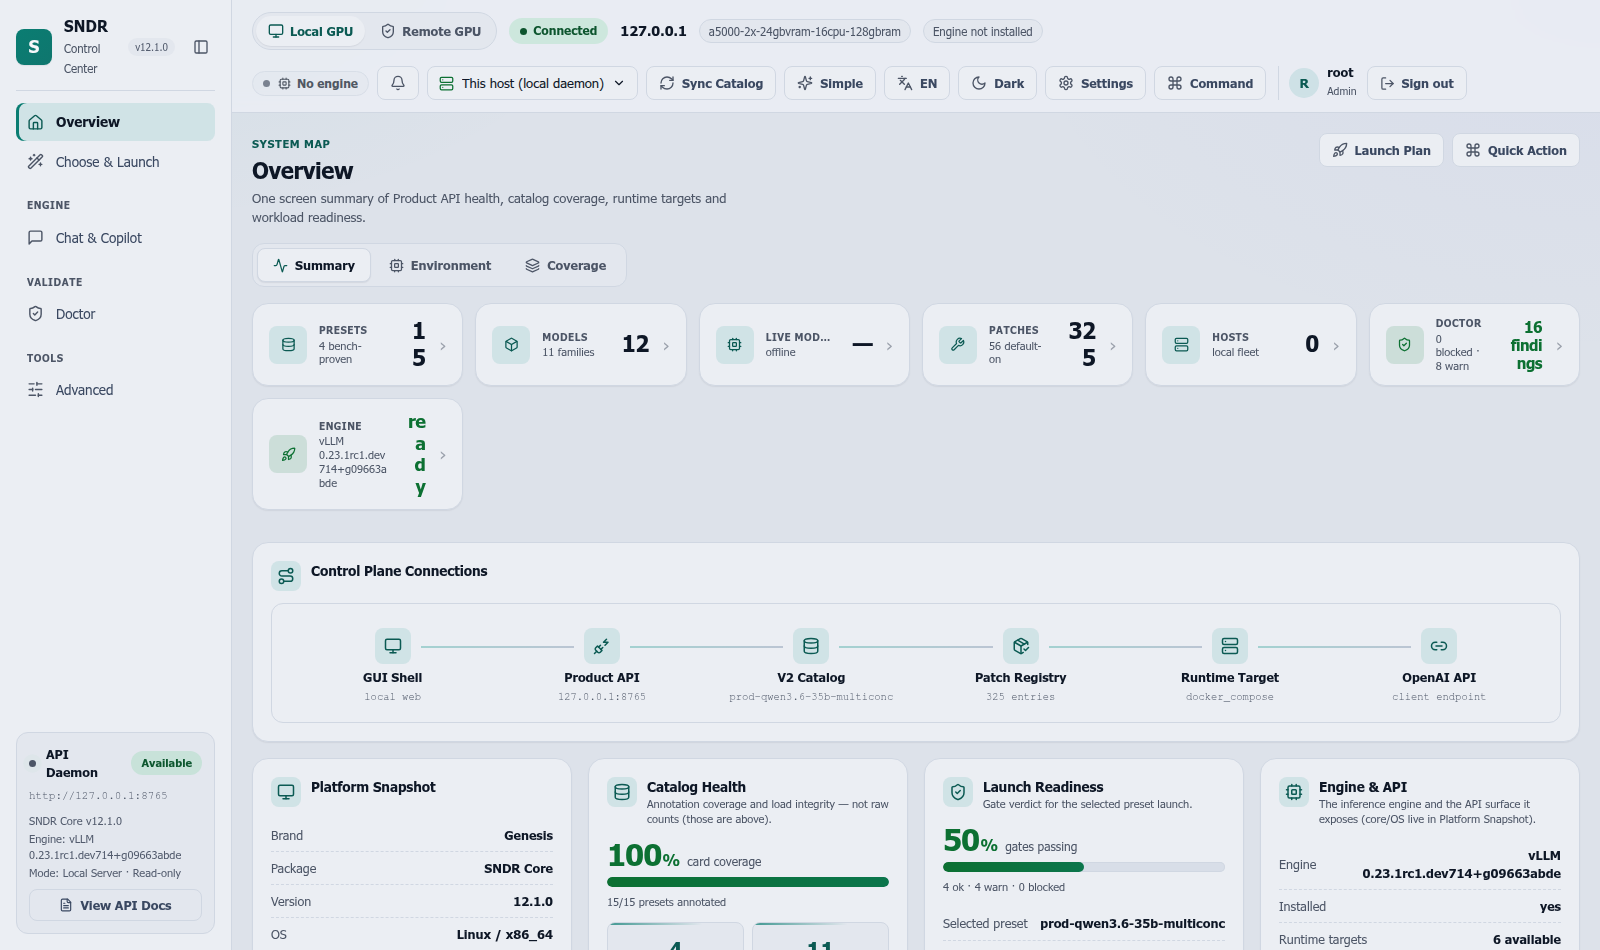
SNDR Core Engine (Genesis) — vLLM runtime patch-overlay for Qwen3.6 + Gemma4 on consumer NVIDIA (Ampere sm_86, 2× A5000/3090). Qwen3.6-35B-A3B FP8 ~240 tok/s, 27B-int4 hybrid GDN+Mamba, Gemma4 26B/31B AWQ, 256K ctx. 321 patches: TurboQuant k8v4 KV, MTP/DFlash spec-decode, FULL cudagraph, hybrid GDN. vLLM pin dev424 + Control Center GUI.
Why this job: topics: local-llm, llm-inference, vllm, llm-serving, quantization
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 4 months ago
- Stars
- 133
- On GitHub
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- v12.1.0
- Released 4 months ago
- Built with
- Python
- 90% of the code
Is it looked after?
- Contributors
- 0
- Last 90 days
- Issues
- 75% closed
- 5 still open
- Pull requests
- 38 merged
- 20 waiting
- Releases
- 2
- 2 in the last year
- Contributing guide (opens in new tab)
- Security policy (opens in new tab)
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| syv-ai / HyperQwen | 2,626 | 6 days ago | Apache-2.0 | No downloads |
| JakeATX / llamAmpere | 299 | today | MIT | No downloads |
| liguodongiot / llm-action | 25,266 | 26 days ago | Apache-2.0 | No downloads |
More: languages, topics and project record
Languages
- Python 90%
- TypeScript 6%
- CSS 2%
- Shell 1%
Topics
- awq
- consumer-gpu
- cuda
- gemma
- kv-cache-quantization
- llm-inference
- llm-serving
- local-llm
- memory
- pgvector
- quantization
- qwen
Project record
- JobLocal LLMs
- StatusListed
- Commits376
- Forks6
- Watching4
- Stars in 28 days0
- CreatedApr 17, 2026
- First seen by usNov 7, 2026
- CheckedNov 7, 2026