
scub-france / docling-Studio
Visual document analysis studio powered by Docling — configure the extraction pipeline, inspect text, tables and bounding boxes in the browser, then chunk, embed and index into OpenSearch and Neo4j.
Why this job: topics: rag, embeddings, vector-search, knowledge-graph, document-parsing, ocr
What it does
- Runs Docling on your PDFs, in the container or on your own Docling Serve server.
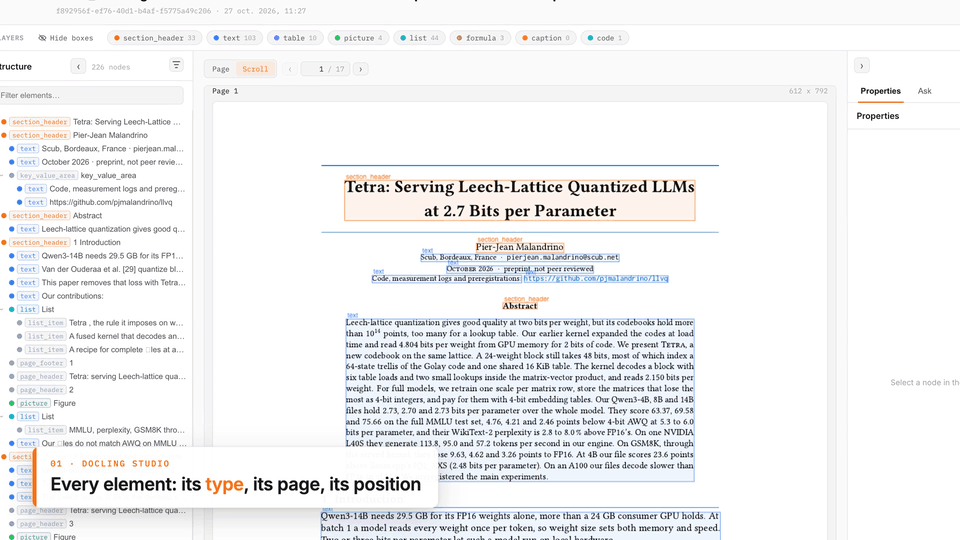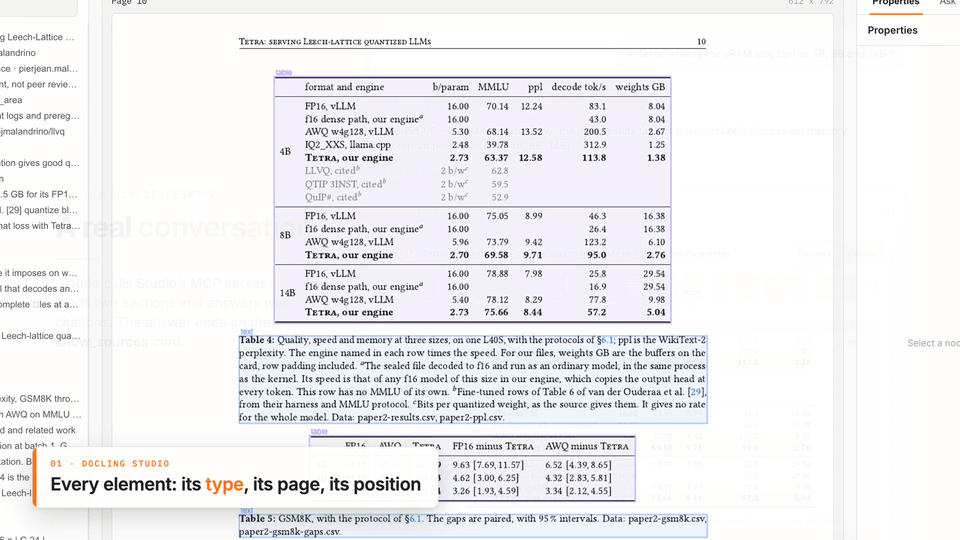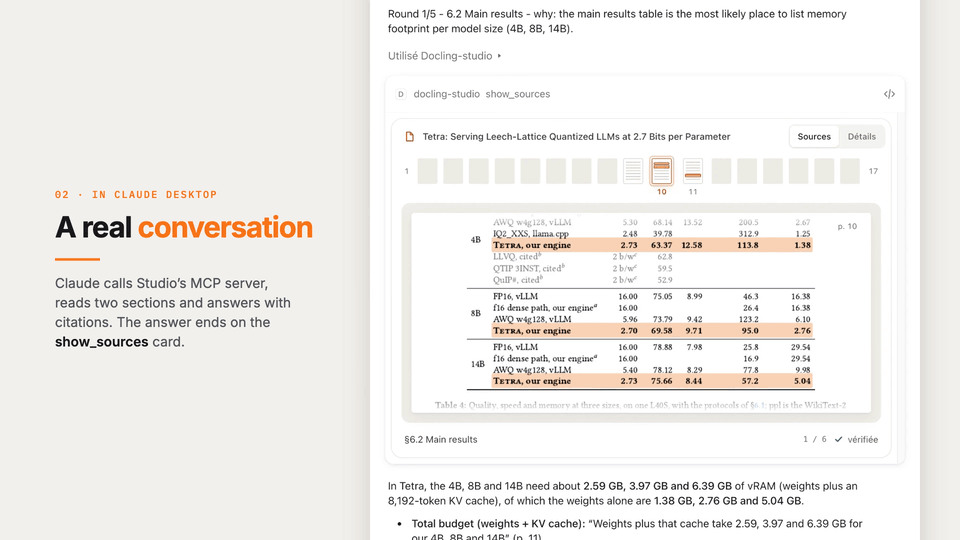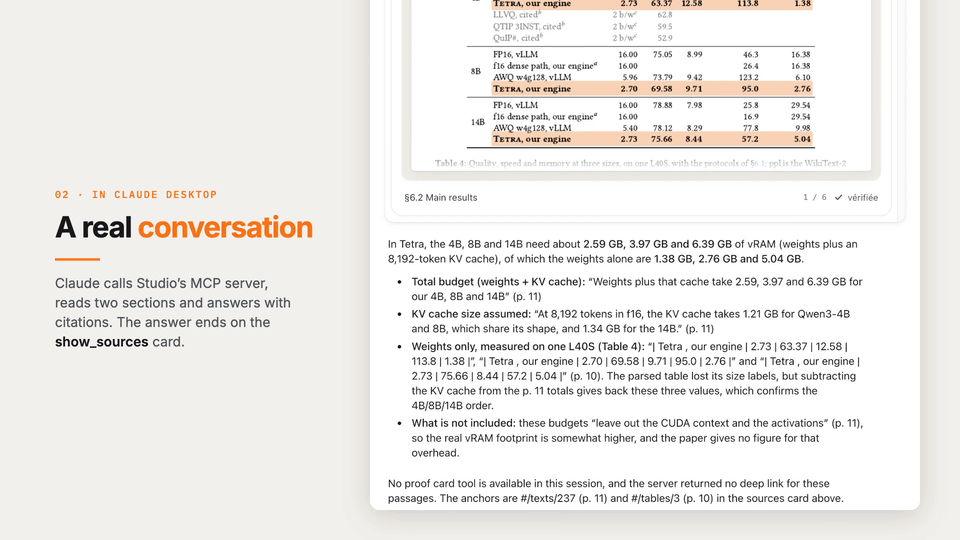
- Draws the box of every element on the page, next to the document tree.
- Shows the text or the table of the element you click. Element types can be hidden.
- Answers questions about a document with a local model (Ollama), and shows the steps it took.
- Exports the result as Markdown or Docling JSON.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 7 days ago
- Stars
- 271
- +1 this week
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- v0.7.3
- Released 8 days ago
- Built with
- Python
- 56% of the code
Is it looked after?
- Contributors
- 3
- Last 90 days
- Issues
- 73% closed
- 57 still open
- Pull requests
- 149 merged
- 6 waiting
- Releases
- 10
- 10 in the last year
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| run-llama / ParseBench | 628 | 4 days ago | Apache-2.0 | No downloads |
| FengZhenfei / carrel | 802 | yesterday | MIT | No downloads |
| aiptimizer / TurboOCR | 1,159 | 44 days ago | MIT | No downloads |
More: languages, topics and project record
Languages
- Python 56%
- Vue 19%
- TypeScript 16%
- HTML 4%
Topics
- chunking
- docling
- document-ai
- document-parsing
- embeddings
- fastapi
- knowledge-graph
- neo4j
- ocr
- opensearch
- pdf-extraction
- rag
Project record
- JobRAG and search
- StatusListed
- Commits666
- Forks29
- Watching1
- Stars in 28 days+9
- CreatedMay 13, 2025
- First seen by usNov 7, 2026
- CheckedNov 7, 2026