
tetsuo-ai / voice_clone_lab
Clone a voice from a few minutes of audio and generate speech locally: Qwen3-TTS fine-tuning pipeline with CLI and web UI
Why this job: says: tts; topics: text-to-speech, tts, voice-cloning
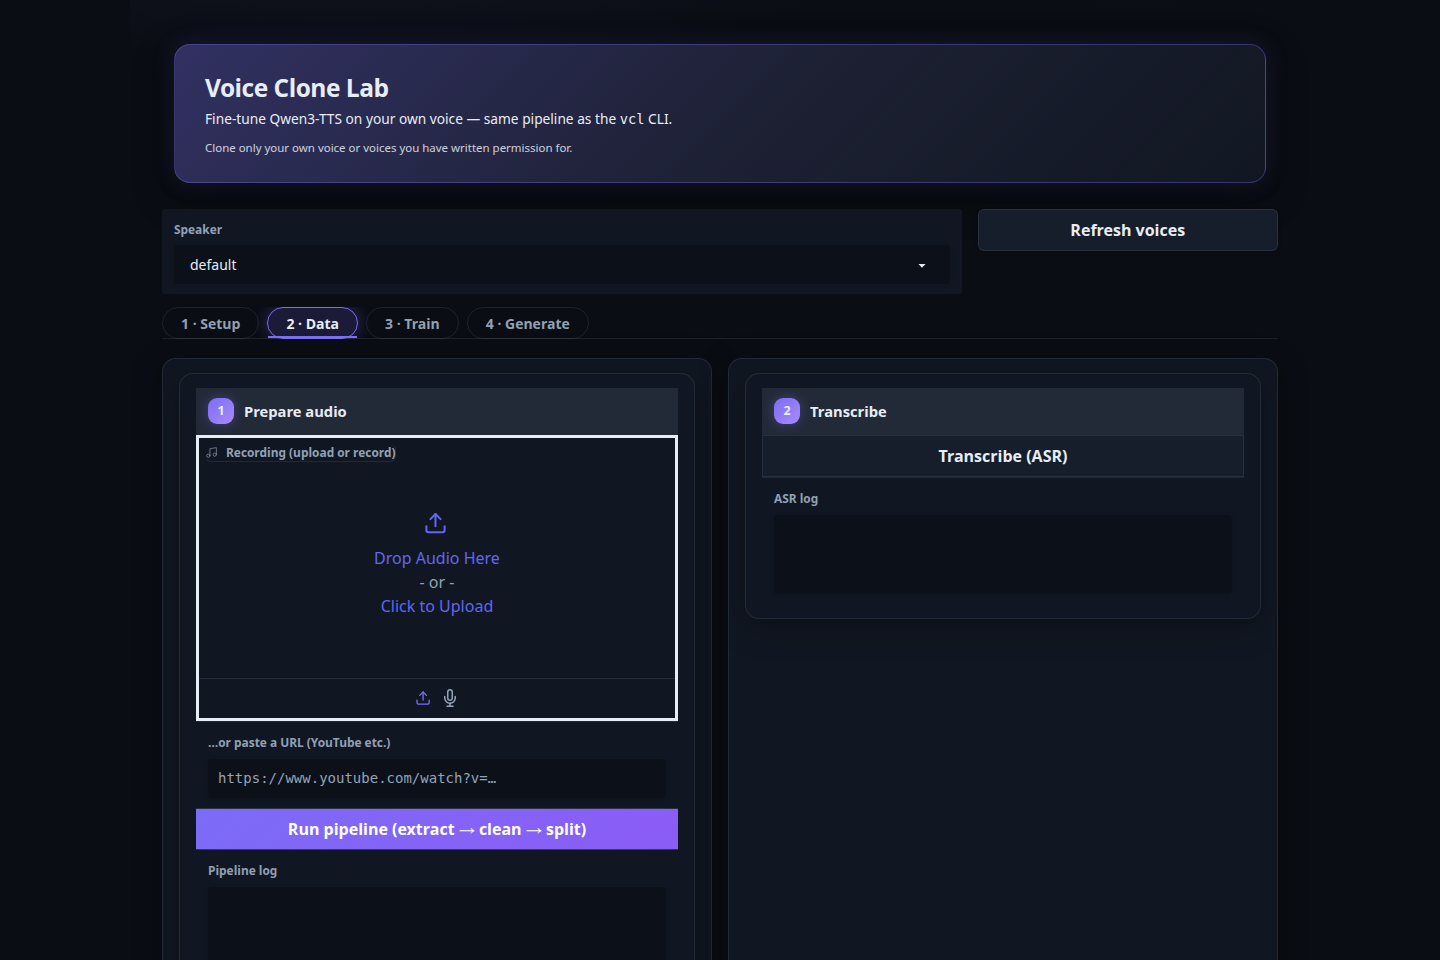
What it does
Clone a voice from a few minutes of audio and generate speech from text — locally, on your own GPU. Give it 5–15 minutes of clean speech (a recording, or a YouTube link) and it fine-tunes Qwen3-TTS into a personal voice model you can drive from a CLI or a web UI.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 3 months ago
- Stars
- 155
- On GitHub
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 100% of the code
Is it looked after?
- Contributors
- 0
- Last 90 days
- Issues
- 0% closed
- 2 still open
- Pull requests
- 0 merged
- 0 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| RVC-Boss / GPT-SoVITS | 64,596 | 9 days ago | MIT | No downloads |
| abus-aikorea / voice-pro | 13,417 | 3 months ago | GPL-3.0 | No downloads |
| Aratako / Irodori-TTS | 1,575 | today | MIT | No downloads |
More: languages, topics and project record
Languages
- Python 100%
Topics
- gradio
- python
- qwen
- text-to-speech
- tts
- voice-cloning
Project record
- JobSpeech and audio
- StatusListed
- Commits2
- Forks21
- Watching2
- Stars in 28 days+3
- CreatedJul 18, 2026
- First seen by usNov 7, 2026
- CheckedNov 7, 2026