
THU-BPM / RLCSD
Source code of paper "RLCSD: Reinforcement Learning with Contrastive On-Policy Self-Distillation"
Why this job: says: reinforcement learning, distillation; topics: reinforcement-learning
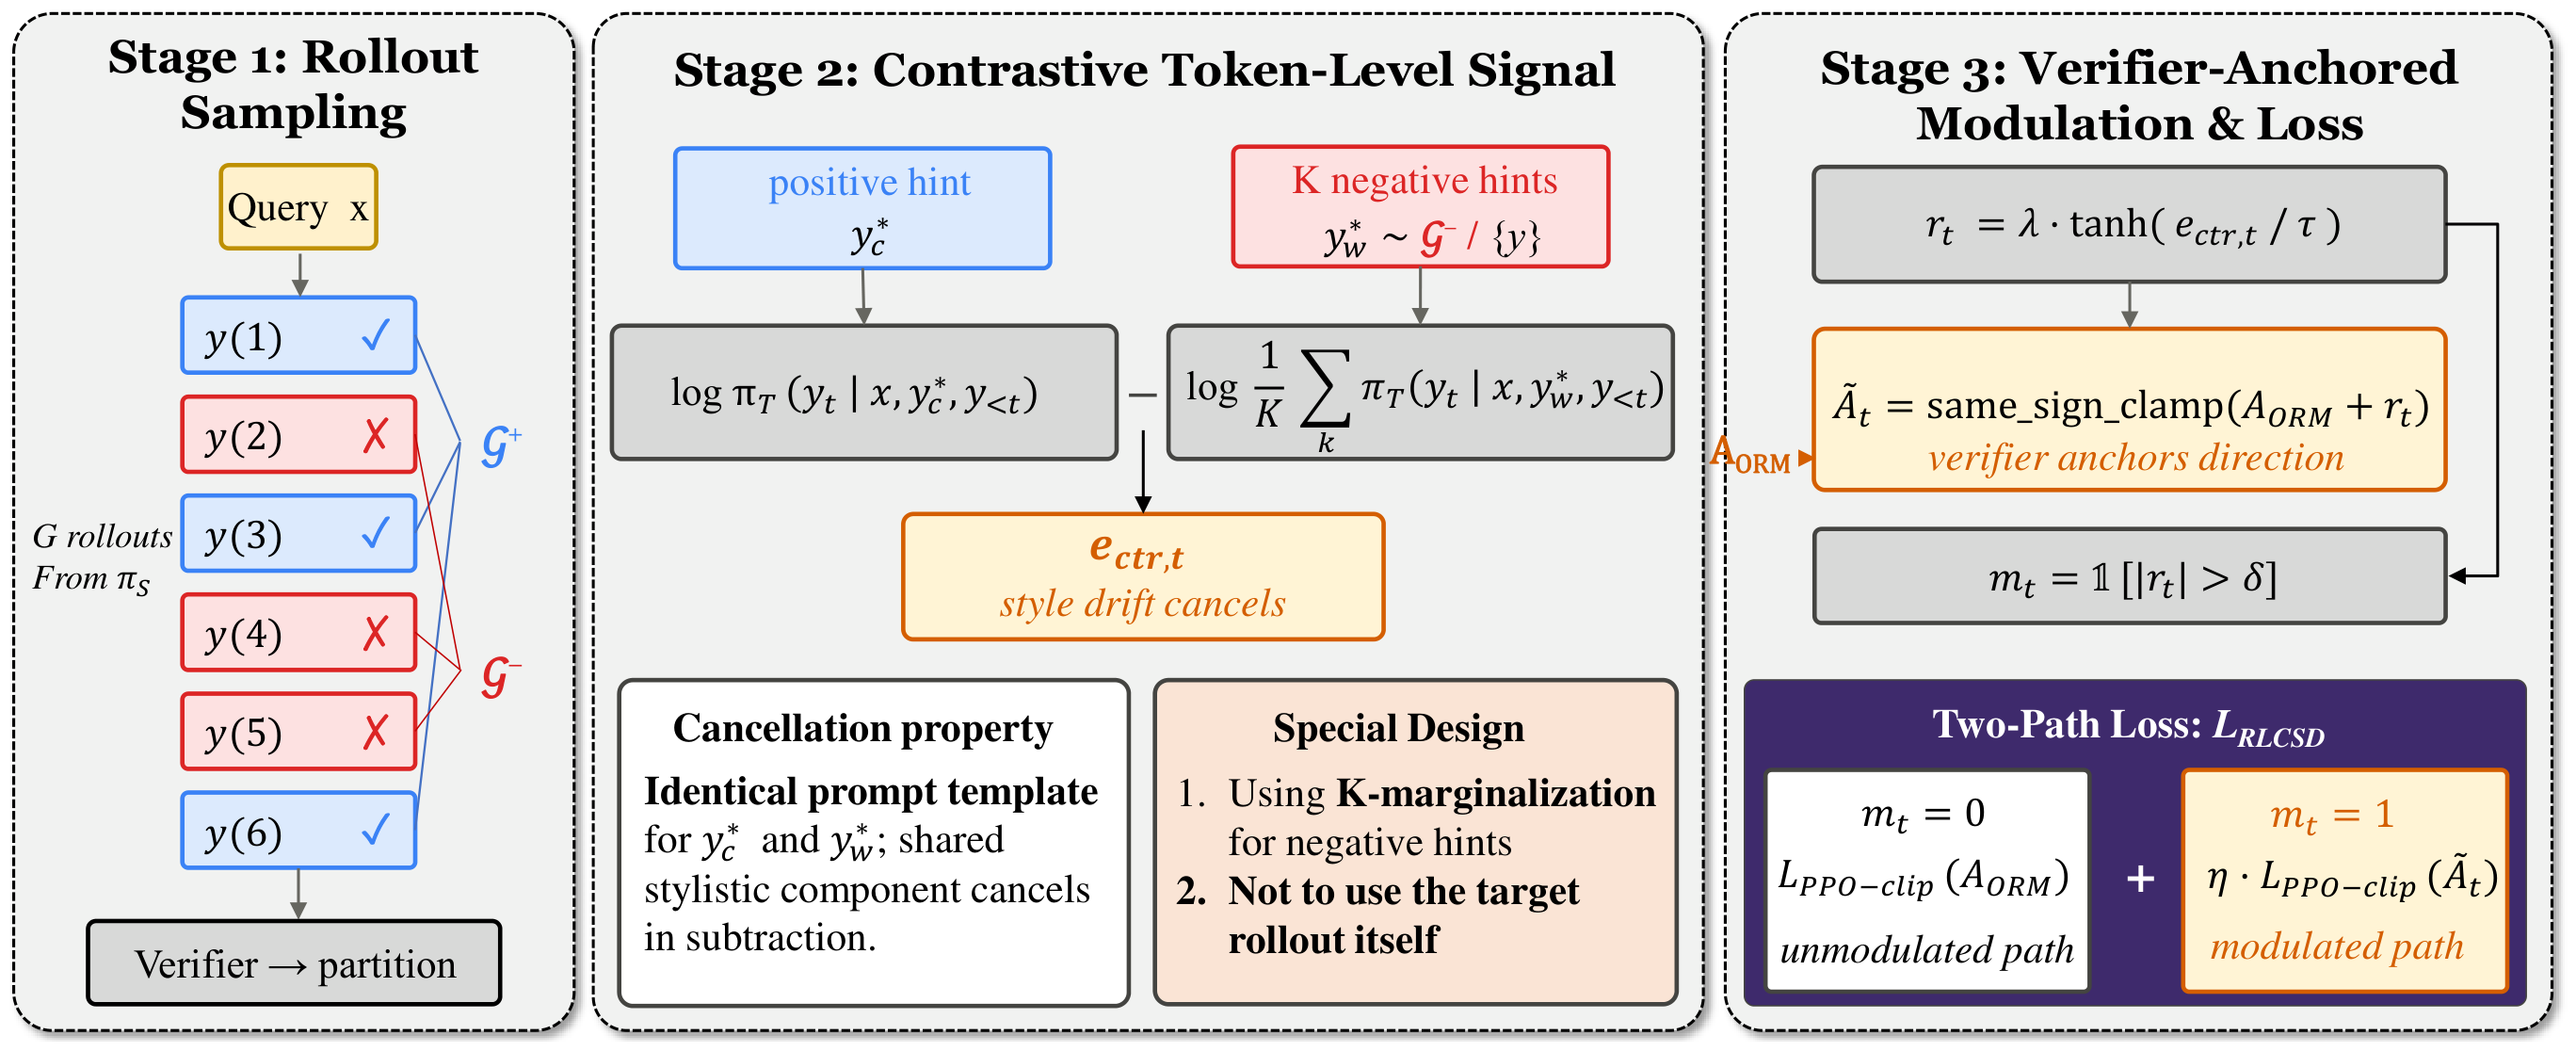
What it does
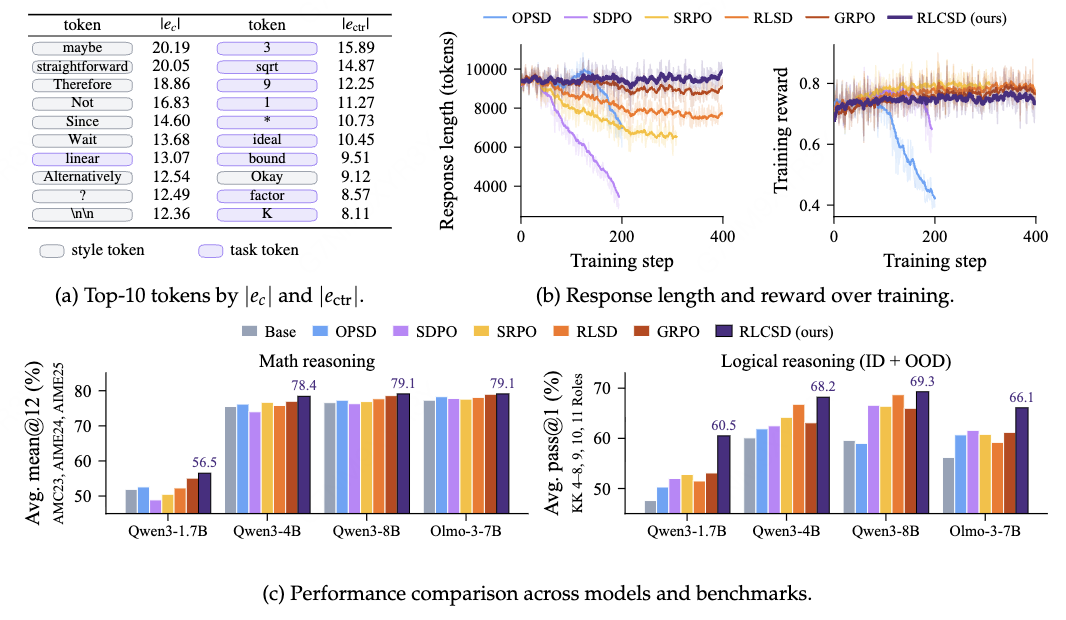
Across Qwen3 (1.7B / 4B / 8B) and Olmo-3-7B-Think, RLCSD achieves the highest math and logic averages among the evaluated methods. Math training uses DeepMath, with evaluation on AMC23, AIME24, and AIME25; logical reasoning uses Knights & Knaves at both in-domain and harder out-of-domain role counts.
Get started
# Recommended: a fresh Python 3.10–3.12 env
pip install -r requirements.txt- Maintenance
- Active
- Last commit 57 days ago
- Stars
- 116
- +1 this week
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 83% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 89% closed
- 1 still open
- Pull requests
- 0 merged
- 0 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| alessiodm / drl-zh | 2,293 | 5 months ago | MIT | No downloads |
| DaoyuanLi2816 / mini-verl | 310 | 56 days ago | Apache-2.0 | No downloads |
More: languages, topics and project record
Languages
- Python 83%
- Shell 17%
Topics
- large-language-models
- llm
- on-policy-distillation
- opd
- opsd
- reinforcement-learning
- self-distillation
Project record
- JobFine-tuning
- StatusListed
- Commits20
- Forks5
- Watching2
- Stars in 28 days+2
- CreatedJun 5, 2026
- First seen by usNov 7, 2026
- CheckedNov 8, 2026