
THUDM / IndexCache
IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse
Why this job: works in the areas we cover, but does not say which job it does
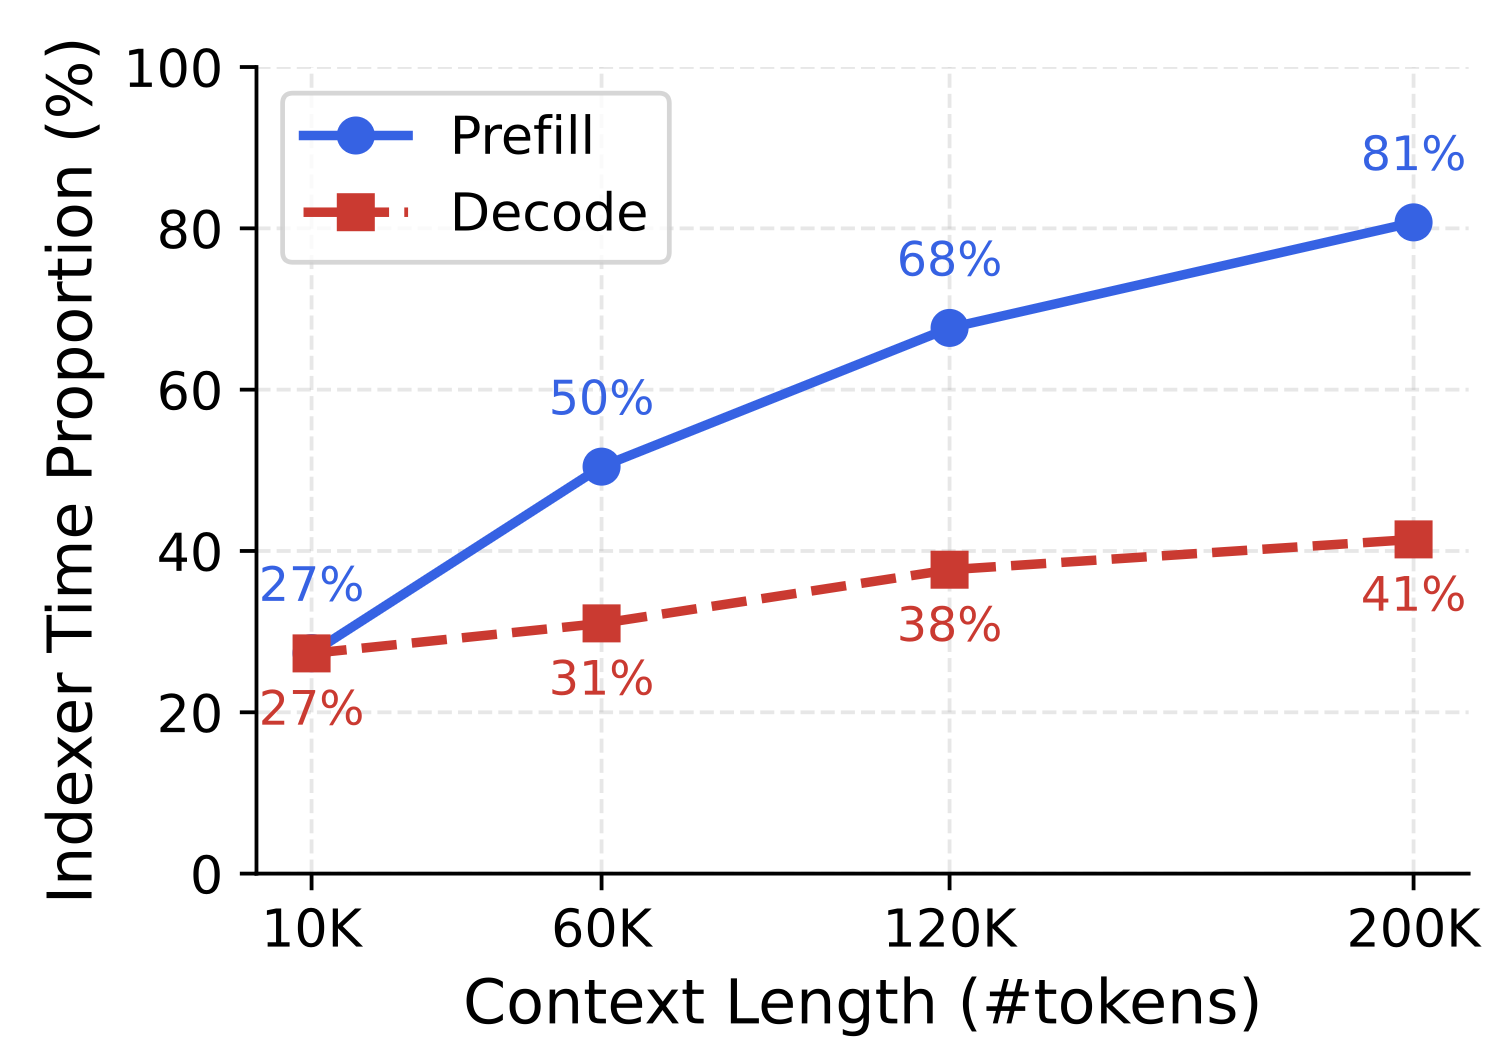
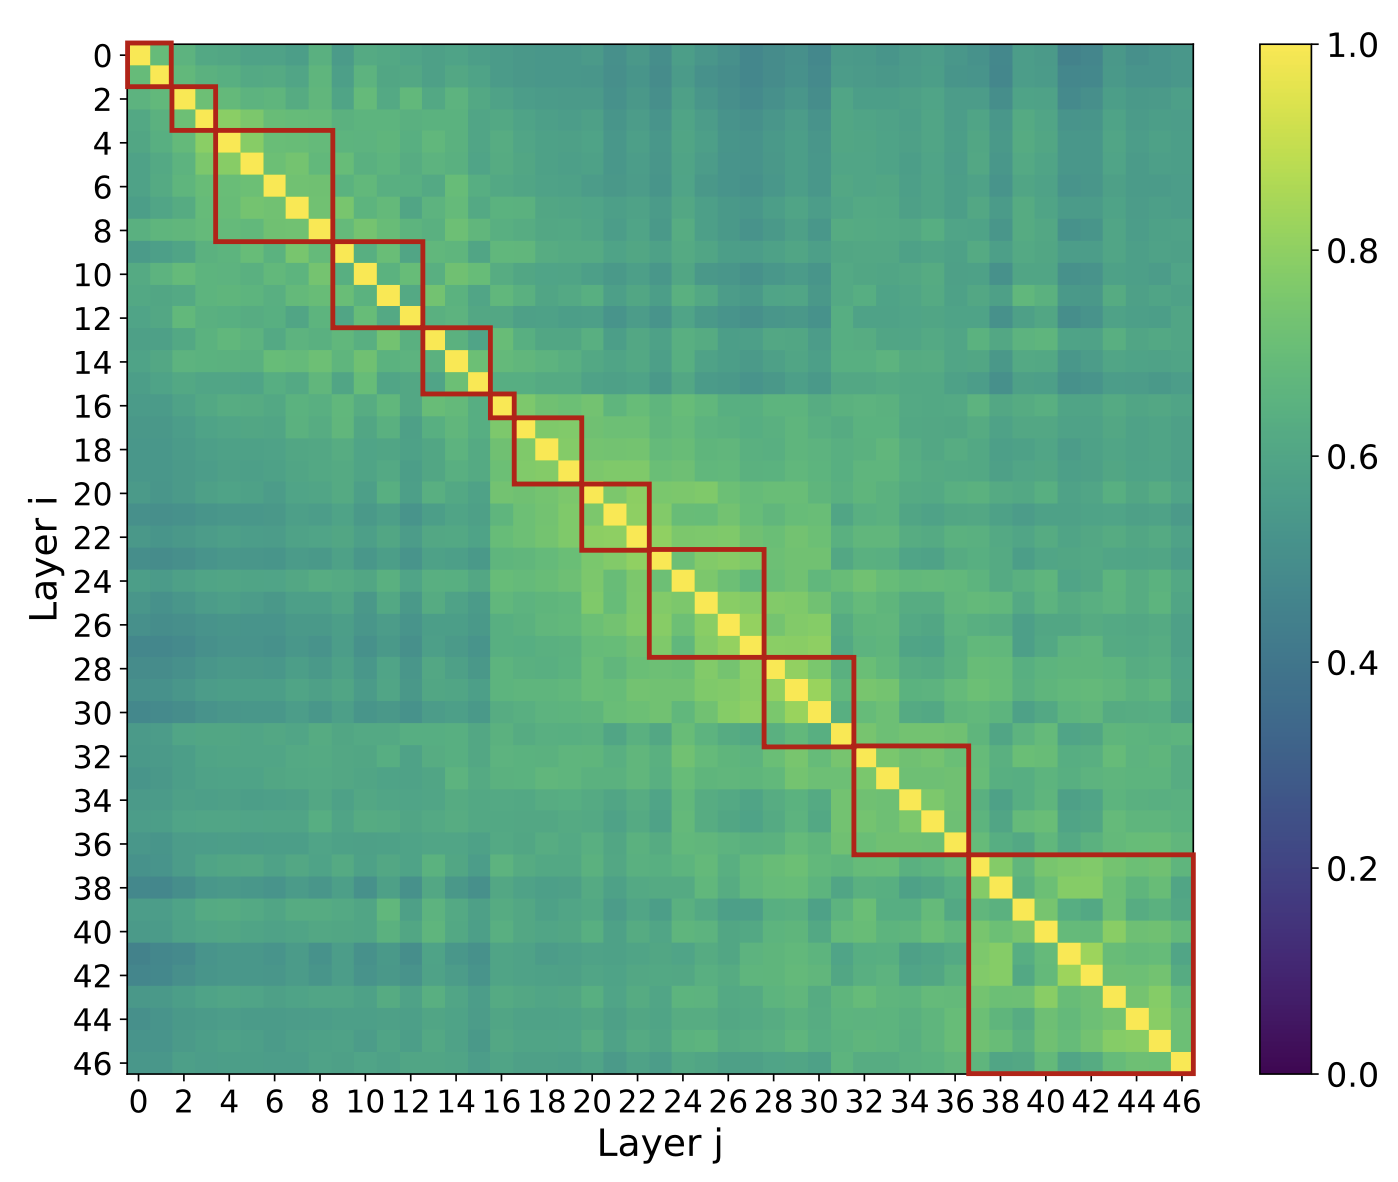
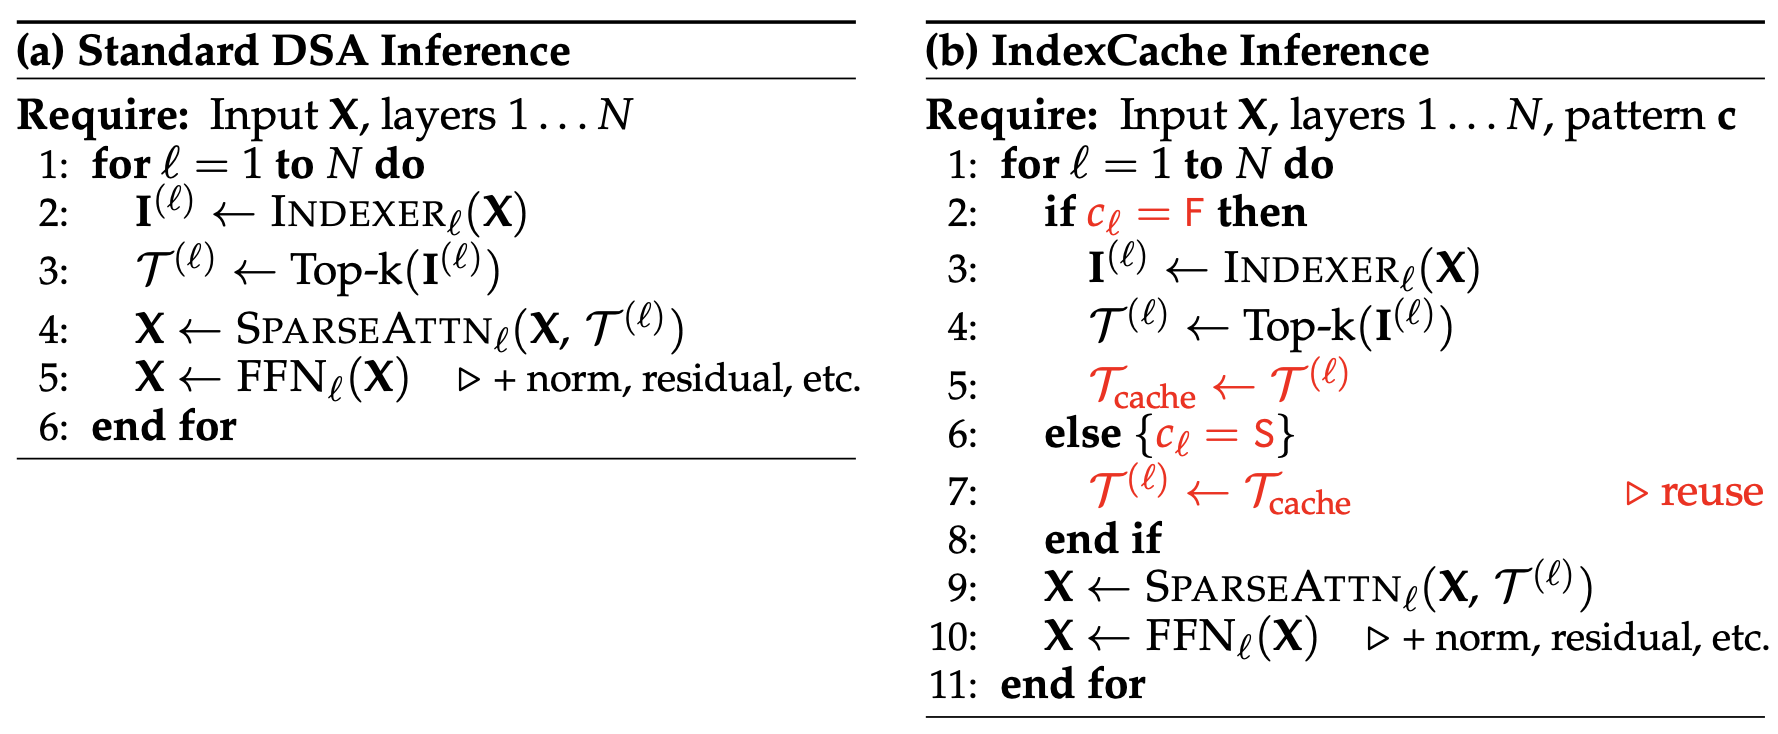
What it does
This repository provides a patch for SGLang and vLLM that enables IndexCache inference acceleration for models using DeepSeek Sparse Attention (DSA), including DeepSeek-V3.2 and GLM-5.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Inactive
- Last commit 8 months ago
- Stars
- 147
- On GitHub
- Licence
- Custom
- Read before business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Not stated
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 12% closed
- 7 still open
- Pull requests
- 0 merged
- 1 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| ollama / ollama | 186,709 | 2 days ago | MIT | Mac, Windows, Linux |
| mindsdb / mindshub | 39,859 | 20 days ago | MIT | No downloads |
| ZSeven-W / rish-app | 163 | 3 days ago | MIT | No downloads |
More: topics and project record
Topics
- deepseek
- glm
- llm
- long-context
- sparse-attention
Project record
- JobOther AI tools
- StatusListed
- Commits6
- Forks11
- Watching2
- Stars in 28 days+3
- CreatedMar 13, 2026
- First seen by usNov 7, 2026
- CheckedNov 8, 2026