
vaexio / vaex
Out-of-Core hybrid Apache Arrow/NumPy DataFrame for Python, ML, visualization and exploration of big tabular data at a billion rows per second 🚀
Why this job: works in the areas we cover, but does not say which job it does


What it does
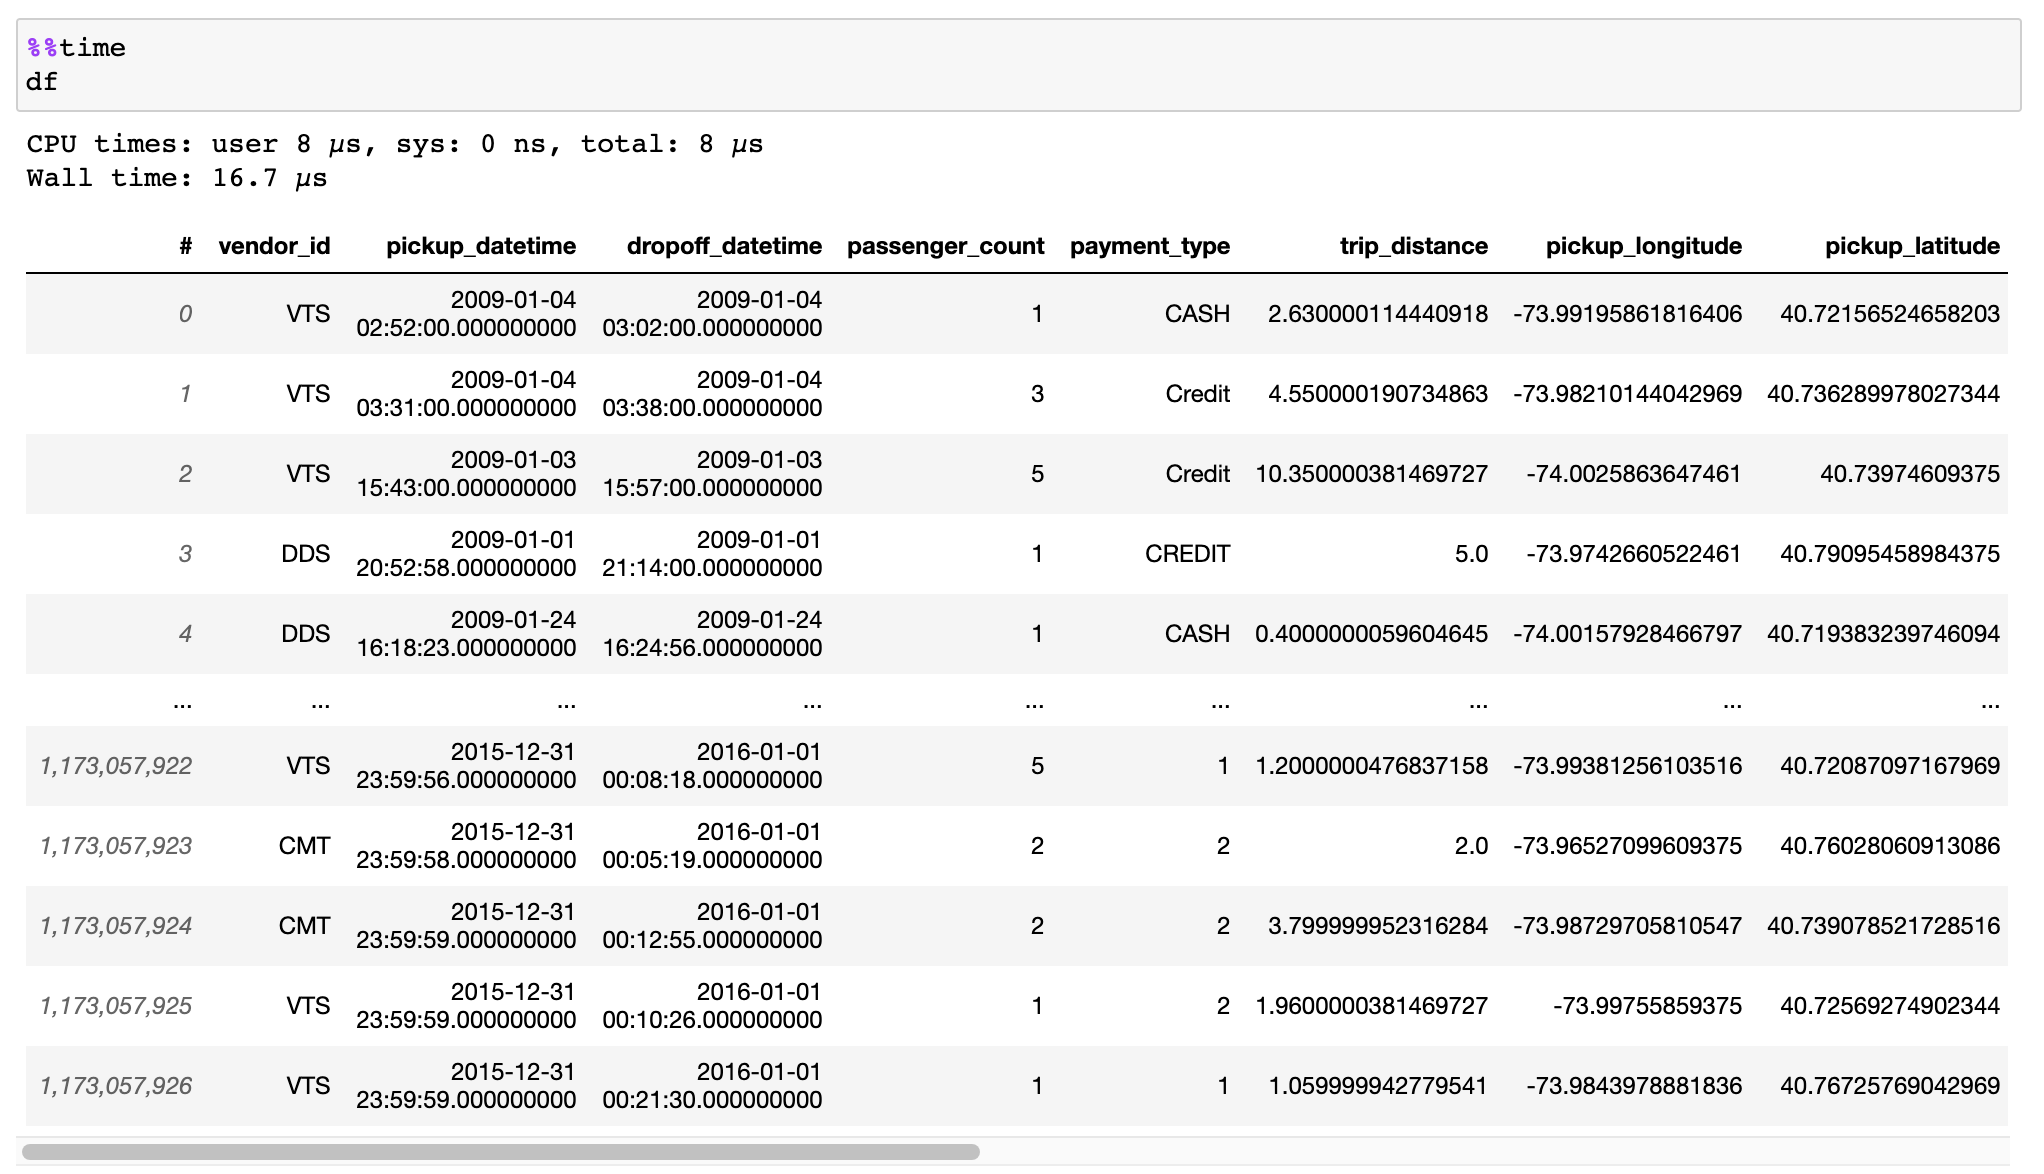
- Instant opening of Huge data files (memory mapping)
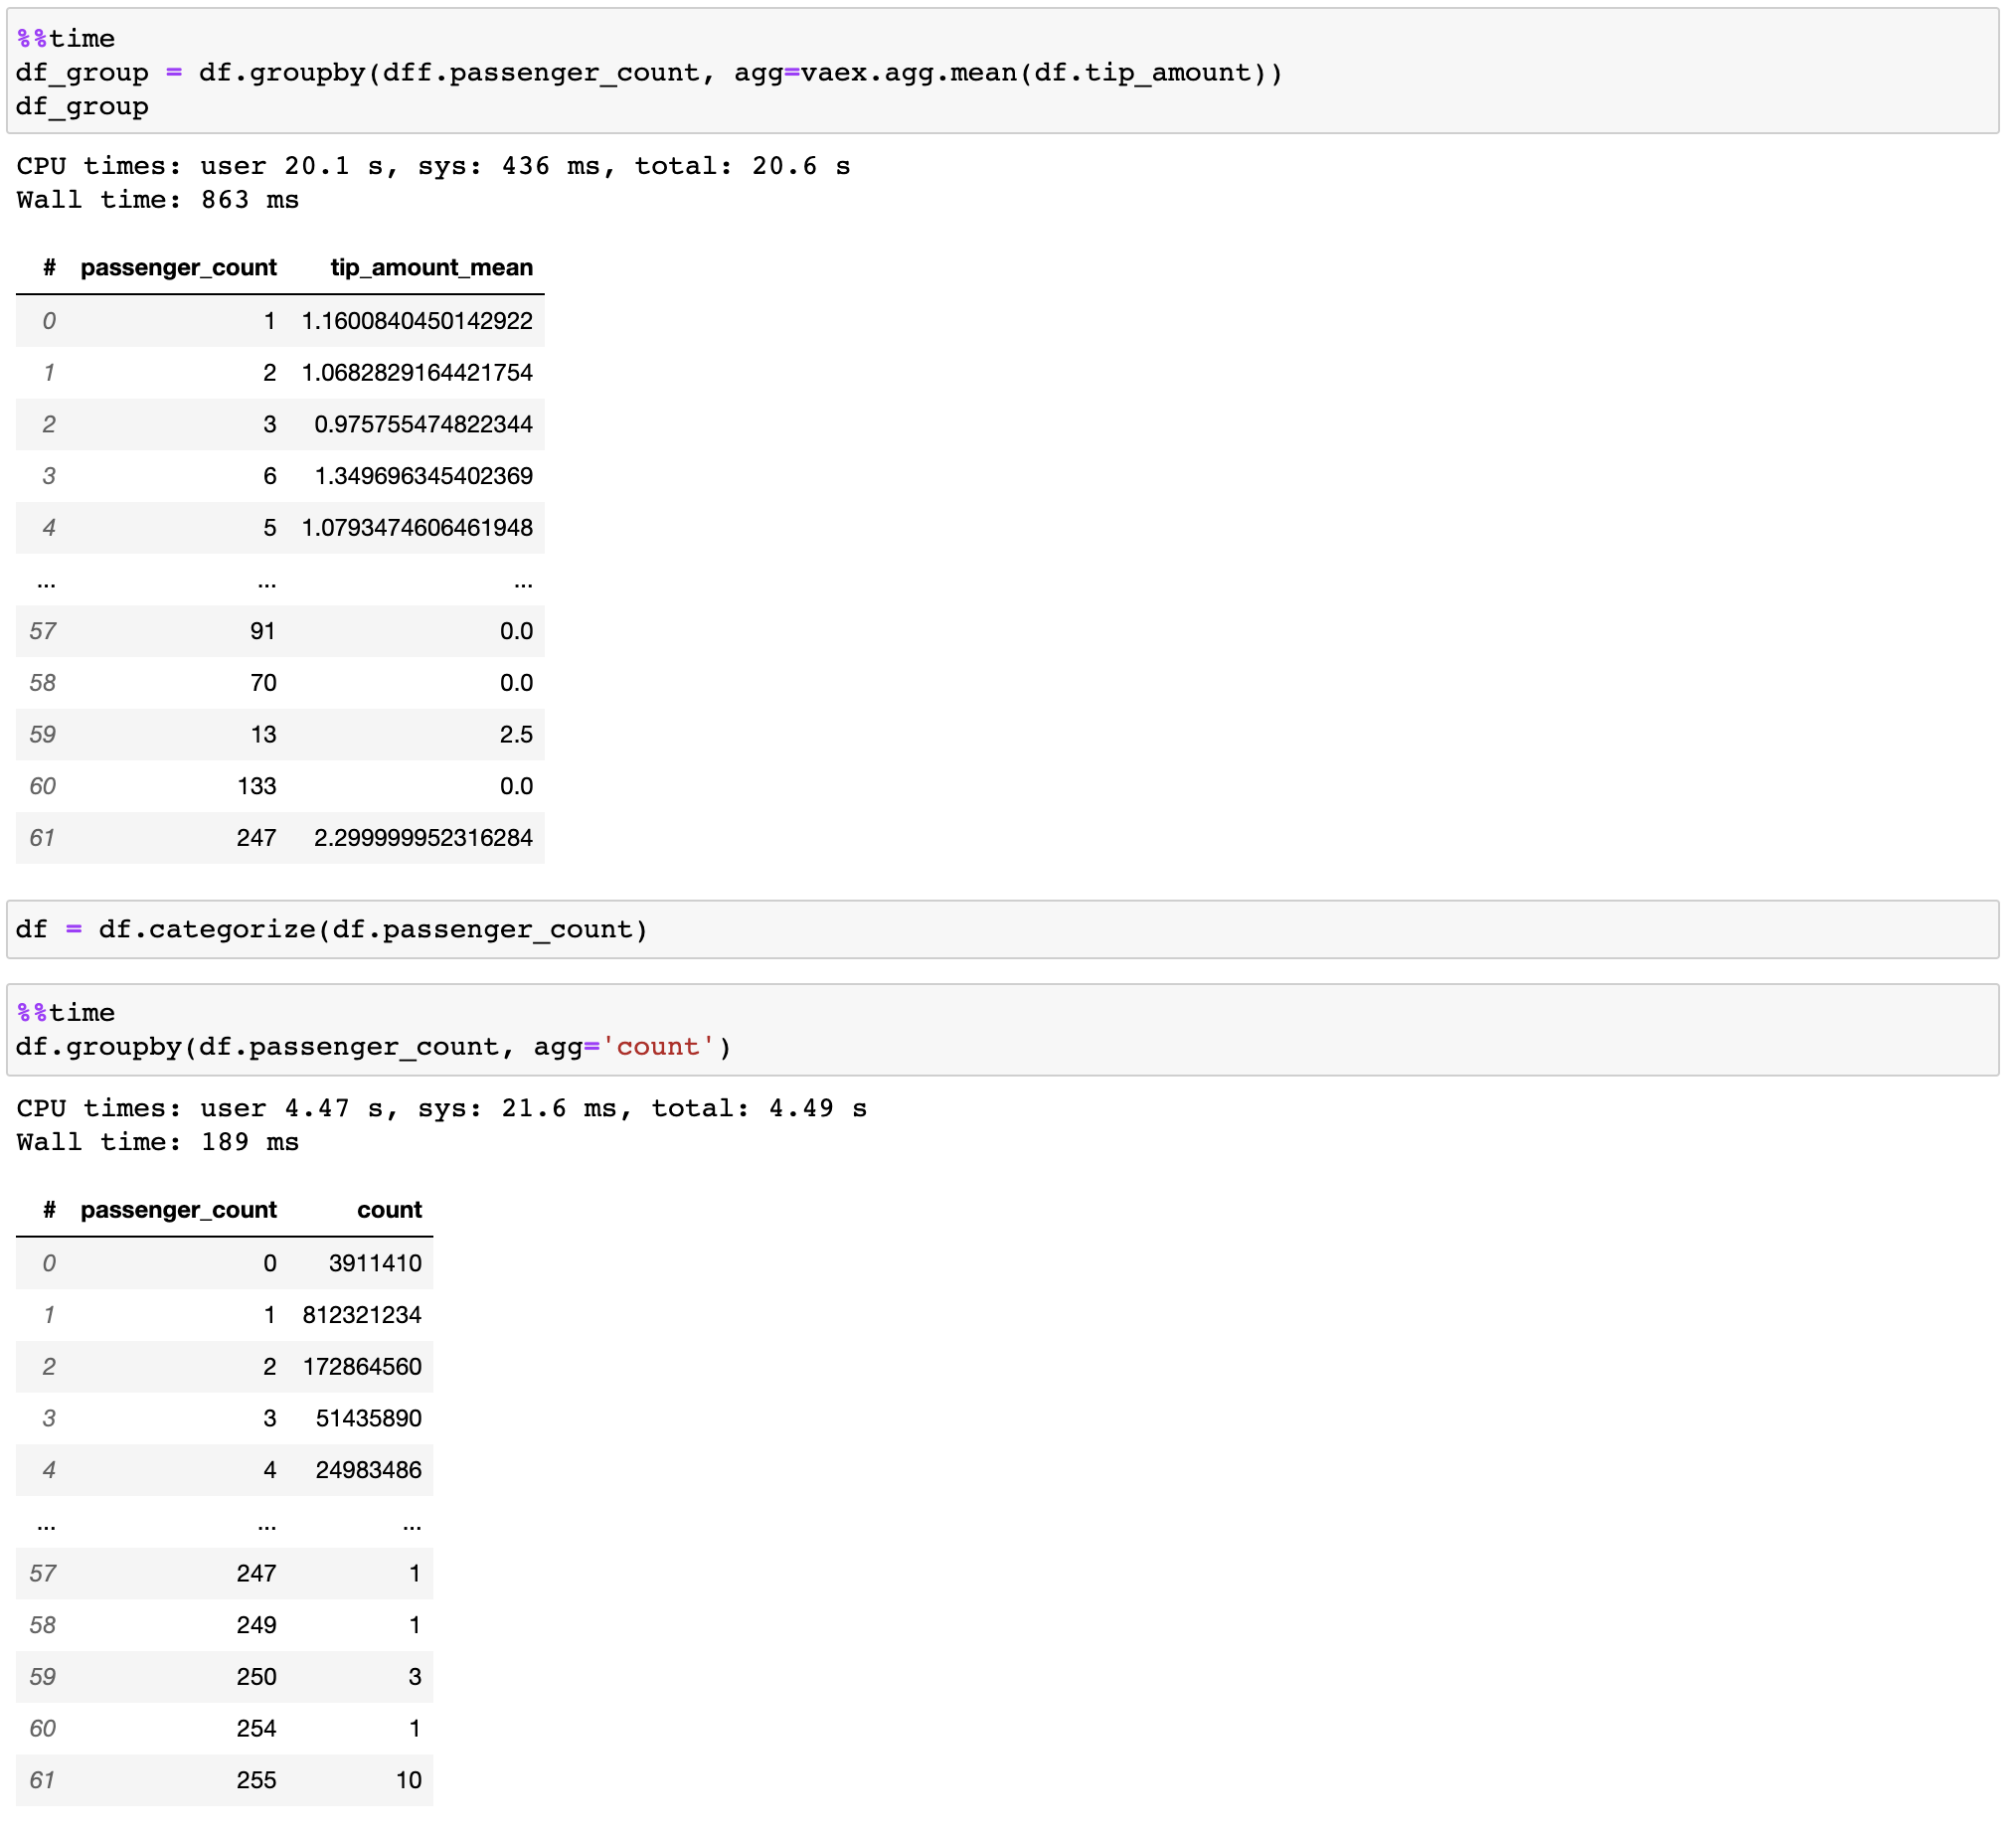
- Fast groupby / aggregations
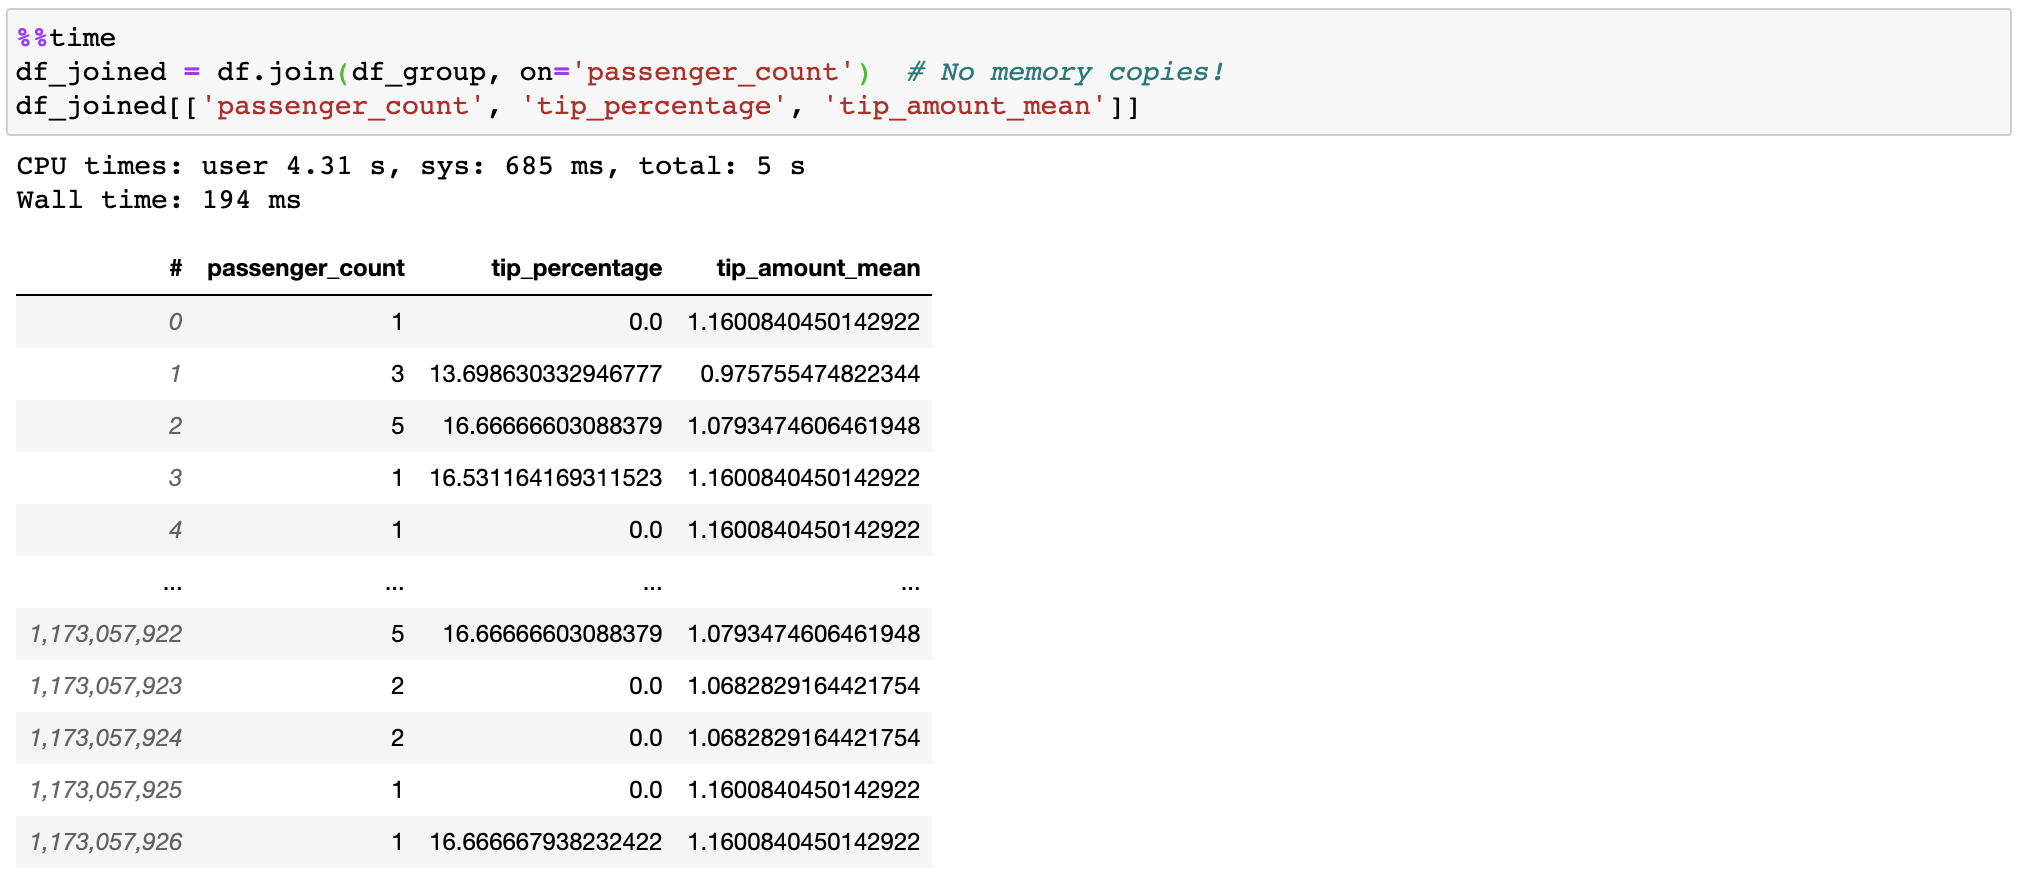
- Fast and efficient join
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 6 days ago
- Stars
- 8,518
- +3 this week
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest tag
- vaexpaper_v1
- Released 8 years ago
- Built with
- Python
- 61% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 64% closed
- 447 still open
- Pull requests
- 816 merged
- 102 waiting
- Releases
- 4
- 0 in the last year
- Contributing guide (opens in new tab)
- Security policy (opens in new tab)
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| jtablesaw / tablesaw | 3,768 | 4 days ago | Apache-2.0 | No downloads |
| pytorch-tabular / pytorch_tabular | 1,698 | 56 days ago | MIT | No downloads |
| haifengl / smile | 6,430 | 2 days ago | Custom | No downloads |
More: languages, topics and project record
Languages
- Python 61%
- JavaScript 24%
- C++ 10%
- HTML 3%
Topics
- dataframe
- python
- bigdata
- tabular-data
- visualization
- memory-mapped-file
- hdf5
- machine-learning
- machinelearning
- data-science
- pyarrow
Project record
- JobOther AI tools
- StatusListed
- Commits3,769
- Forks600
- Watching136
- Stars in 28 days+6
- CreatedSep 27, 2014
- First seen by usNov 7, 2026
- CheckedNov 8, 2026