
worldbench / awesome-vla-for-ad
🌐 Vision-Language-Action Models for Autonomous Driving: Past, Present, and Future
Why this job: name: awesome; topics: awesome-list
What it does
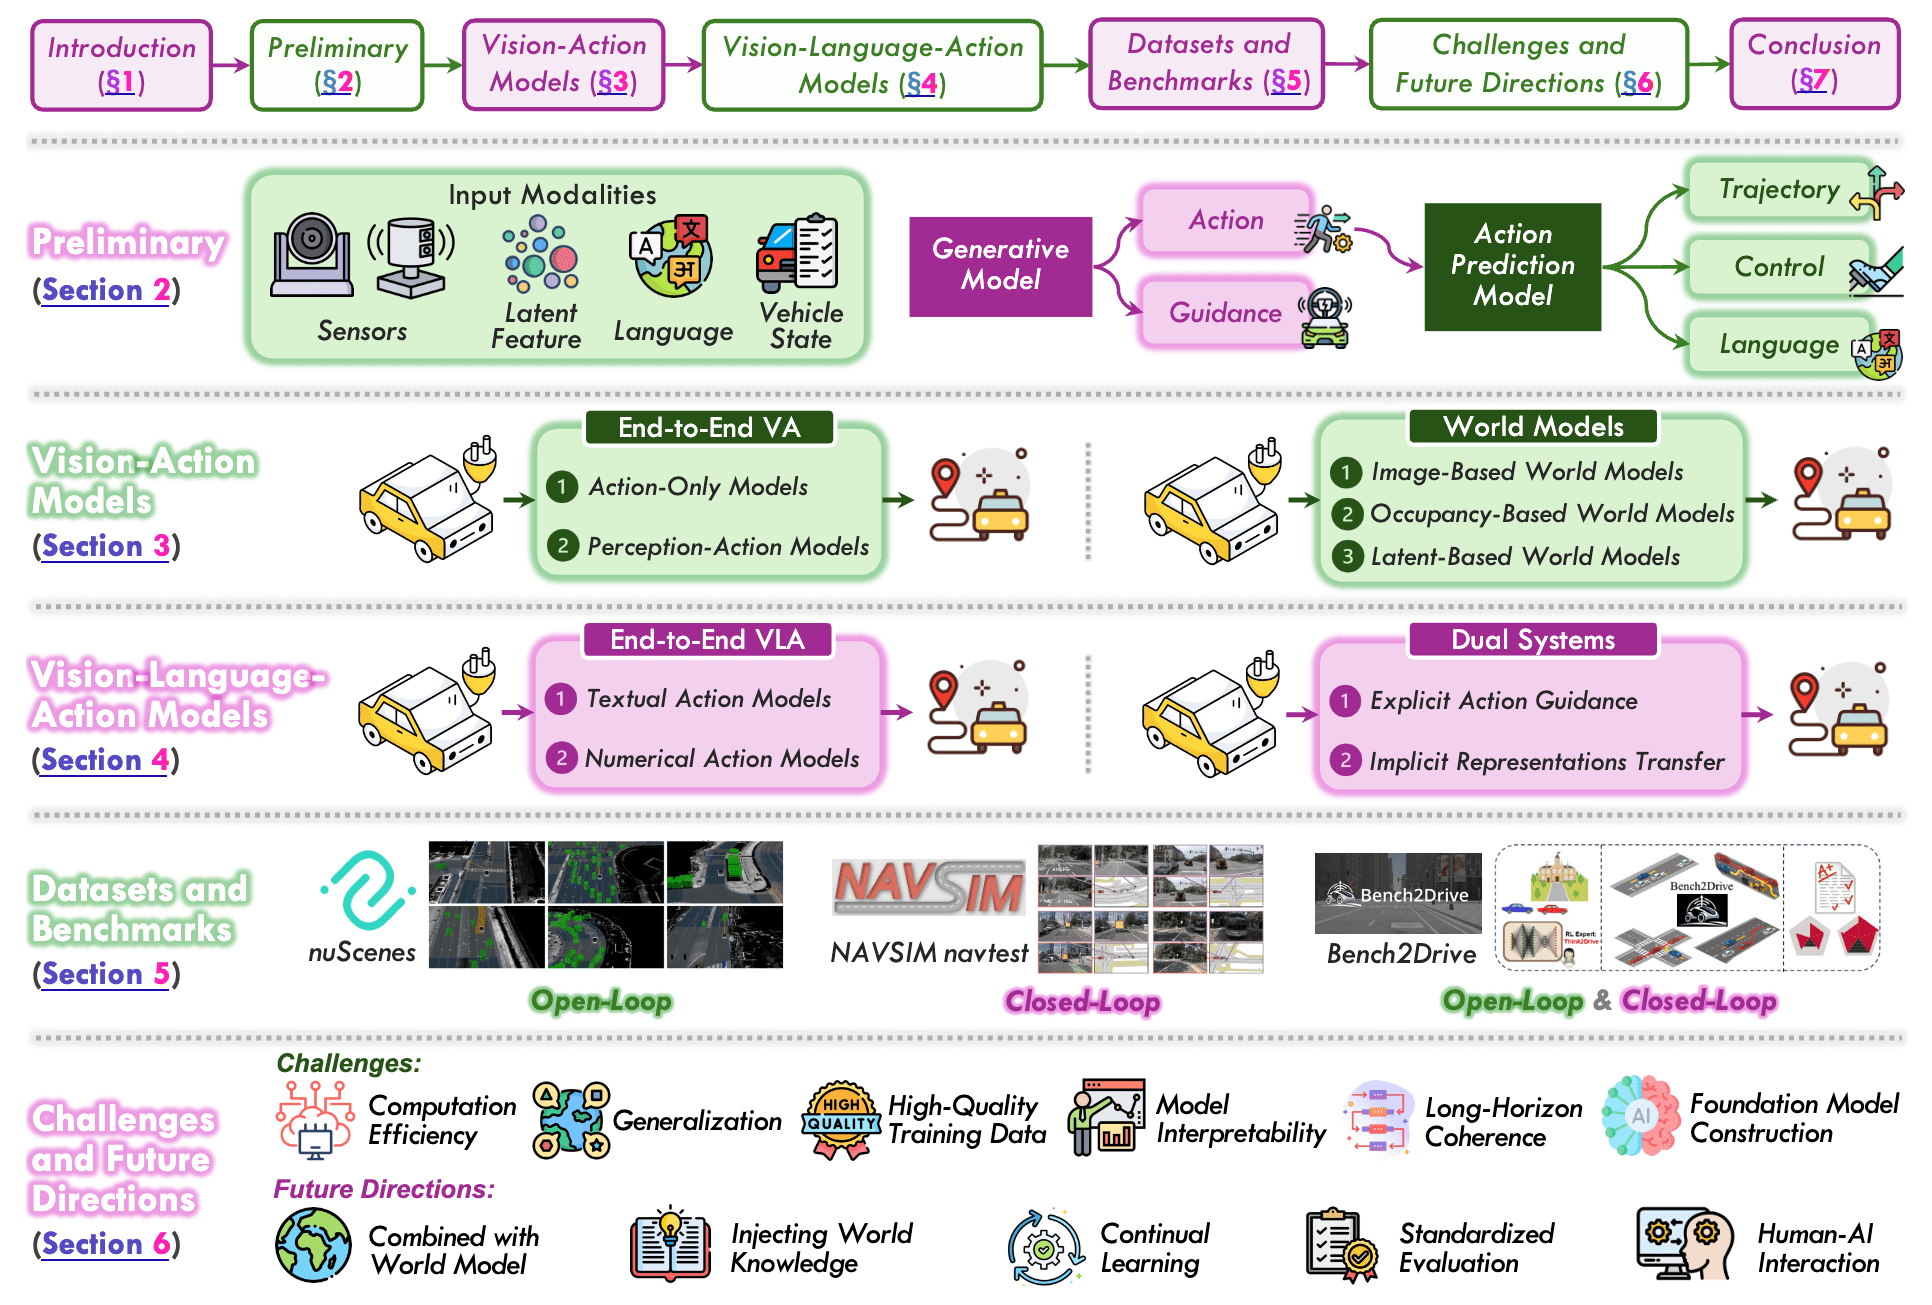
Autonomous driving has long relied on modular "Perception-Decision-Action" pipelines, whose hand-crafted interfaces and rule-based components often struggle in complex, dynamic, or long-tailed scenarios. Their cascaded structure also amplifies upstream perception errors, undermining downstream planning and control.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 3 days ago
- Stars
- 524
- On GitHub
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- HTML
- 100% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 100% closed
- 0 still open
- Pull requests
- 41 merged
- 1 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| sou350121 / VLA-Handbook | 762 | today | CC-BY-4.0 | No downloads |
More: languages, topics and project record
Languages
- HTML 100%
Topics
- autonomous-driving
- embodied-ai
- large-language-models
- multimodal-large-language-models
- vision-language-action
- vision-language-models
- llm
- vla
- vlm
- awesome-list
- multi-modal
- self-driving
Project record
- JobLists and guides
- StatusListed
- Commits103
- Forks60
- Watching17
- Stars in 28 days+31
- CreatedSep 7, 2025
- First seen by usNov 7, 2026
- CheckedNov 8, 2026