
yalun753 / moe-l2
MoE expert offload for low-VRAM GPUs — run 100B+ MoE models (DeepSeek, Qwen, Mixtral) on 8 GB cards. Expert cache with LRU hot experts, OpenAI-compatible proxy, GGUF multi-shard.
Why this job: says: gguf; topics: llama-cpp, llm-inference
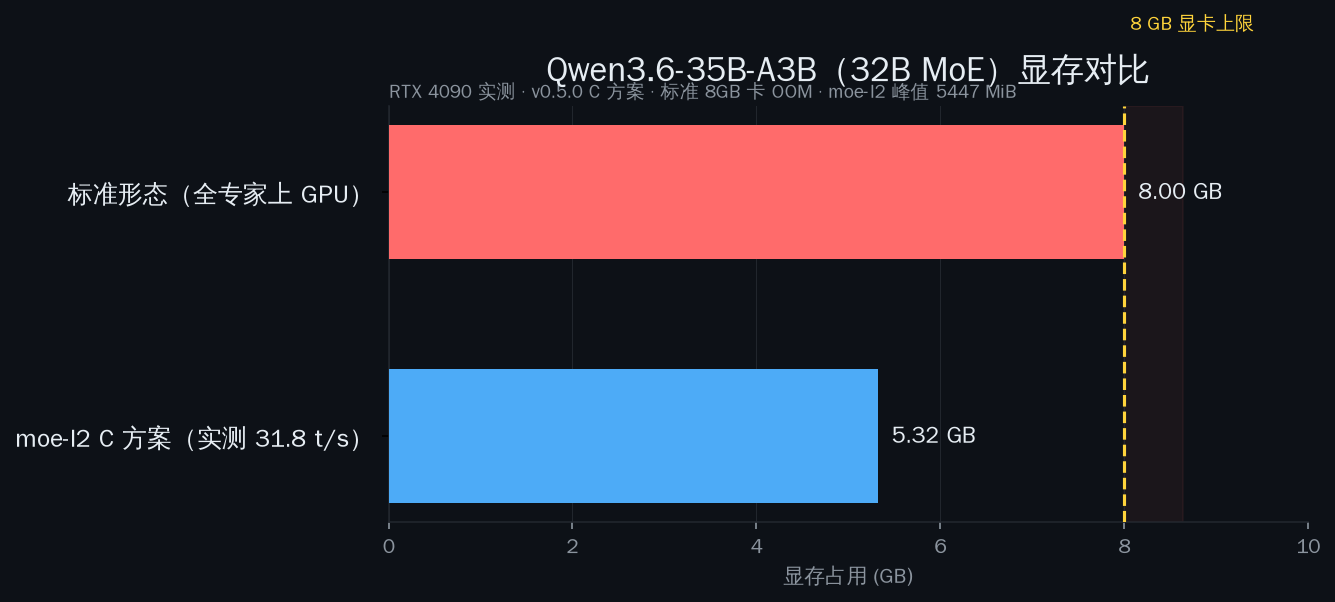
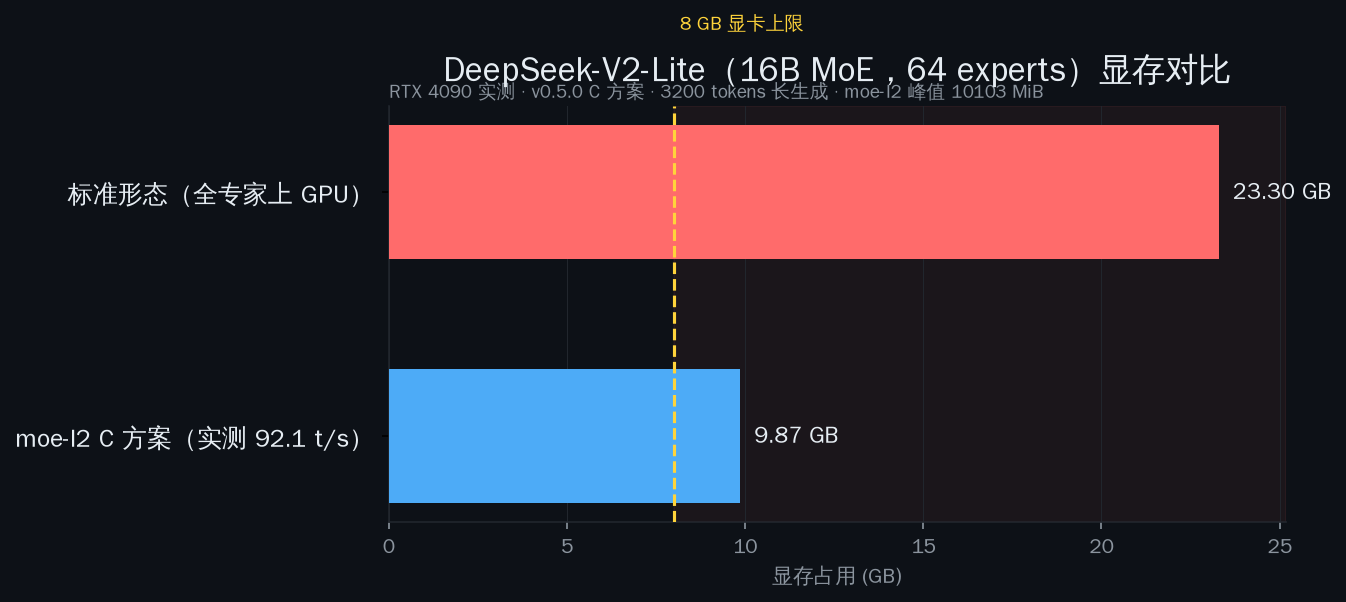
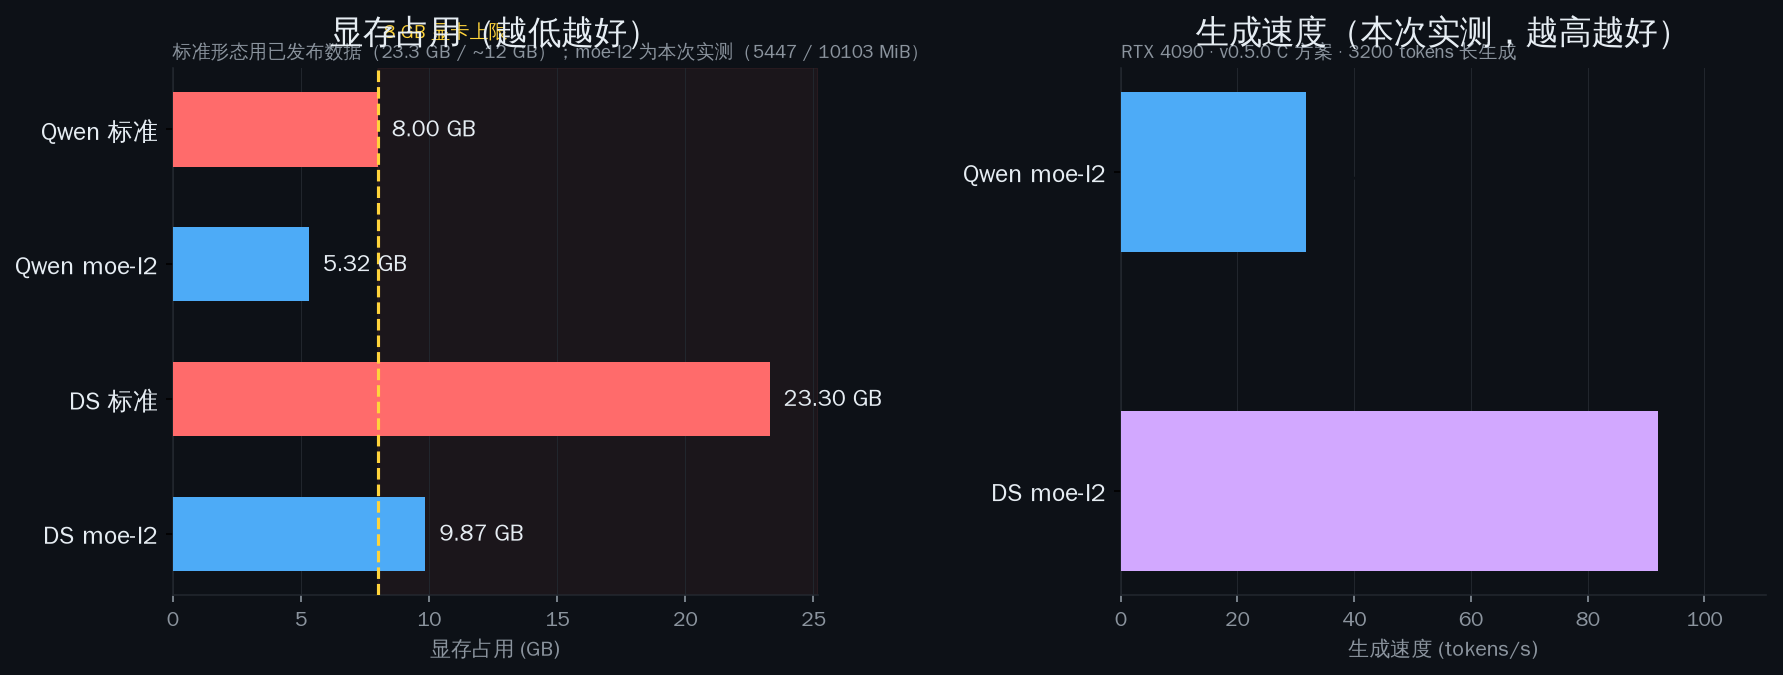
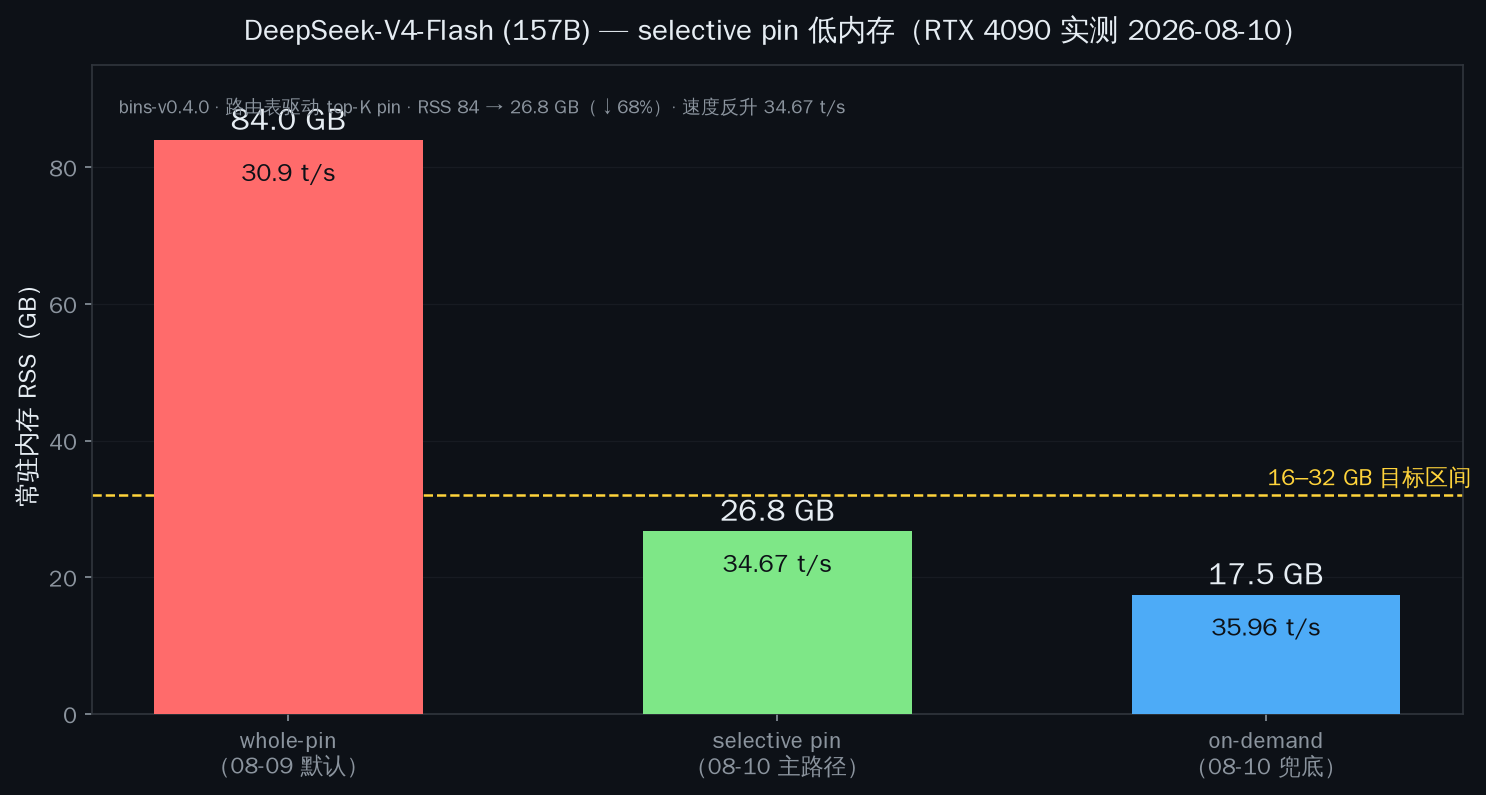
Get started
curl -fsSL https://raw.githubusercontent.com/yalun753/moe-l2/main/scripts/install.sh | bash You need: Linux x86_64 + NVIDIA GPU — primary platform (CUDA .so + llama-server bundle); Windows 10/11 x64 + NVIDIA GPU — native support since bins-v0.8.0 (llama_bins_win.zip, llama-server.exe + DLLs; same A3 expert cache / router-map features as Linux); macOS, and ARM Linux are not supported
- Maintenance
- Active
- Last commit 40 days ago
- Stars
- 146
- +1 this week
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest tag
- bins-v0.8.1
- Released 40 days ago
- Built with
- Cuda
- 41% of the code
Is it looked after?
- Contributors
- 0
- Last 90 days
- Issues
- 50% closed
- 1 still open
- Pull requests
- 0 merged
- 1 waiting
- Releases
- 15
- 15 in the last year
- Contributing guide (opens in new tab)
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| syv-ai / HyperQwen | 2,639 | today | Apache-2.0 | No downloads |
| mw00 / project-maya | 2,741 | yesterday | MIT | No downloads |
| kacper-daftcode / vLLM-Moet | 571 | today | Apache-2.0 | No downloads |
More: languages, topics and project record
Languages
- Cuda 41%
- Python 35%
- C++ 23%
- Shell 1%
Topics
- consumer-gpu
- deepseek
- expert-caching
- llama-cpp
- llm-inference
- moe
- vram-optimization
Project record
- JobLocal LLMs
- StatusListed
- Commits186
- Forks6
- Watching1
- Stars in 28 days+5
- CreatedJul 26, 2026
- First seen by usNov 7, 2026
- CheckedNov 7, 2026