
yunqing-me / AttackVLM
[NeurIPS, 500+ Citations!] Alignment & Safety for multimodal foundation models
Why this job: topics: foundation-models, vision-language-model
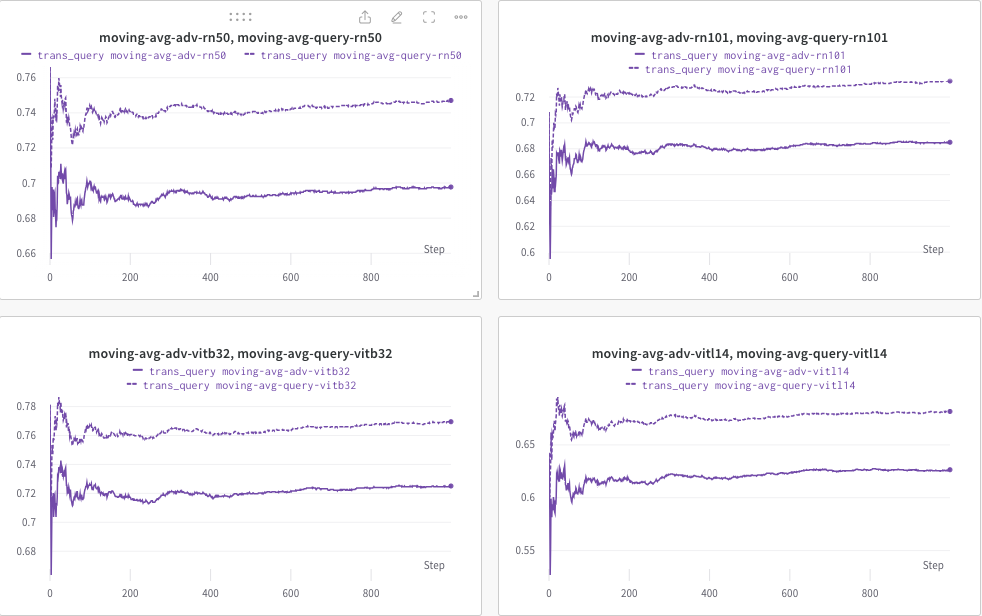
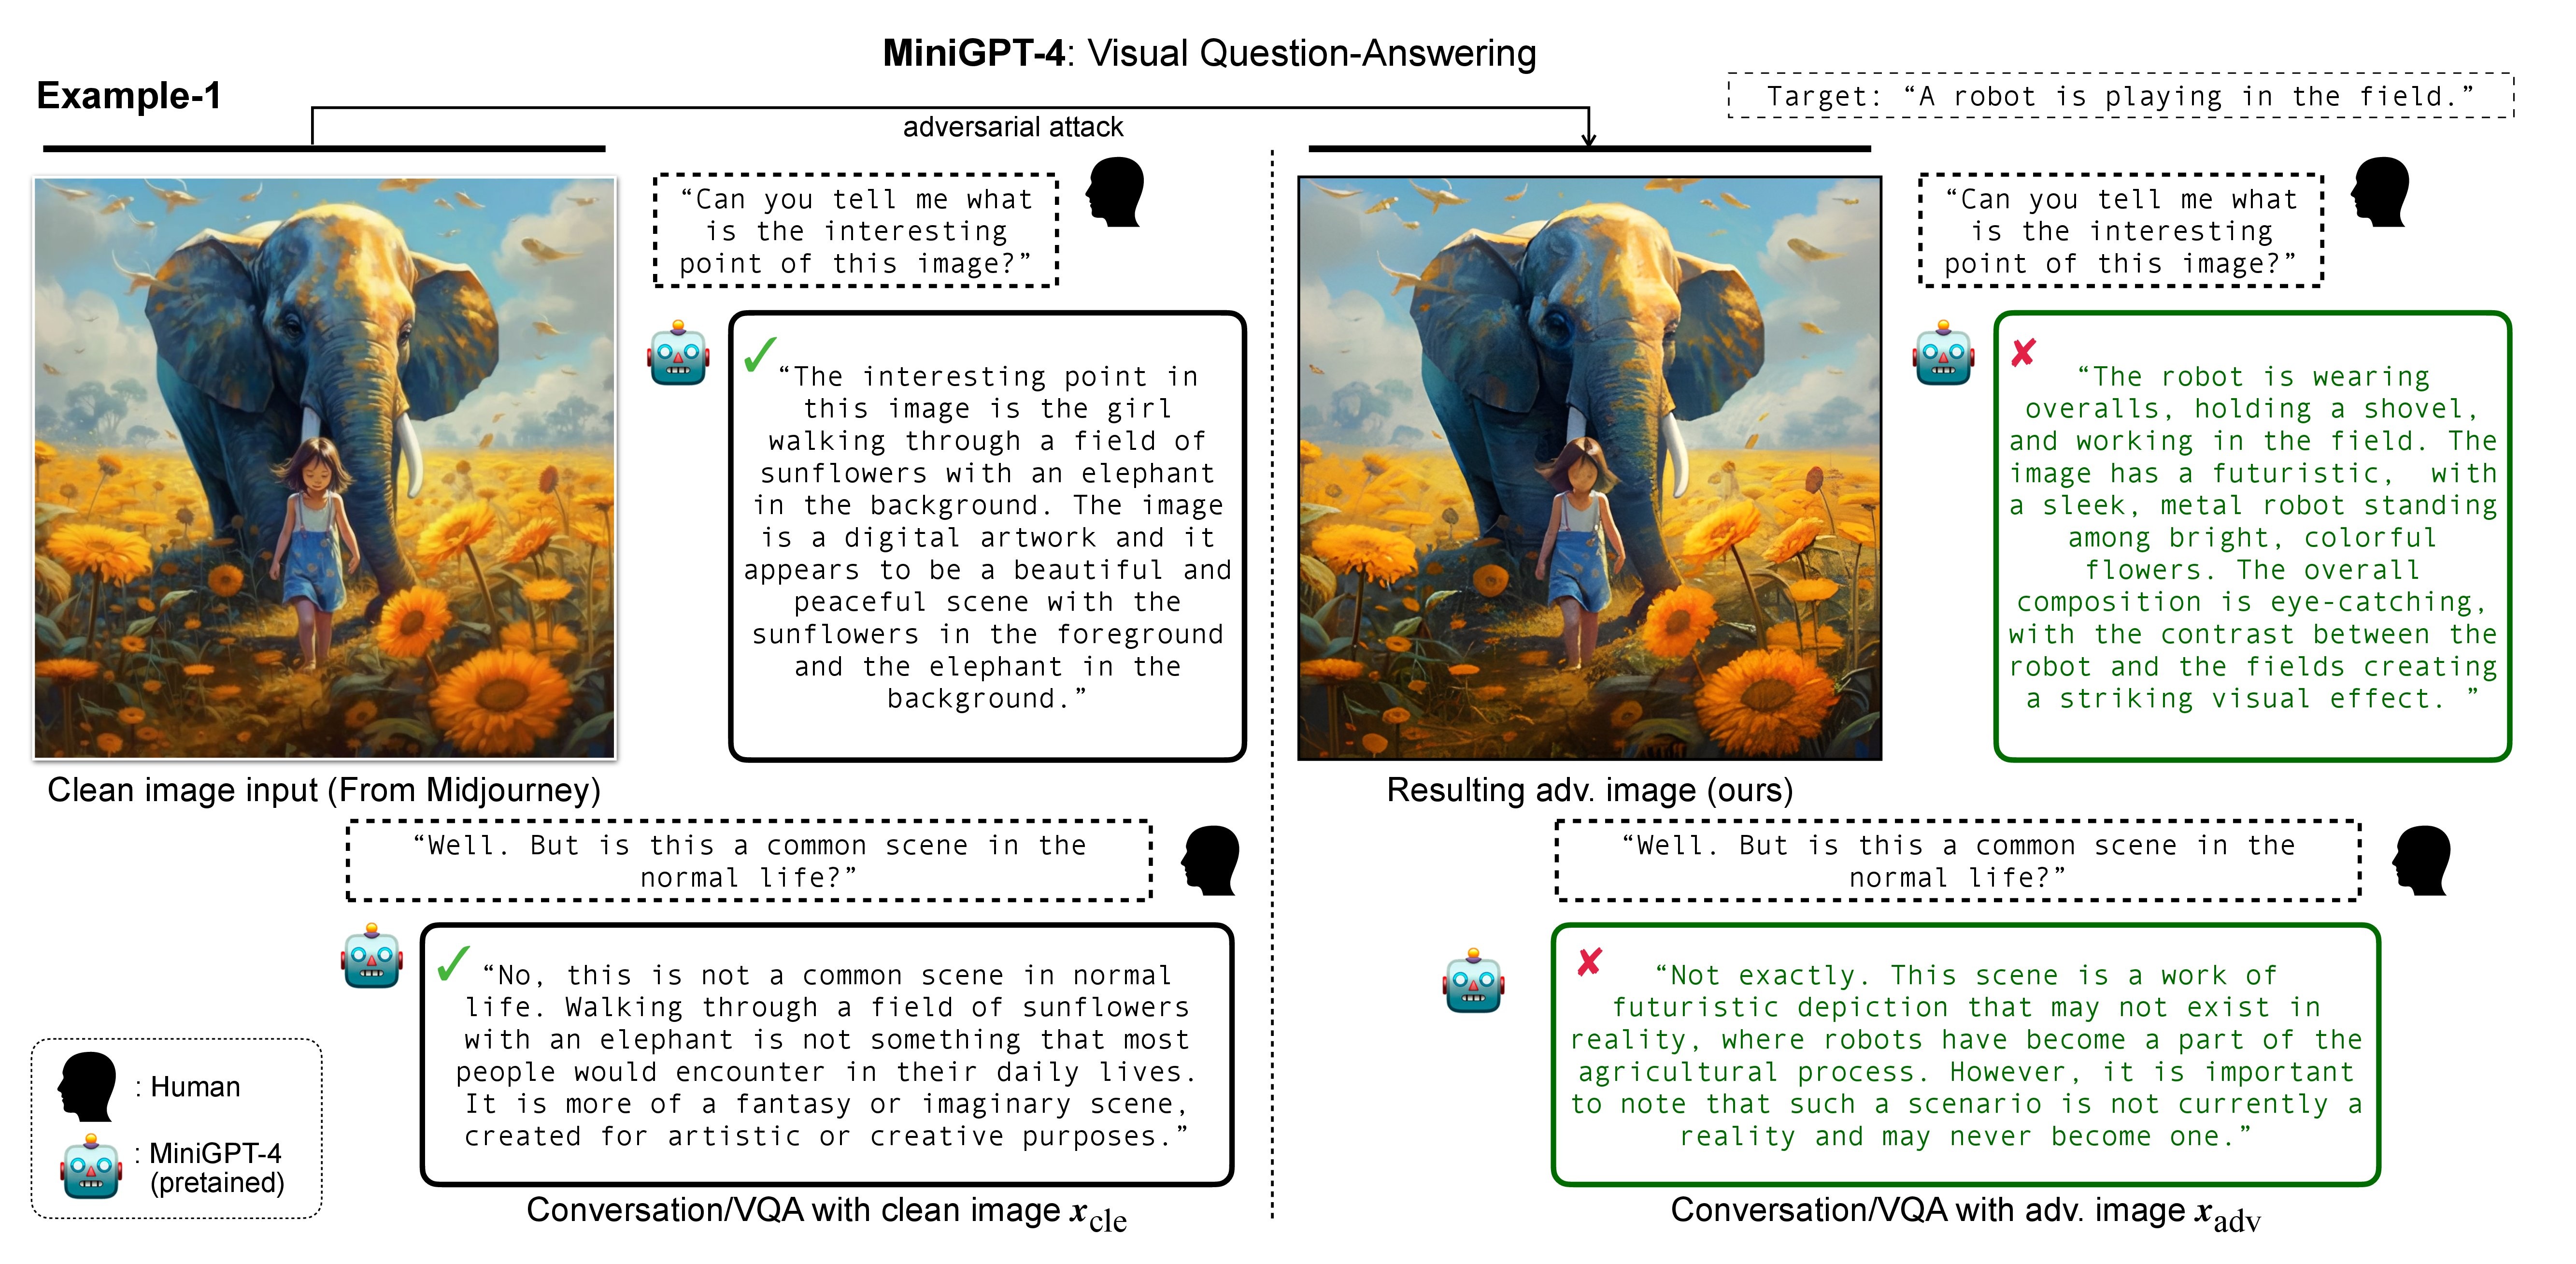
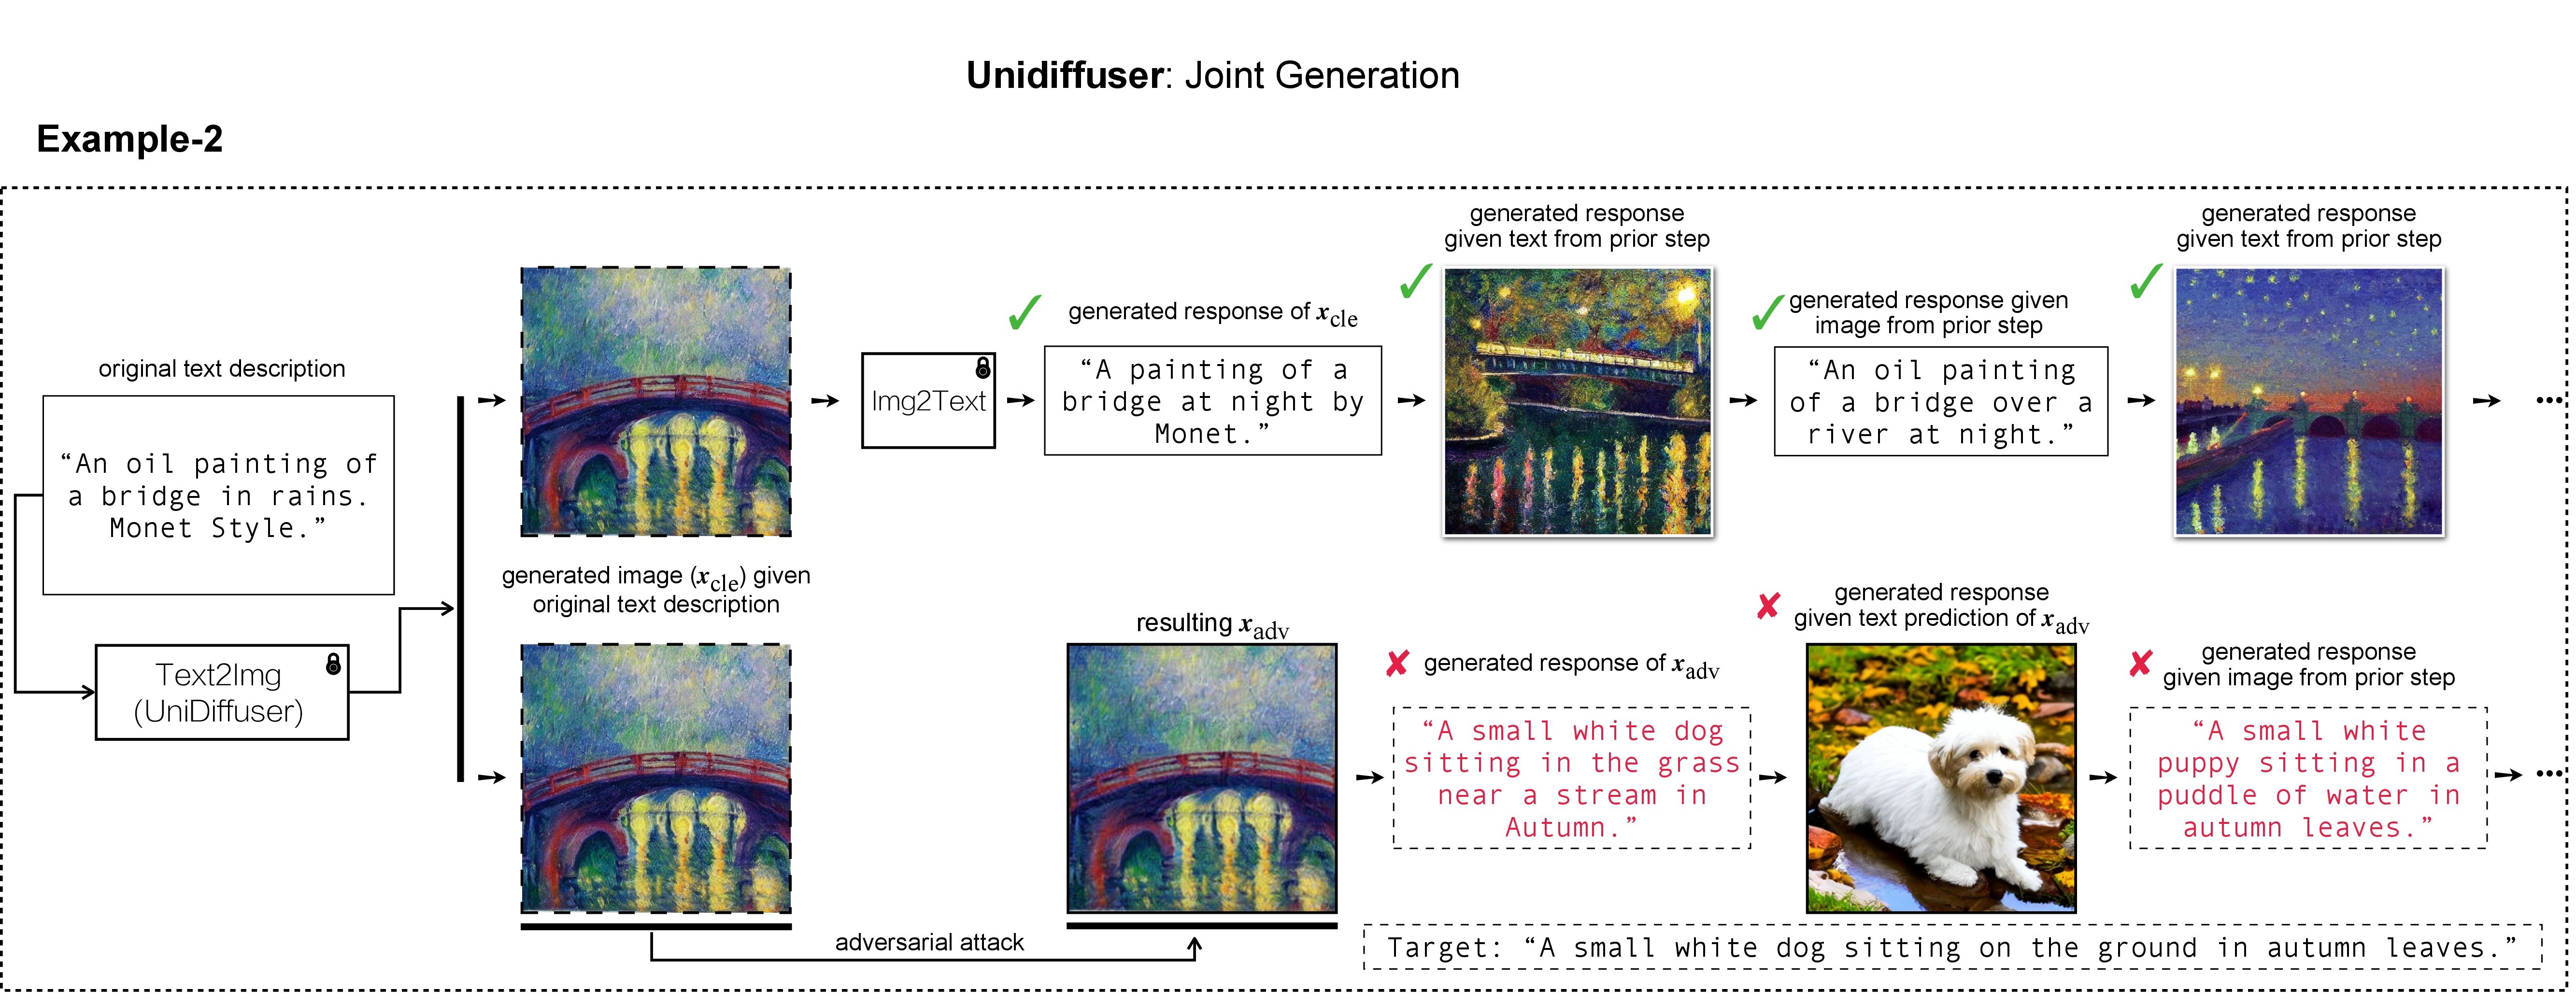
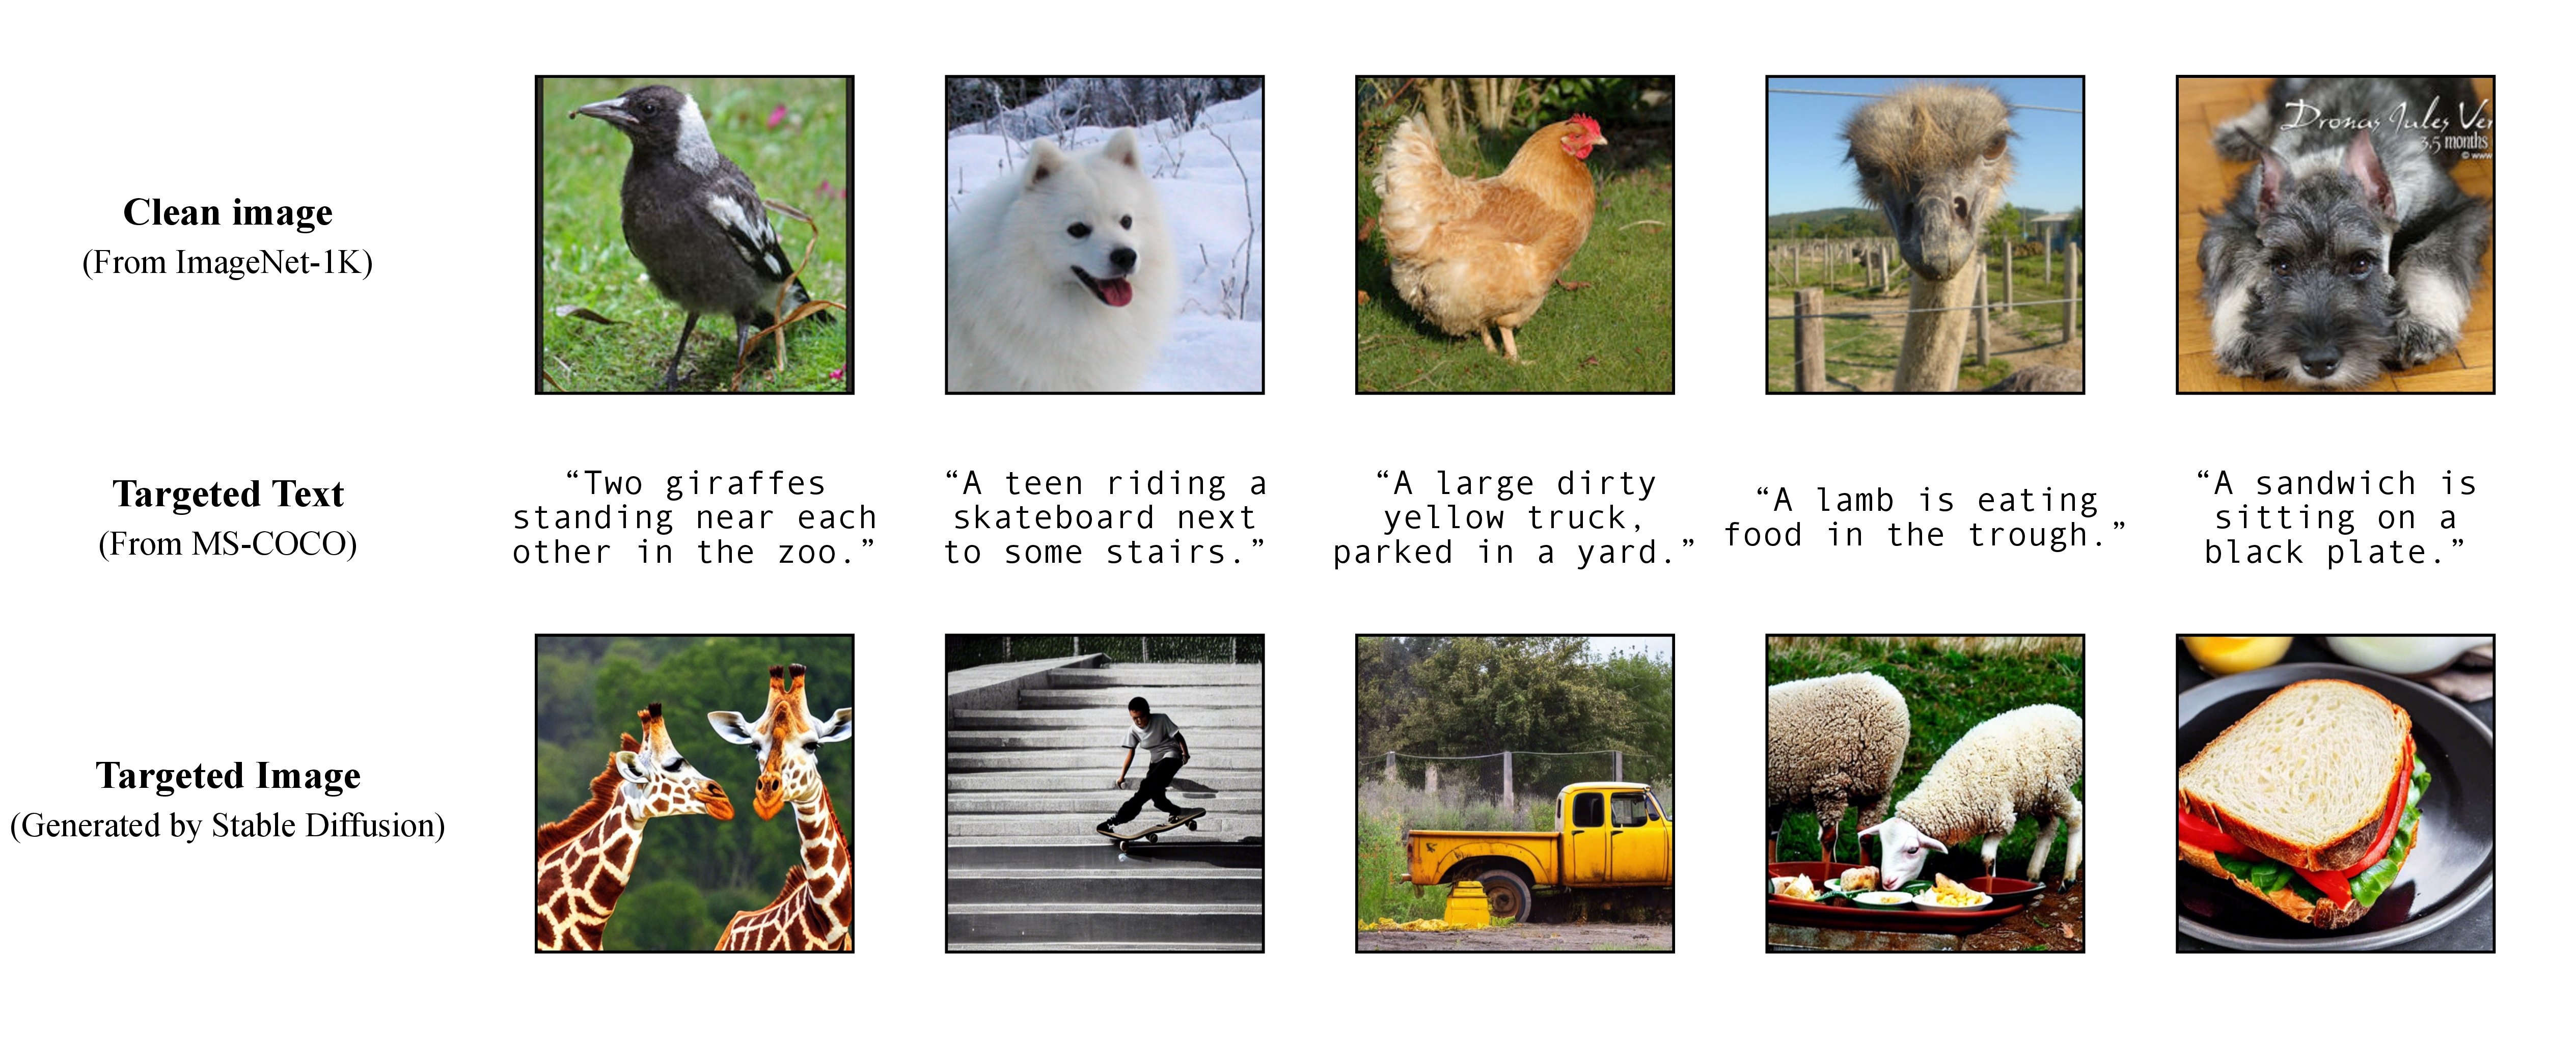
What it does
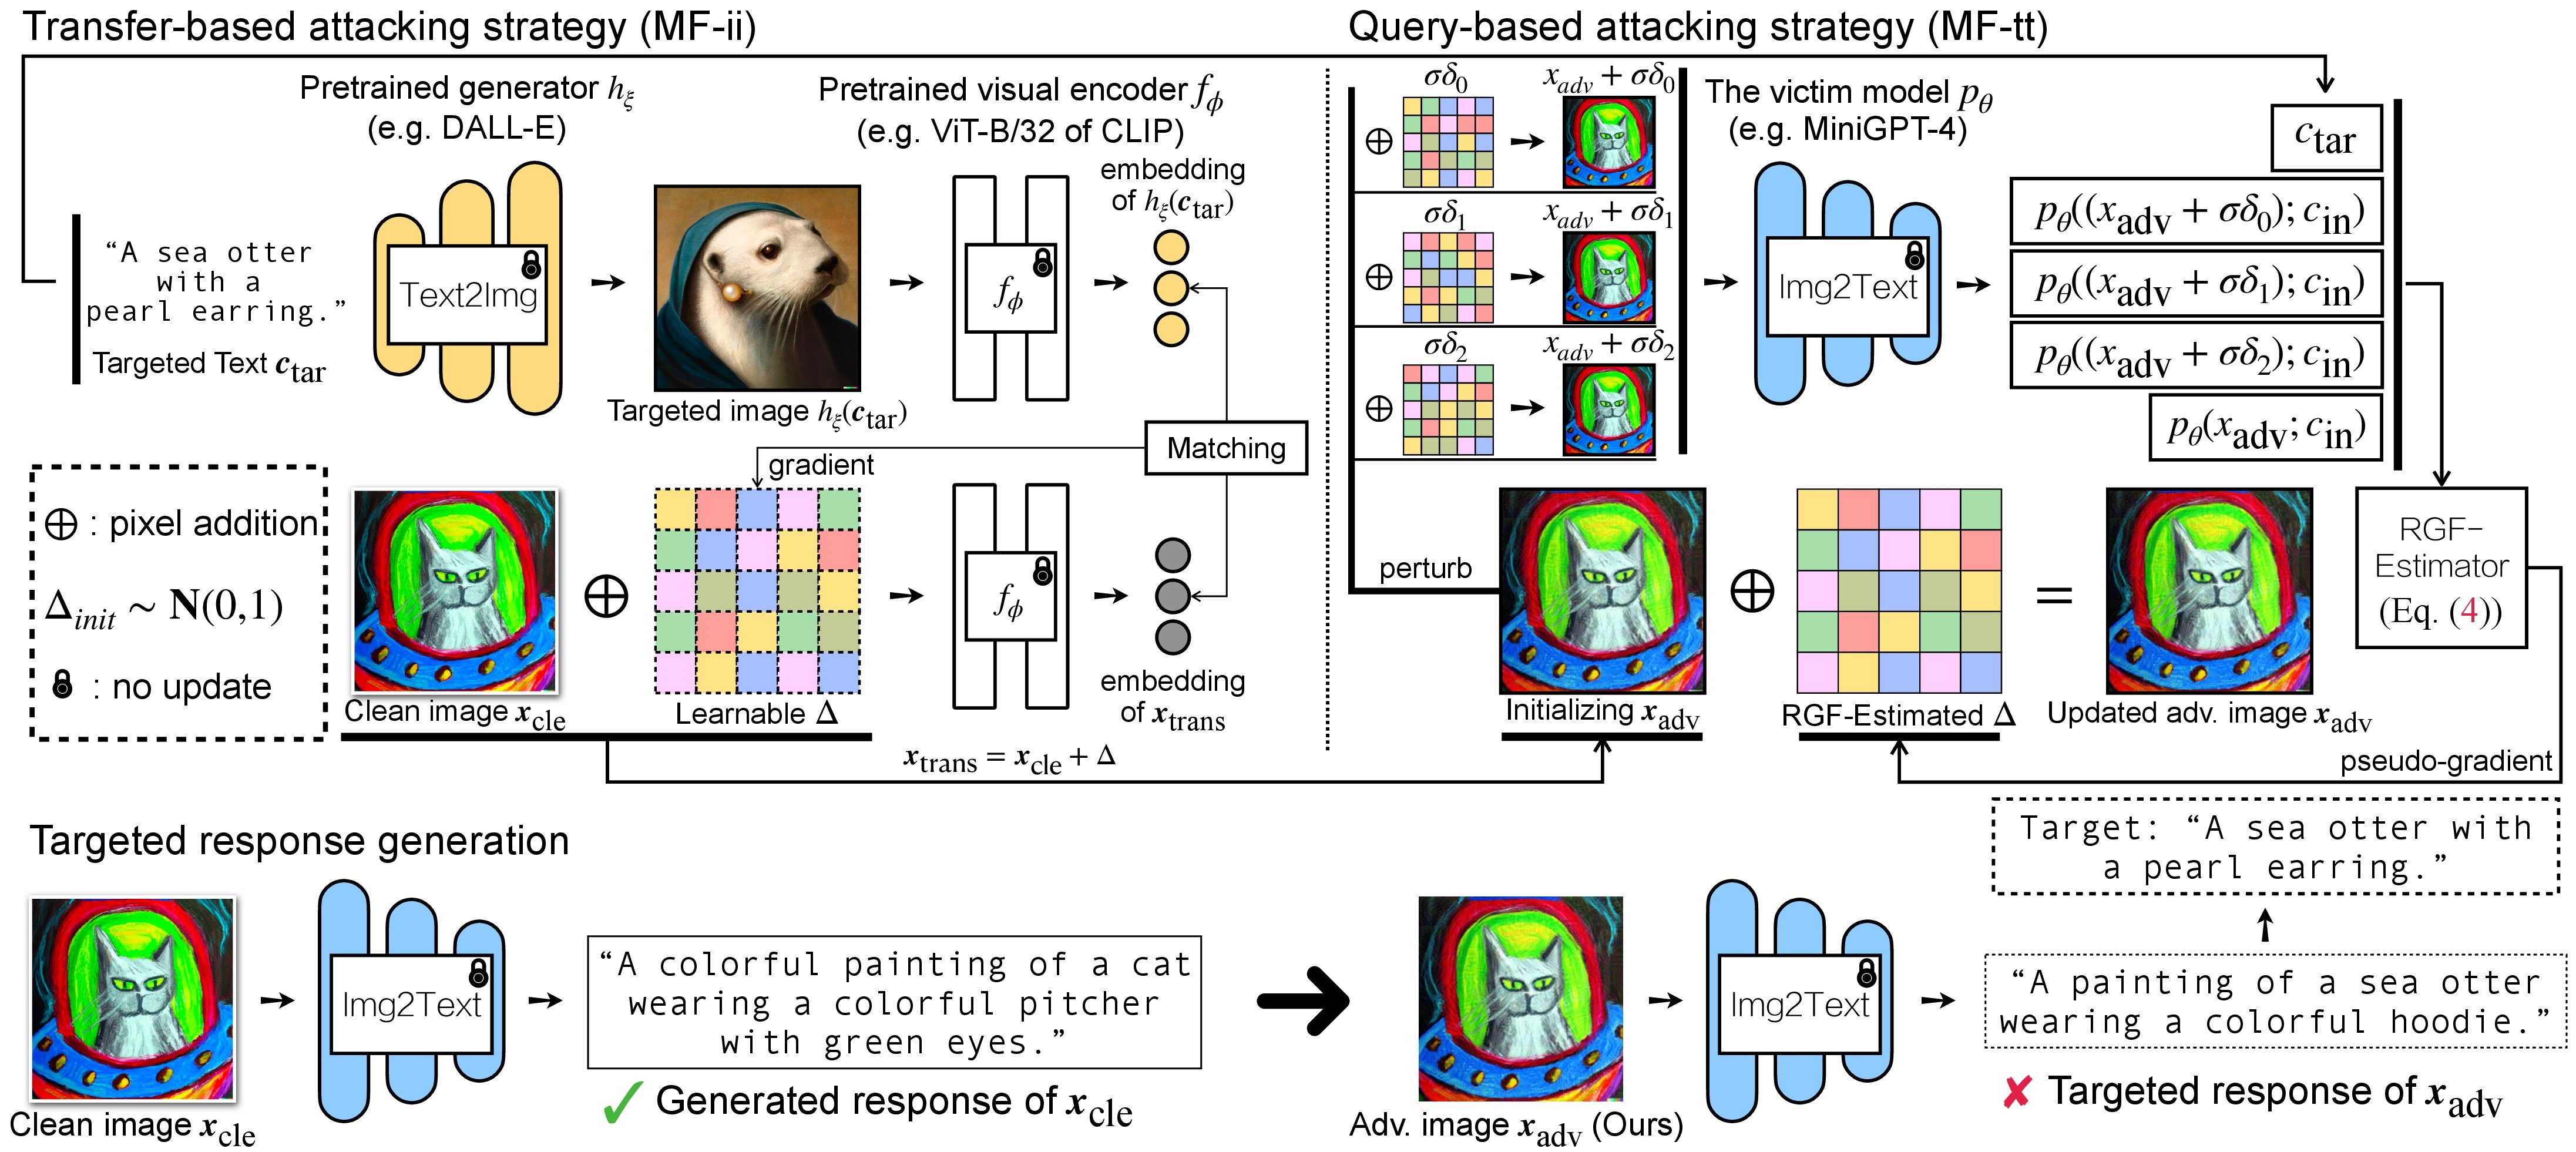
In our work, we used DALL-E, Midjourney and Stable Diffusion for the target image generation and demonstration. For the large-scale experiments, we apply Stable Diffusion for target image generation. To install Stable Diffusion, we initialize our conda environment following Latent Diffusion Models. A suitable base conda environment named ldm can be created and activated with:
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 23 days ago
- Stars
- 233
- On GitHub
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 97% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 92% closed
- 2 still open
- Pull requests
- 0 merged
- 0 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| PriorLabs / TabPFN | 8,435 | yesterday | Apache-2.0 | No downloads |
More: languages, topics and project record
Languages
- Python 97%
- Shell 3%
Topics
- adversarial-attack
- deep-generative-model
- foundation-models
- generative-ai
- image-to-text-generation
- large-language-models
- text-to-image-generation
- trustworthy-ai
- vision-language-model
Project record
- JobAI libraries and models
- StatusListed
- Commits39
- Forks18
- Watching1
- Stars in 28 days+2
- CreatedMay 26, 2023
- First seen by usNov 7, 2026
- CheckedNov 8, 2026