
ZhuLinsen / LiteMoE
A MoE inference engine you can read in an afternoon.
Why this job: says: inference engine; topics: vllm, inference
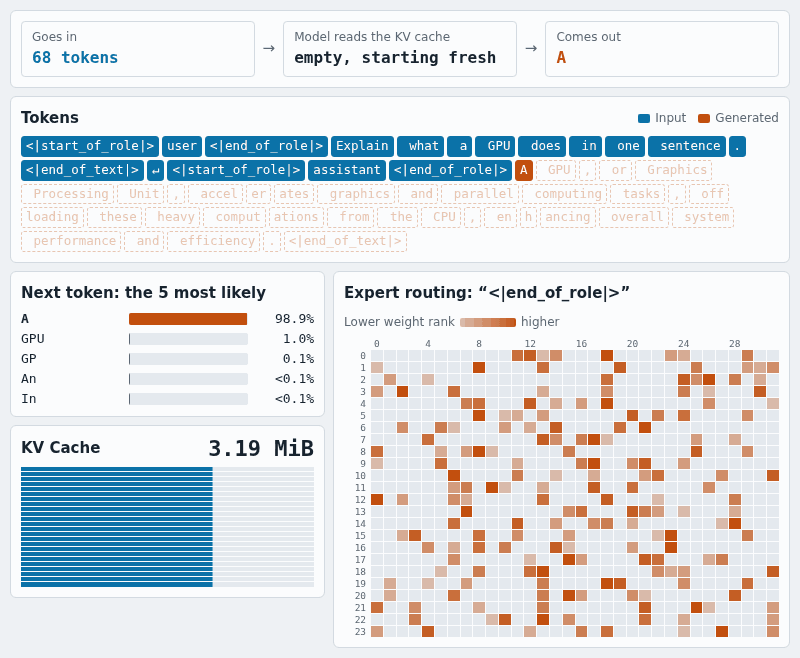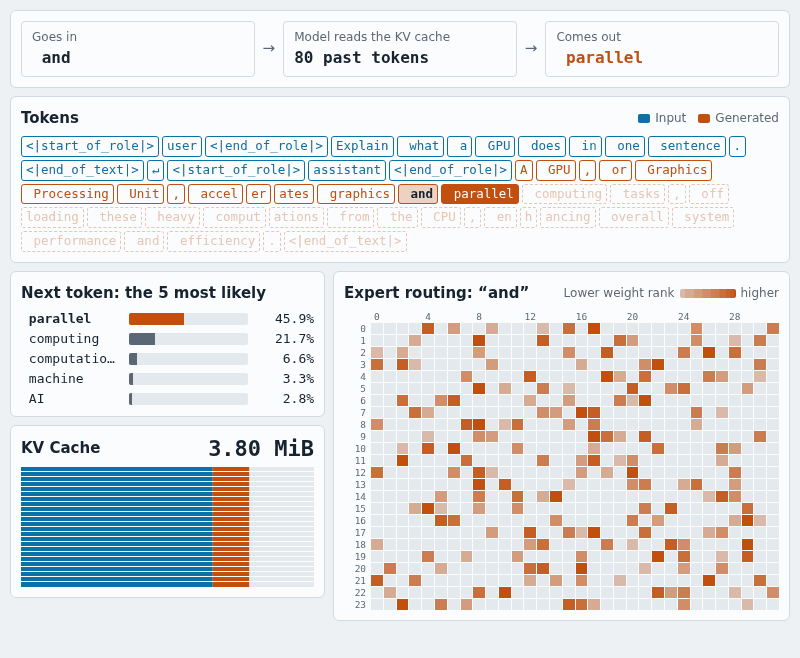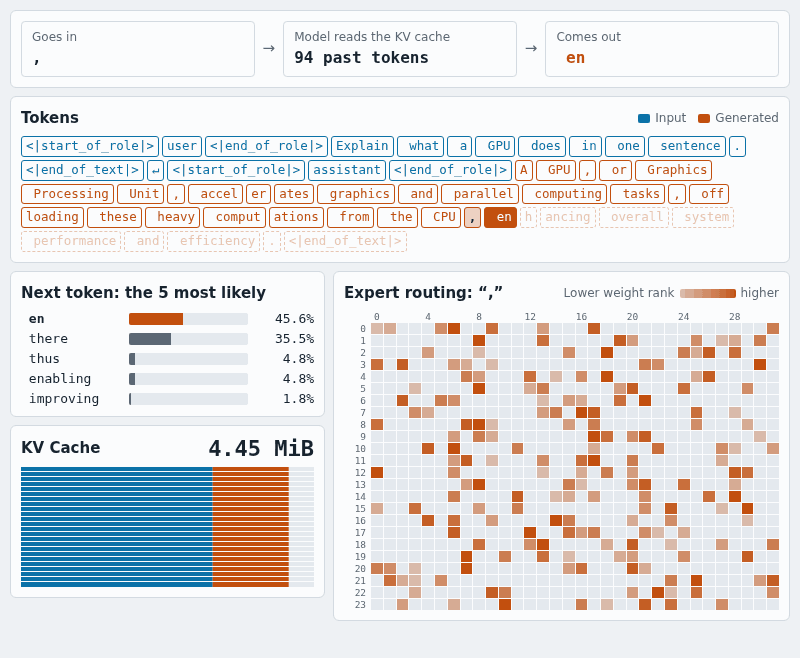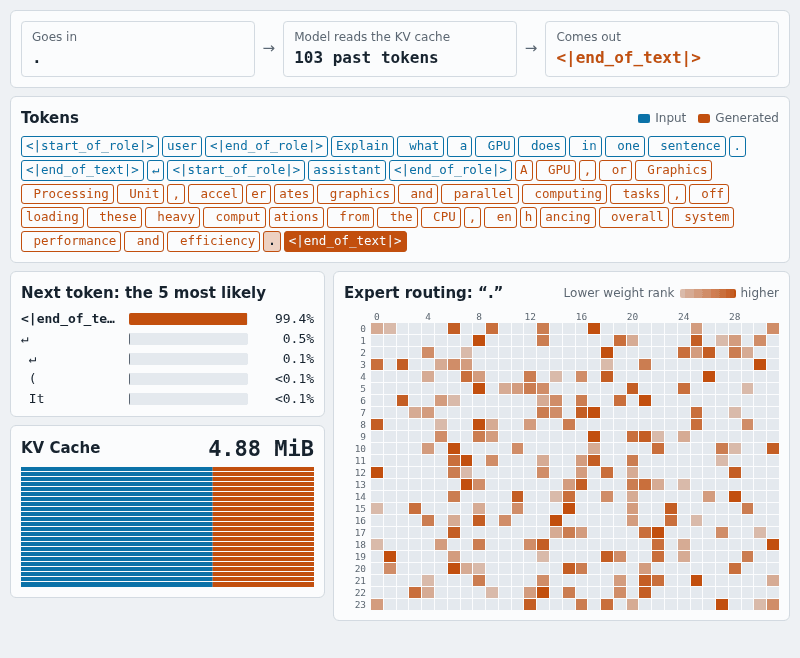
What it does
Most of the gain comes from removing work that can't affect live requests: per-layer masks, index lookups and output copies in Decode. Whole Decode steps run as a CUDA Graph.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 6 days ago
- Stars
- 29
- +19 this week
- Licence
- Apache-2.0
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 99% of the code
Is it looked after?
- Contributors
- 1
- Last 90 days
- Issues
- None
- No issues filed
- Pull requests
- 6 merged
- 0 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| triton-inference-server / server | 11,134 | 4 days ago | BSD-3-Clause | Linux |
| bojieli / ai-infra-book | 7,406 | 39 days ago | Apache-2.0 | No downloads |
| microsoft / vidur | 721 | 2 months ago | MIT | No downloads |
More: languages, topics and project record
Languages
- Python 99%
- Shell 1%
Topics
- gpu
- inference
- llm
- mixture-of-experts
- vllm
Project record
- JobLocal LLMs
- StatusNew to our list
- Commits11
- Forks2
- Watching2
- CreatedNov 1, 2026
- First seen by usNov 7, 2026
- CheckedNov 9, 2026