
ziqipang / LM4VisualEncoding
[ICLR 2024 (Spotlight)] "Frozen Transformers in Language Models are Effective Visual Encoder Layers"
Why this job: works in the areas we cover, but does not say which job it does
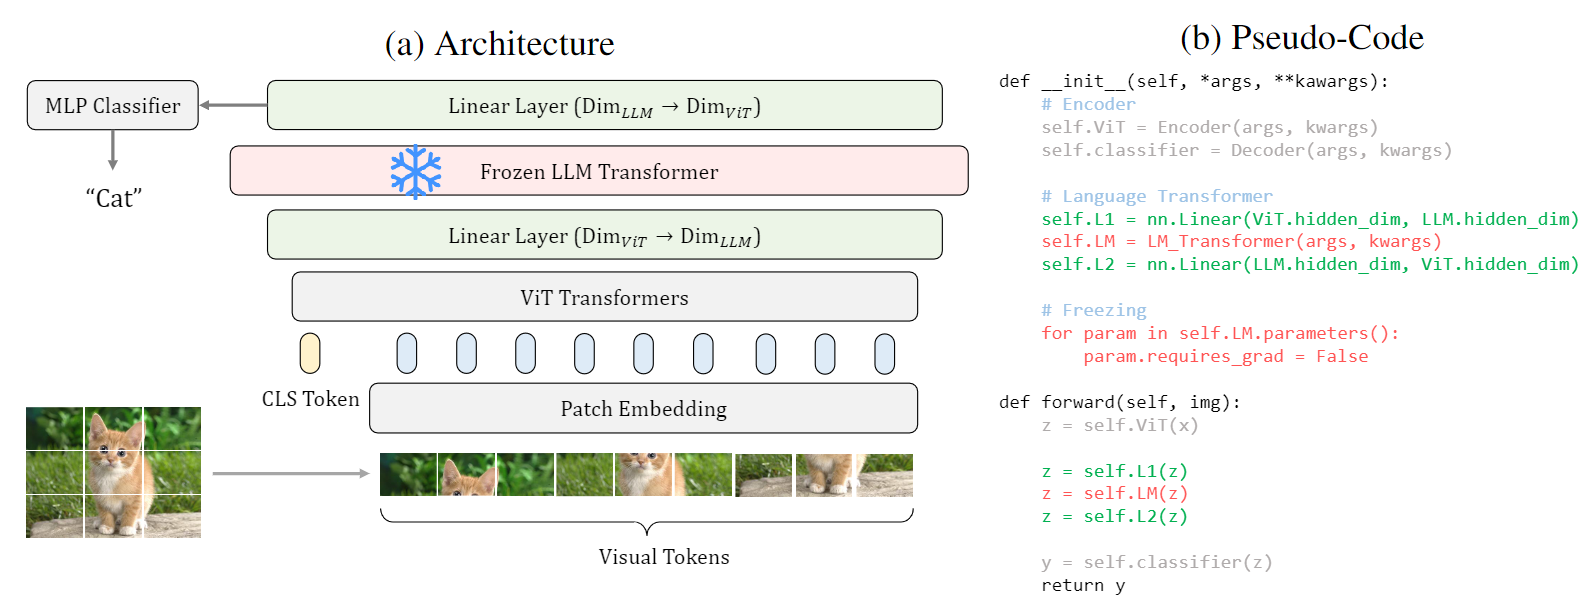
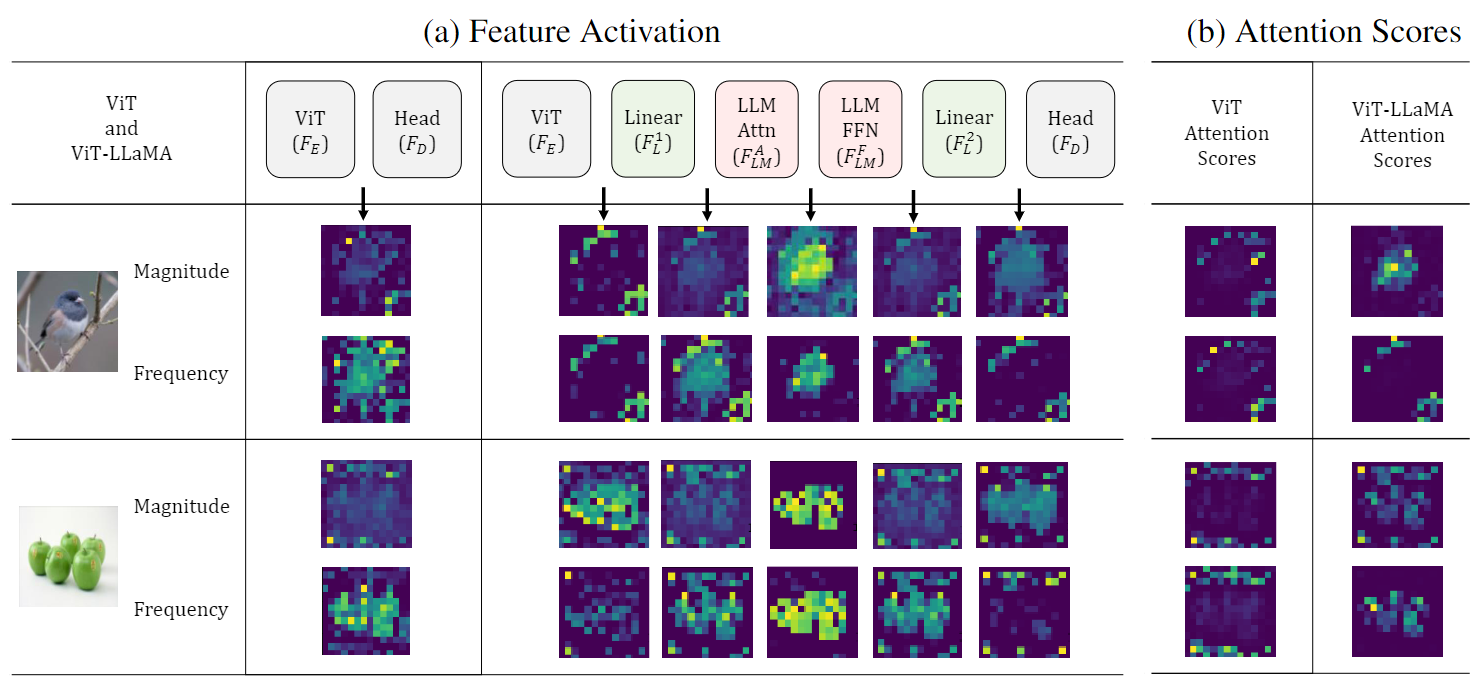
What it does
This paper reveals an intriguing discovery: pretrained transformers from LLMs, despite being trained solely on textual data, are *surprisingly* strong encoders for *purely* visual tasks in the absence of language. Our exploration shows the potential of LLMs as general-purpose *encoders* for *visual* data, as opposed to the previous usages of either pure *encoders* for text embeddings or *decoders* for tokenized outputs.
Get started
No single install command. Read the steps in the README (opens in new tab)
- Maintenance
- Active
- Last commit 4 months ago
- Stars
- 247
- +1 this week
- Licence
- MIT
- Allows business use
- Downloads for
- None listed
- No release files
- Latest version
- None yet
- No releases
- Built with
- Python
- 95% of the code
Is it looked after?
- Contributors
- Not stated
- Last 90 days
- Issues
- 60% closed
- 4 still open
- Pull requests
- 2 merged
- 0 waiting
- Releases
- None
- Never published
- No contributing guide
- No security policy
- No code of conduct
Similar repos
| Repo | Stars | Last commit | Licence | Downloads for |
|---|---|---|---|---|
| LAMDA-CL / LAMDA-PILOT | 613 | 9 months ago | MIT | No downloads |
| sotopia-lab / sotopia | 343 | 10 months ago | MIT | No downloads |
More: languages, topics and project record
Languages
- Python 95%
- Cuda 4%
- Shell 1%
- C++ <1%
Topics
- llm
- vision-transformer
Project record
- JobOther AI tools
- StatusListed
- Commits21
- Forks7
- Watching4
- Stars in 28 days+2
- CreatedOct 19, 2023
- First seen by usNov 7, 2026
- CheckedNov 8, 2026